Features and similarity search
Open in Colab · Download notebook
This notebook will guide you on how to extract embeddings / features from a pretrained model for similarity search.
Setup
# On Colab:
# !pip install "torch-pointcloud"
# !pip install torch-scatter torch-cluster -f https://data.pyg.org/whl/torch-2.10.0+cu128.html
import torch
import torch.nn.functional as F

import torch_pointcloud as tp

torch.manual_seed(0)
device = "cuda" if torch.cuda.is_available() else "cpu"
print("torch-pointcloud", tp.__version__, "| device:", device)
Reset the classifier
To extract features, you can either use the reset_classifier method to set num_classes=0 (or use the num_classes argument to create_model) or use the forward_features method directly. With num_classes=0 the head is an nn.Identity and forward returns features whose width is model.num_features.
model_clf = tp.create_model("pointnet2-ssg.modelnet40.xu-yan", task="classification", num_classes=0).eval()
model_seg = tp.create_model("pointnext-sm", task="segmentation", in_channels=4, num_classes=0).eval()

pos = torch.rand(8192, 3) * 4.0
x = torch.rand(8192, 4)
batch = torch.arange(2).repeat_interleave(4096)

with torch.no_grad():
    per_cloud = model_clf(None, pos, batch)
    per_point = model_seg(x, pos, batch)

print("per point:", tuple(per_point.shape), "| head:", type(model_seg.head).__name__, "| C:", model_seg.num_features)
print("per cloud:", tuple(per_cloud.shape), "| head:", type(model_clf.head).__name__, "| C:", model_clf.num_features)
Extract features
The next section extracts features from a room of the ScanNet20 validation set. ScanNet requires a signed agreement: request it on its download page and extract it under data/ScanNet/raw/.
import numpy as np


def load_sample():
    # Keep the per-point tensors of the first room; `color` is in 0-255
    return {key: value for key, value in scannet[0].items() if torch.is_tensor(value)}
data = load_sample()
print({key: tuple(value.shape) for key, value in data.items()})
# {'pos': (237360, 3), 'color': (237360, 3), 'normal': (237360, 3), 'segment': (237360,), 'instance': (237360,)}
from torch_pointcloud.utils.data import collate

model, info = tp.create_model(
    "concerto-large-lp.scannet20.pointcept",
    task="segmentation",
    pretrained=True,
    num_classes=0,
    return_info=True,
)
model = model.eval().to(device)

transform = info["transform"]

sample = load_sample()
data = collate([transform({key: value.clone() for key, value in sample.items()})])

with torch.inference_mode():
    features = model(data["x"].to(device), data["pos_grid"].to(device), data["batch"].to(device)).float()

print(f"{features.shape=}")
print(f"pos_grid.shape={data['pos_grid'].shape}")
print(f"origin_pos.shape={data['origin_pos'].shape}")
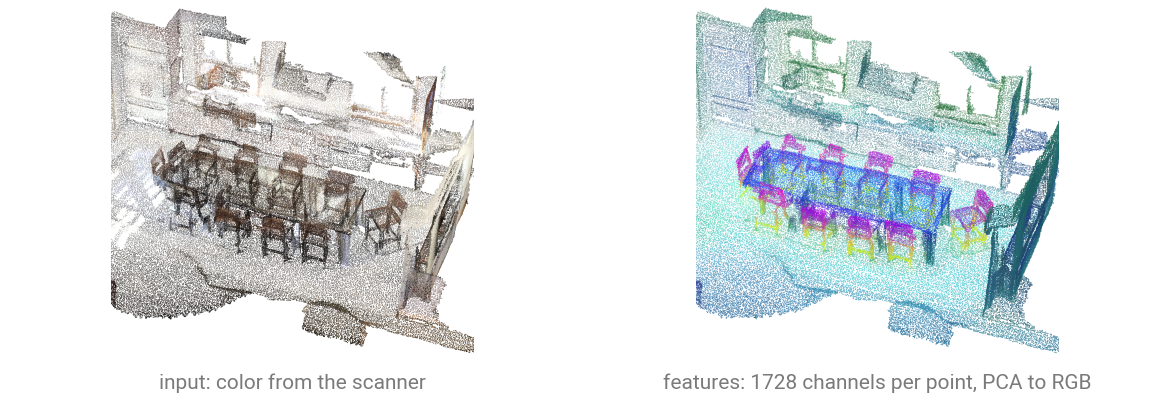
Note that this model voxelizes the input point cloud in place, so pos, x and segment hold one entry per voxel while the raw cloud stays under origin_pos / origin_segment. We will use the inverse key stored in the data dictionary to map each feature back to its original point.
def pca_color(feat: torch.Tensor) -> torch.Tensor:
    """Map a per-point feature (N, C) to RGB in [0, 1] through its top principal components."""
    _, _, components = torch.pca_lowrank(feat, center=True, q=6, niter=5)
    projected = feat @ components
    projected = projected[:, :3] * 0.6 + projected[:, 3:6] * 0.4
    low, high = projected.min(0, keepdim=True).values, projected.max(0, keepdim=True).values
    return ((projected - low) / (high - low).clamp_min(1e-6)).clamp(0, 1)


rgb = pca_color(features).cpu()  # matplotlib draws from host memory
print("rgb:", tuple(rgb.shape), "| range:", (float(rgb.min()), float(rgb.max())))
import matplotlib.pyplot as plt


def show_clouds(clouds, titles, point_size=1.0, columns=None, height=4.4):
    """Draw one cloud per panel, colored by its own `color`: RGB rows in [0, 1], or one color for the panel."""
    columns = columns or len(clouds)
    rows = -(-len(clouds) // columns)
    _, axes = plt.subplots(rows, columns, figsize=(4.4 * columns, height * rows), subplot_kw={"projection": "3d"})
    for ax, cloud, title in zip(np.ravel(axes), clouds, titles):
        pos = np.asarray(cloud["pos"])
        ax.scatter(*pos.T, c=cloud["color"], s=point_size, linewidths=0, depthshade=False)
        ax.set_box_aspect(np.ptp(pos, axis=0))
        ax.set_title(title, fontsize=10)
        ax.set_axis_off()
    plt.show()


show_clouds(
    [{"pos": sample["pos"], "color": sample["color"] / 255}, {"pos": data["origin_pos"], "color": rgb[data["inverse"]]}],
    ["input: color from the scanner", f"PCA of {features.shape[1]:,} features per point"],
    point_size=0.4,
)
Query a point
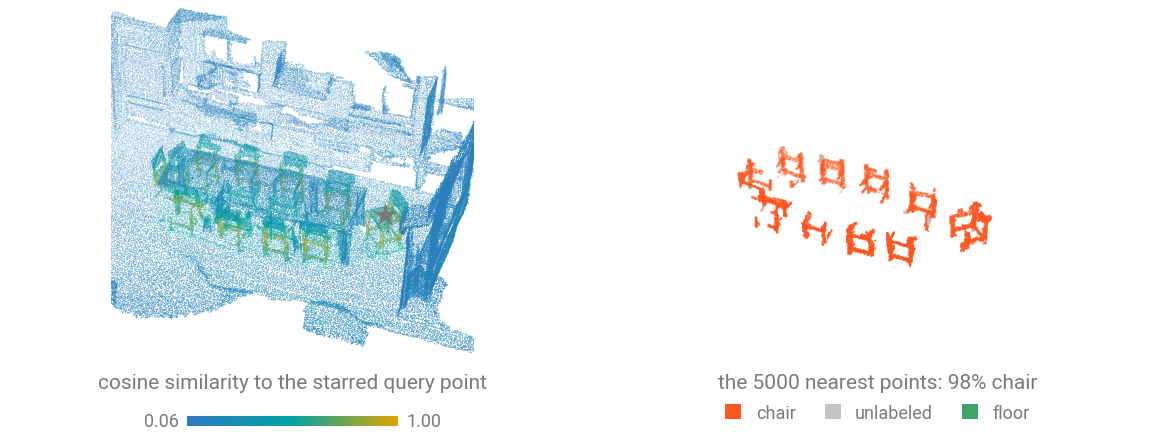
We can use the features of a point (or better, a region-of-interest) to search for similar points in the scene by measuring the cosine similarity between their features.
classes = list(info["weights"]["classes"])
segment = data["segment"].numpy()  # voxelized labels, used to score the answer and nothing else
normalized = F.normalize(features, dim=-1)  # unit rows, so a dot product is a cosine

chairs = np.where(segment == classes.index("chair"))[0]
query = int(chairs[len(chairs) // 2])  # a point in the middle of the class, not on its boundary
similarity = (normalized[query] @ normalized.t()).cpu()  # (N,) in [-1, 1]

print(f"query {query}: one of {len(chairs)} chair points")
print(f"similarity: min {float(similarity.min()):.2f}, mean {float(similarity.mean()):.2f}")
for k in (100, 1000, 5000):
    top = similarity.topk(k).indices.numpy()
    share = (segment[top] == classes.index("chair")).mean()
    print(f"top {k:>5}: {share:6.1%} chair, lowest cosine {float(similarity[top].min()):.2f}")

found, counts = np.unique(segment[similarity.topk(5000).indices.numpy()], return_counts=True)
print("top  5000:", {("unlabeled" if label < 0 else classes[label]): int(count) for label, count in zip(found, counts)})
query 105107: one of 23335 chair points
similarity: min 0.06, mean 0.21
top   100: 100.0% chair, lowest cosine 0.97
top  1000: 100.0% chair, lowest cosine 0.82
top  5000:  89.8% chair, lowest cosine 0.59
top  5000: {'unlabeled': 419, 'chair': 4492, 'table': 89}
top = similarity.topk(5000).indices.numpy()
scaled = ((similarity - similarity.min()) / (1 - similarity.min())).numpy()
found = np.unique(segment[top])
palette = {label: plt.get_cmap("tab10")(rank) for rank, label in enumerate(found)}

_, (heat, neighbors) = plt.subplots(1, 2, figsize=(11.0, 4.6), subplot_kw={"projection": "3d"})
heat.scatter(*data["pos_grid"].numpy().T, c=scaled, cmap="viridis", s=0.4, linewidths=0, depthshade=False)
heat.scatter(*data["pos_grid"][query].tolist(), marker="*", s=200, color="red")  # the query point
neighbors.scatter(
    *data["pos_grid"][top].numpy().T,
    c=[palette[label] for label in segment[top]],
    s=1.5,
    linewidths=0,
    depthshade=False,
)
titles = ["cosine similarity to the starred query point", "the 5000 nearest points, by annotated class"]
for ax, title in zip((heat, neighbors), titles):
    ax.set_box_aspect(np.ptp(data["pos_grid"].numpy(), axis=0))
    ax.set_title(title, fontsize=10)
    ax.set_axis_off()
plt.show()
Retrieve whole shapes
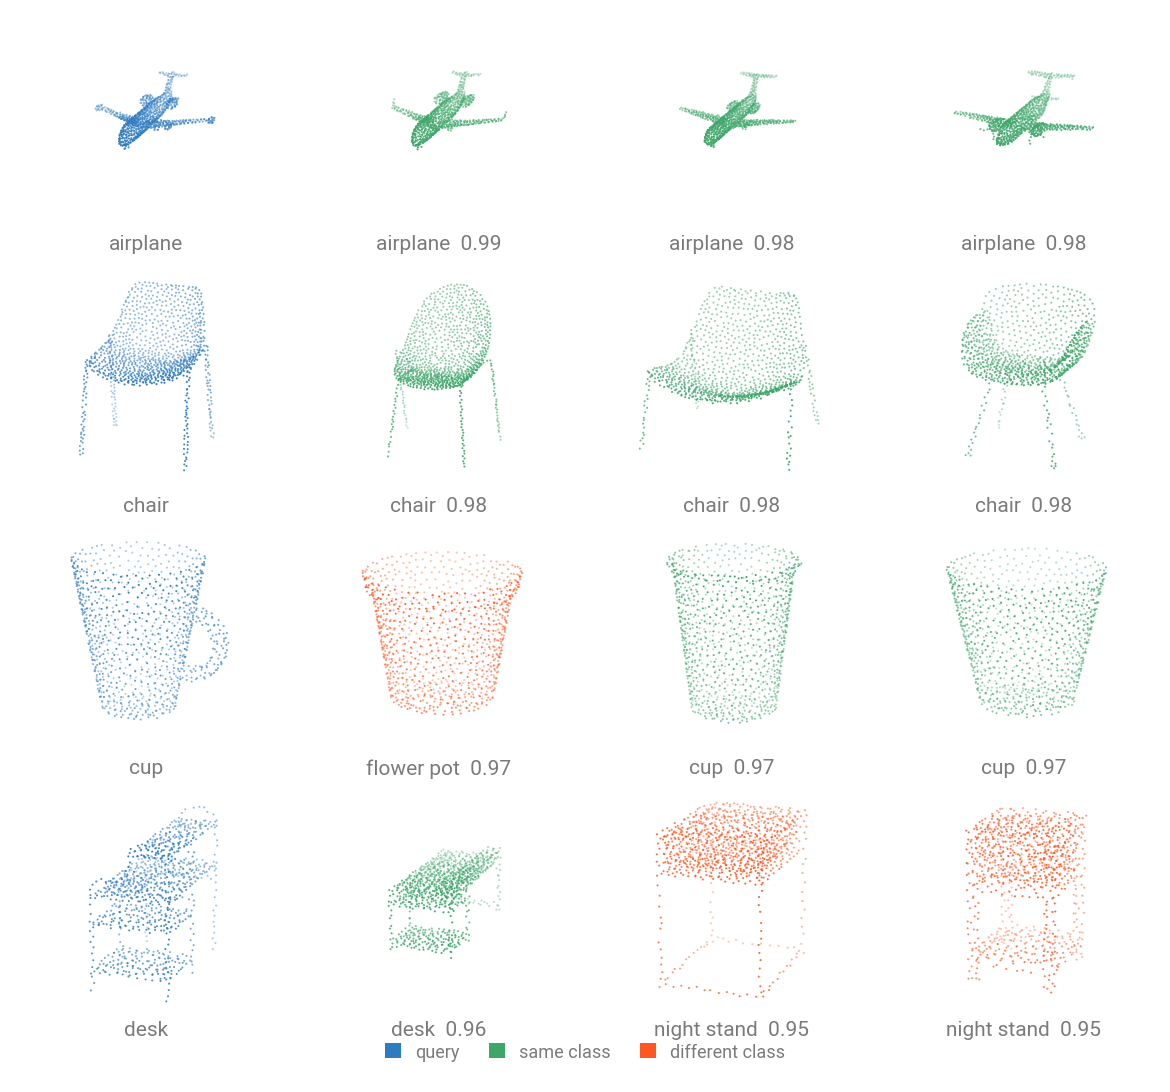
Here we will use the same logic but to retrieve objects from a classification dataset (ModelNet40).
from torch_pointcloud.datasets import ModelNetNormalResampled
from torch_pointcloud.utils.data import PointCloudDataLoader

encoder, info = tp.create_model(
    "pointnet2-ssg.modelnet40.xu-yan",
    task="classification",
    pretrained=True,
    num_classes=0,
    return_info=True,
)
encoder = encoder.eval().to(device)

dataset = ModelNetNormalResampled(
    root="data",
    variant="40",
    train=False,
    transform=info["transform"],
    download=True,
)
dataloader = PointCloudDataLoader(dataset, batch_size=64, num_workers=6)

index, labels = [], []
with torch.inference_mode():
    for item in dataloader:
        embedding = encoder(None, item["pos"].to(device), item["batch"].to(device))
        index.append(F.normalize(embedding, dim=-1).cpu())  # normalize once, at write time
        labels.append(item["label"])

index, labels = torch.cat(index), torch.cat(labels)
print("index:", tuple(index.shape), f"| {index.numel() * index.element_size() / 1e6:.1f} MB float32")
similarity = index @ index.t()
similarity.fill_diagonal_(-1.0)  # never retrieve the query itself
nearest = similarity.argmax(dim=1)
top5 = similarity.topk(5, dim=1).indices

print(f"1-NN retrieval accuracy: {(labels[nearest] == labels).float().mean():.4f}")
print(f"top-5 class purity:      {(labels[top5] == labels[:, None]).float().mean():.4f}")
print(f"5-NN vote accuracy:      {(torch.mode(labels[top5], dim=1).values == labels).float().mean():.4f}")
88.25% of the split retrieves an object of its own class first, against 92.30% for the same checkpoint's trained classification head. The head was fitted to these 40 classes; the search was not told the classes exist.
names = {value: key for key, value in dataset.class_to_idx.items()}
roles = ("tab:blue", "tab:green", "tab:red")  # the query, a neighbor of its class, a neighbor of another

gallery, titles = [], []
for name in ("airplane", "chair", "cup", "desk"):
    query = int((labels == dataset.class_to_idx[name]).nonzero()[0])
    for rank, found in enumerate([query, *top5[query, :3].tolist()]):
        pos = dataset[found]["pos"][:, [0, 2, 1]]  # the dataset is y-up, the figure is z-up
        role = 0 if rank == 0 else int(labels[found] != labels[query]) + 1
        gallery.append({"pos": pos, "color": roles[role]})
        title = names[int(labels[found])].replace("_", " ")
        titles.append(title if rank == 0 else f"{title}  {float(similarity[query, found]):.2f}")

show_clouds(gallery, titles, point_size=1.5, columns=4, height=3.6)
We can also project the whole dataset's embedding space down to 2D with PCA, to see whether the classes separate.
shown = ["airplane", "chair", "table", "bottle", "dresser", "night_stand"]
ids = torch.tensor([dataset.class_to_idx[name] for name in shown])
lookup = torch.full((len(dataset.class_to_idx),), -1, dtype=torch.long)
lookup[ids] = torch.arange(len(shown))  # palette index of each drawn class, -1 for the rest
keep = lookup[labels] >= 0

descriptors = index[keep]
_, _, components = torch.pca_lowrank(descriptors, center=True, q=3, niter=8)
projected = ((descriptors - descriptors.mean(0)) @ components).numpy()
drawn = lookup[labels[keep]].numpy()

_, ax = plt.subplots(figsize=(7.5, 6.0), subplot_kw={"projection": "3d"})
for rank, name in enumerate(shown):
    ax.scatter(*projected[drawn == rank].T, s=4.0, label=name.replace("_", " "), depthshade=False)

ax.legend(loc="upper left", frameon=False, fontsize=9)
ax.set_axis_off()
plt.show()
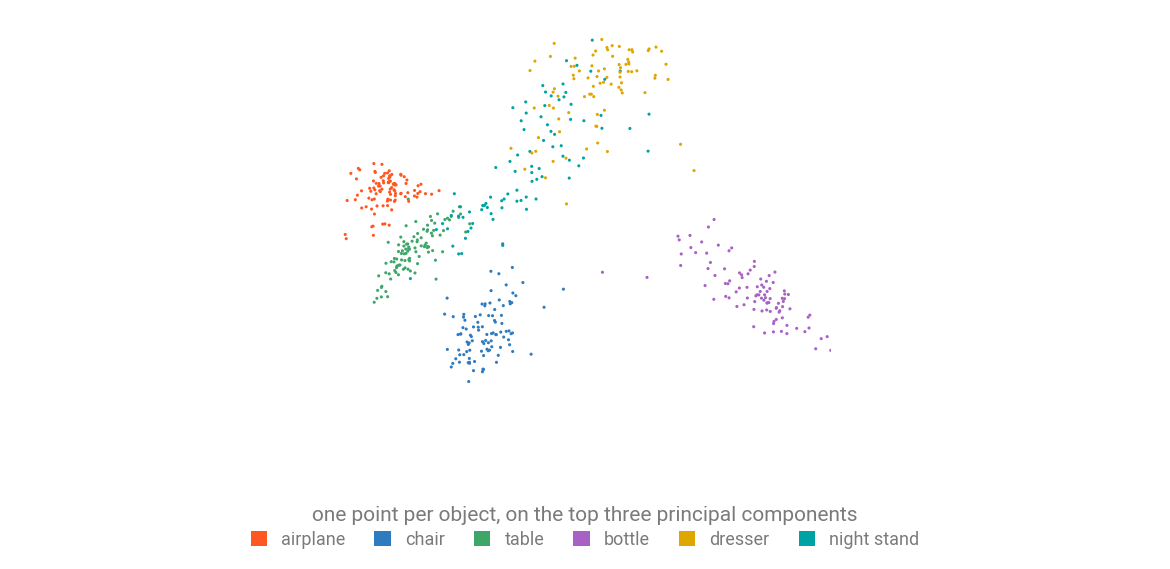
Airplane holds a region of its own and retrieves its own class for all 100 of its test objects. Night stand and dresser objects sit close to each other.