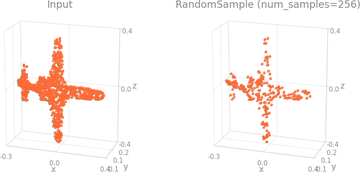
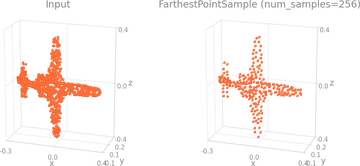
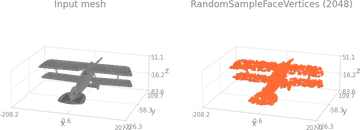
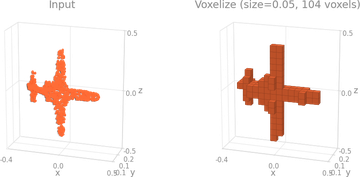
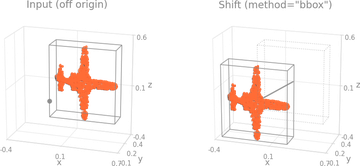
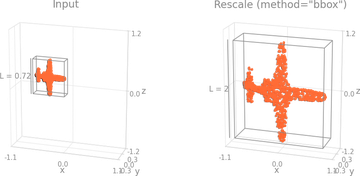
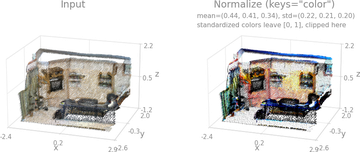
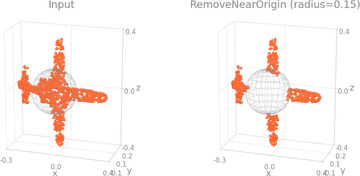
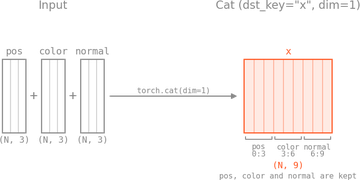
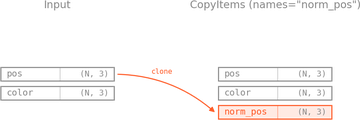
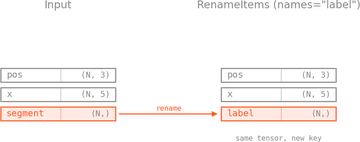
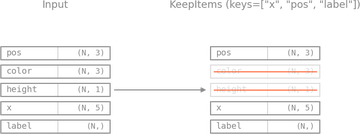
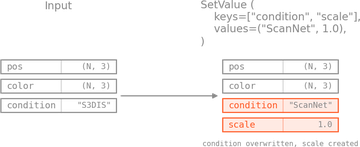
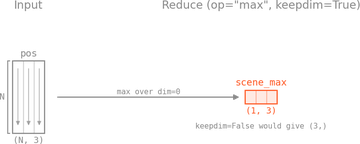
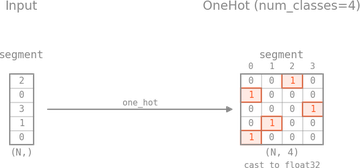
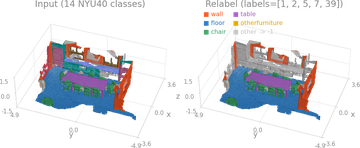
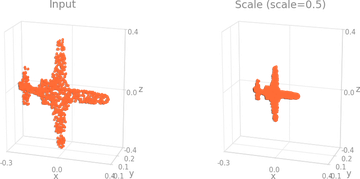
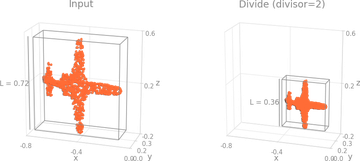
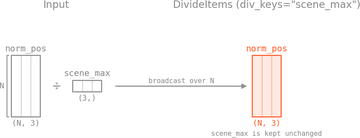
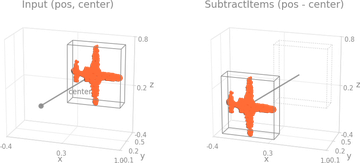
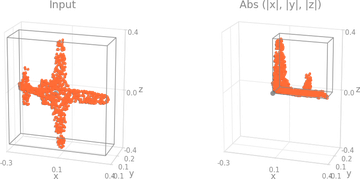
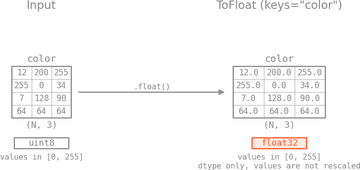
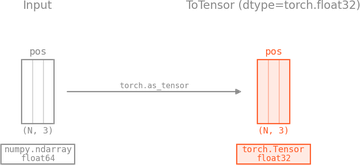
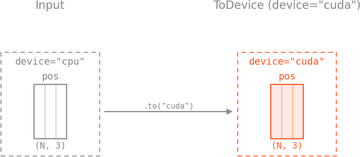
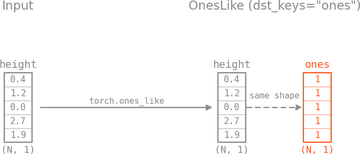
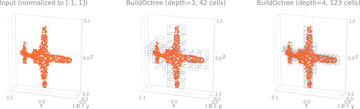
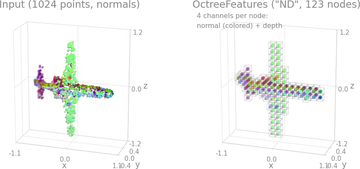
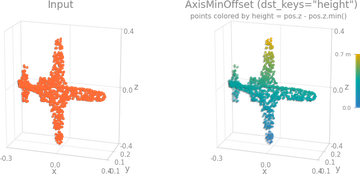A transform takes one sample dict and returns a new one. Compose chains them (RandomApply chains them under a probability), and a dataset applies the chain to every sample it loads. The API follows MONAI's dict transforms and PyTorch Geometric's Data conventions.
Each transform reads and writes the keys you name, so a sample can carry any extra key (intensity, color, ...) without every transform handling it.
A transform that changes the number of points keeps pos, x, segment and batch aligned at the new resolution, and records how to get back when given the dst_* keys: inverse from Voxelize and DivisiblePad (dst_inverse_key), index from the selection samplers (dst_index_key), next to the origin_pos copy the registered pipelines keep. The sampling keys of the data format page define the four keys and how they compose.