Classification
Open in Colab · Download notebook
Classification maps one point cloud to one label: a chair, a table, a plane. Models read a packed batch \((N, C)\) and return logits \((B, \text{num\_classes})\), one row per cloud.
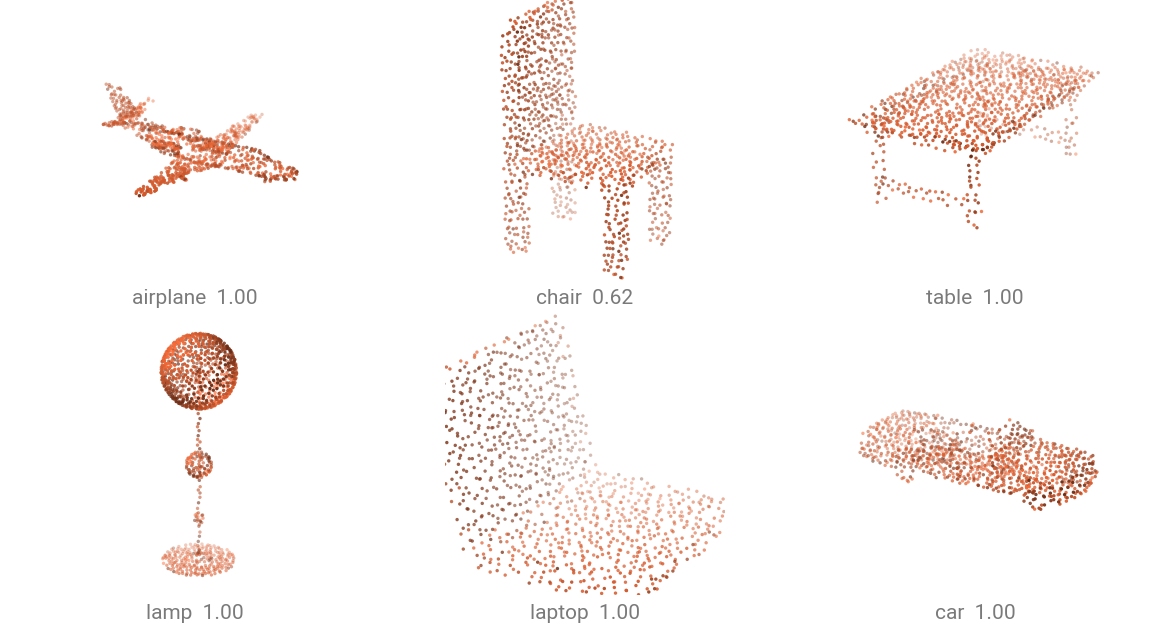
Run a pretrained checkpoint
The example reads one object of the ModelNet40 test set, which ModelNetNormalResampled downloads on first use.
Pass return_info=True to also get the transform registered with the checkpoint, and hand it to the dataset so every sample is ready for the forward pass.
import torch

import torch_pointcloud as tp
from torch_pointcloud.datasets import ModelNetNormalResampled
from torch_pointcloud.utils.data import collate

# Load the pretrained model
model, info = tp.create_model(
    "pointnet2-ssg.modelnet40.xu-yan",
    task="classification",
    pretrained=True,
    return_info=True,
)
model = model.eval()

# Get associated transform
transform = info["transform"]

# Load one object of the ModelNet40 test set
dataset = ModelNetNormalResampled(root="data", variant="40", train=False, download=True, transform=transform)
sample = dataset[0]

# Collate the sample into a batch
data = collate([sample])

# Inference pass
with torch.no_grad():
    logits = model(data.get("x"), data["pos"], data["batch"])  # (1, 40)

# Get predicted classes
classes = info["weights"]["classes"]
top = logits.softmax(dim=-1).topk(3, dim=-1)
for index, score in zip(top.indices[0].tolist(), top.values[0].tolist()):
    print(f"{classes[index]:>12}  {score:.2f}")
Use data.get('x') rather than data['x']
Checkpoints trained on coordinates only never build an x key, and the models accept None.
Inputs and outputs
| Argument | Shape | Meaning |
|---|---|---|
x | \((N, C)\) or None | Per-point features, assembled by the checkpoint's transform (normals, height, color) |
pos | \((N, 3)\) | Coordinates, all clouds in the batch concatenated |
batch | \((N,)\) | Per-point cloud index, \(0 \ldots B-1\) |
| returns | \((B, \text{num\_classes})\) | Class logits, one row per cloud |
Evaluate on a dataset
The same transform slots into a dataset, so reproducing a published score is a plain loop. ModelNetNormalResampled is the presampled ModelNet40 release the published numbers use; it downloads on first use and takes a few GB on disk.
import torch
from tqdm.auto import tqdm

import torch_pointcloud as tp
from torch_pointcloud.datasets import ModelNetNormalResampled
from torch_pointcloud.utils.data import PointCloudDataLoader
from torch_pointcloud.config import DATA_DIR

model, info = tp.create_model(
    "pointnet2-ssg.modelnet40.xu-yan",
    task="classification",
    pretrained=True,
    return_info=True,
)
model = model.cuda().eval()

dataset = ModelNetNormalResampled(
    root=DATA_DIR,
    variant="40",
    train=False,
    transform=info["transform"],
)
dataloader = PointCloudDataLoader(dataset, batch_size=32, num_workers=6)

correct = total = 0
with torch.no_grad():
    for data in tqdm(dataloader, desc="Evaluating"):
        logits = model(None, data["pos"].cuda(), data["batch"].cuda())
        correct += (logits.argmax(dim=-1).cpu() == data["label"]).sum().item()
        total += data["label"].numel()

print(f"overall accuracy: {correct / total:.4f}")
# Evaluating: 100%|██████████| 78/78 [00:24<00:00,  3.24it/s]
# overall accuracy: 0.9230
Train from scratch
Build an untrained model by name and pass the data-dependent arguments. in_channels counts the columns of x (0 when the model reads coordinates only).
import torch
import torch_pointcloud as tp

model = tp.create_model(
    "pointnet2-ssg.modelnet40.xu-yan",
    task="classification",
    in_channels=0,
    num_classes=12,
)

pos = torch.randn(4096, 3)
batch = torch.arange(4).repeat_interleave(1024)
logits = model(None, pos, batch)

print(tuple(logits.shape))
# (4, 12)
Fine-tune a pretrained backbone
You can fine-tune a pretrained backbone by overriding num_classes while loading pretrained weights. This will load the backbone and rebuild the head with the desired number of classes.
model = tp.create_model(
    "pointnet2-ssg.modelnet40.xu-yan",
    task="classification",
    pretrained=True,
    num_classes=10,
)

# OR
model.reset_classifier(10)