Segmentation Datasets
Open in Colab · Download notebook
Segmentation datasets hold one scene per sample: a room or a LiDAR scan, with a label on every point. A sample holds hundreds of thousands of points, so a training pipeline crops, voxelizes or tiles it before batching.
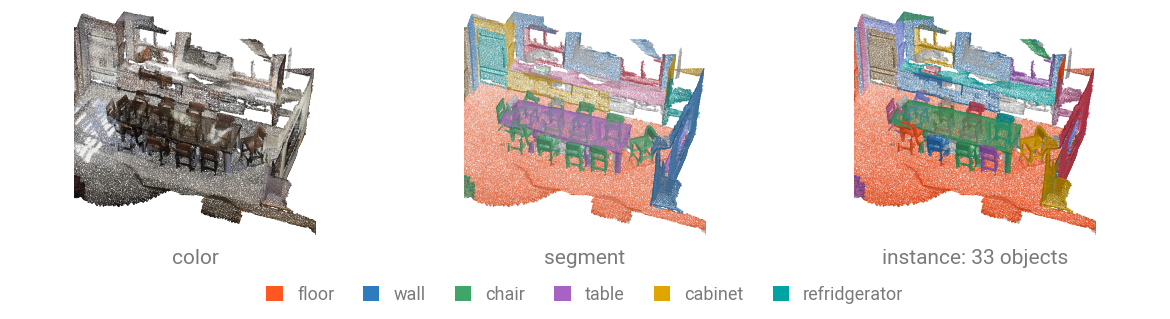
An indoor sample carries color, a semantic label and an instance id on every point. Outdoor scans carry intensity in place of color.
Indoor
| Dataset | Scenes | Classes | Download |
|---|---|---|---|
S3DIS |
272 rooms in 6 areas | 13 | automatic |
S3DISHdf5 |
23 585 tiles of 4 096 points | 13 | automatic |
ScanNet20 |
1 201 train / 312 val | 20 | automatic |
ScanNet200 |
same scenes | 200 | automatic |
Outdoor
| Dataset | Frames or scenes | Classes | Download |
|---|---|---|---|
SemanticKITTI |
19 130 train / 4 071 val | 19 | manual |
Semantic3D |
15 train scenes | 8 | manual |
Toronto3D |
4 tiles | 8 | manual |
ParisLille3D |
3 scenes | 9 | manual |
Load a dataset
from torch_pointcloud.datasets import S3DIS
from torch_pointcloud.config import DATA_DIR

dataset = S3DIS(root=DATA_DIR, areas=["Area_5"], download=True)
print(f"Rooms: {len(dataset)}")
print({k: tuple(v.shape) for k, v in dataset[0].items()})
ScanNet is loaded the same way, and adds estimated normals and the scene name:
from torch_pointcloud.datasets import ScanNet20
from torch_pointcloud.config import DATA_DIR

dataset = ScanNet20(root=DATA_DIR, split="val", download=True)
print(f"Scenes: {len(dataset)}")
print(sorted(dataset[0]))
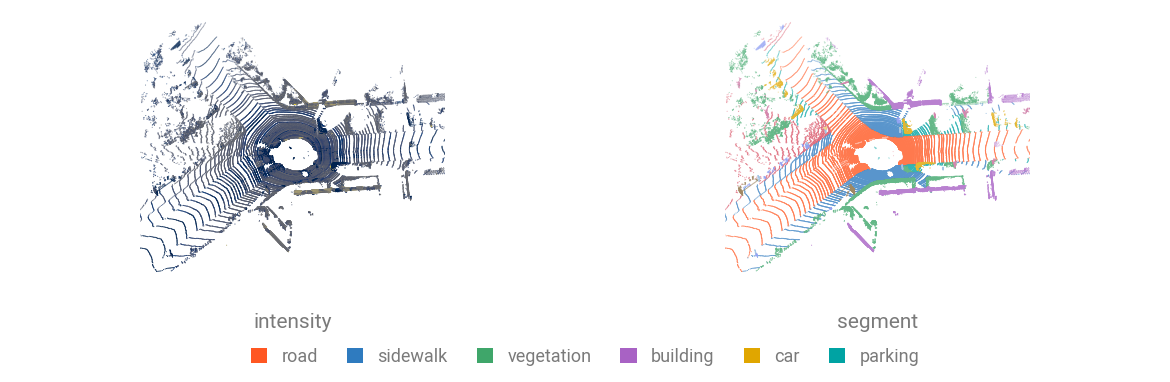
Outdoor scans carry intensity \((N, 1)\) instead of color (reflectance on ParisLille3D), plus the sequence and frame identifiers on SemanticKITTI. Their labels are the raw SemanticKITTI ids, which the checkpoints remap themselves.
Tile a large room
S3DIS and ScanNet can split their scenes into ground-plane blocks at construction time, which reproduces the block-based training protocols:
from torch_pointcloud.config import DATA_DIR

dataset = S3DIS(
    root=DATA_DIR,
    areas=["Area_1"],
    block_size=1.0,
    block_stride=0.5,
    num_nodes=4096,
)
S3DISHdf5 is the same data, released already cut into 4096-point tiles. Use it for benchmarking to reproduce block-based results.
Conventions
Color range differs per loader
color is uint8 in \([0, 255]\) for S3DIS, ScanNet, Toronto3D and Semantic3D, and float32 in \([0, 1]\) for S3DISHdf5. Checkpoint transforms divide by 255 where needed, so mixing the two silently halves or doubles the input scale.
Ignore index differs per dataset
Unlabeled points are 0 in ScanNet (<unk>) and the outdoor sets, and \(-1\) after the class-subset remaps. A checkpoint's Relabel transform sends everything outside its class list to its own default, and the matching loss and metric take ignore_index=-1.
Batch the samples
Scenes batch the same way as objects: PointCloudDataLoader concatenates the per-point tensors and builds the batch index alongside them.
from torch_pointcloud.utils.data import PointCloudDataLoader
from torch_pointcloud.config import DATA_DIR

dataset = S3DIS(
    root=DATA_DIR,
    areas=["Area_5"],
    block_size=1.0,
    block_stride=0.5,
    num_nodes=4096,
)

dataloader = PointCloudDataLoader(
    dataset,
    batch_size=32,
    shuffle=True,
    num_workers=6,
)

data = next(iter(dataloader))

print(f"Batch keys: {data.keys()}")
print(f"  pos.shape: {tuple(data['pos'].shape)}")
print(f"  batch.shape: {tuple(data['batch'].shape)}")
print(f"  segment.shape: {tuple(data['segment'].shape)}")

# Loading: 100%|██████████| 1/1 [00:07<00:00,  7.84s/it]
# Batch keys: dict_keys(['pos', 'color', 'segment', 'instance', 'room_max', 'batch'])
#   pos.shape: (131072, 3)
#   batch.shape: (131072,)
#   segment.shape: (131072,)
Class names
SEMANTIC_KITTI_CLASSES holds the 19 benchmark classes only, while PARISLILLE3D_CLASSES starts with unclassified, so it has one entry more than the class count in the table above.
from torch_pointcloud.datasets.semantickitti import SEMANTIC_KITTI_CLASSES
from torch_pointcloud.datasets.parislille3d import PARISLILLE3D_CLASSES

print(len(SEMANTIC_KITTI_CLASSES), len(PARISLILLE3D_CLASSES))
S3DIS and ScanNet20 expose theirs the same way, and a pretrained checkpoint carries its own head order in info["weights"]["classes"].