scaling
Transforms that rescale or normalize values.
Classes:
-
Rescale–Center a point set and rescale it to a unit extent.
-
Normalize–Normalize dictionary tensor entries: \(x' = (x - \mu) / \max(\sigma, \epsilon)\).
-
MaxAbsScale–Scale dictionary tensor entries by their largest absolute value, per channel:
Rescale(
    keys: KeyCollection,
    eps: float = 1e-06,
    method: RescaleMethod = "centroid",
    allow_missing_keys: bool = False,
)
Bases: DictTransform
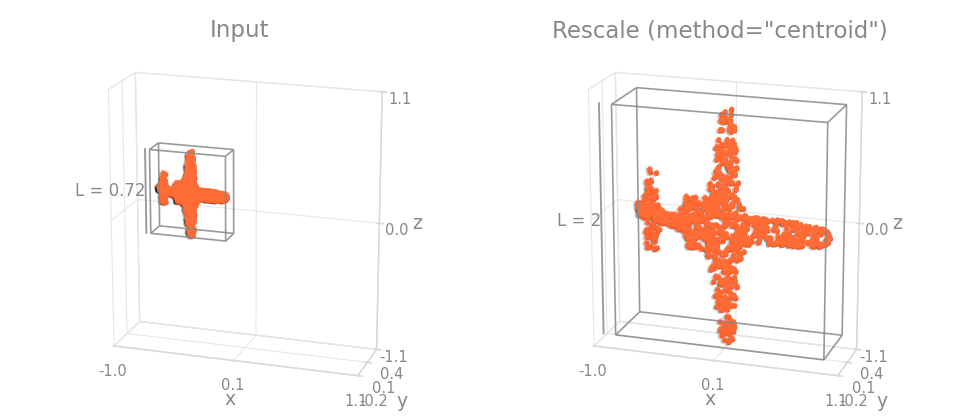
Center a point set and rescale it to a unit extent.
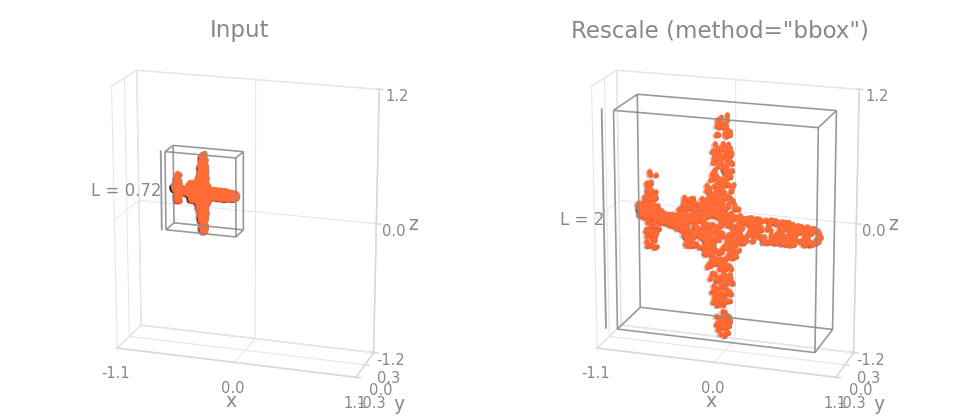
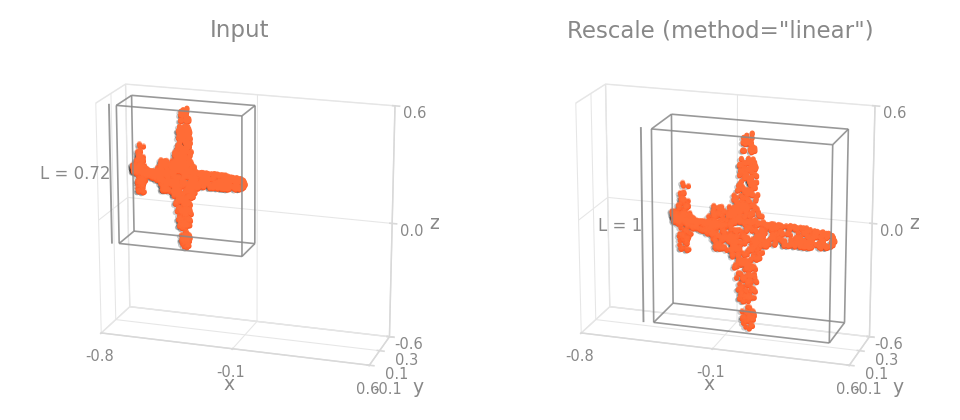
Bundles a centering step and a divide-by-extent step that depend on the same statistics. Four methods, each pairing a center and a denominator:
method | Center on | Divide by |
|---|---|---|
"centroid" | centroid (mean) | max Euclidean distance to center |
"bbox" | bbox midpoint | half of the longest axis extent |
"centroid_extent" | centroid (mean) | longest axis extent |
"min_sphere" | min-sphere center | min-sphere radius |
Empty inputs (N=0) are returned unchanged.
See Also
torch_pointcloud.transforms.functional.rescale
Parameters:
-
keys(KeyCollection) –The keys to rescale.
-
eps(float, default:1e-06) –Small constant added to the denominator for numerical stability.
-
method(RescaleMethod, default:'centroid') –"centroid","bbox","centroid_extent", or"min_sphere". -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
Normalize(
    keys: KeyCollection,
    mean: Sequence[float],
    std: Sequence[float],
    eps: float = 1e-07,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
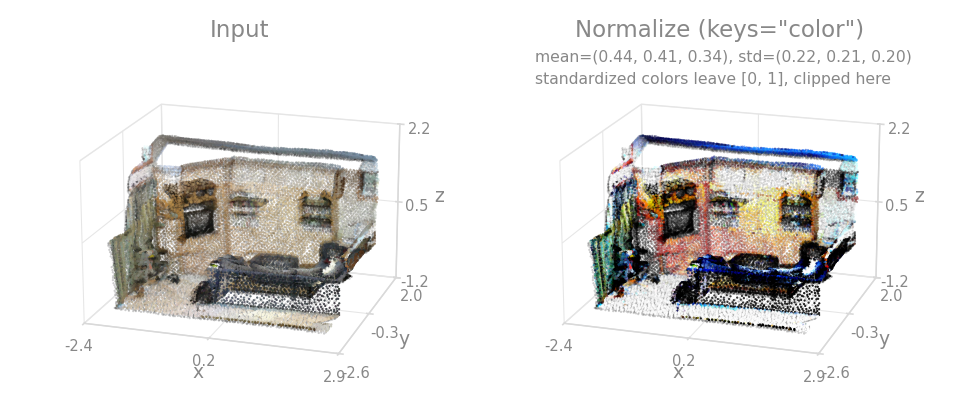
Normalize dictionary tensor entries: \(x' = (x - \mu) / \max(\sigma, \epsilon)\).
Parameters:
-
keys(KeyCollection) –The keys to standardize.
-
mean(Sequence[float]) –Per-channel mean(s). Broadcast against the last dimension of each tensor.
-
std(Sequence[float]) –Per-channel standard deviation(s).
-
eps(float, default:1e-07) –Lower bound on \(\sigma\) to prevent division by zero. Defaults to \(10^{-7}\).
-
allow_missing_keys(bool, default:False) –If
True, missing keys are silently ignored.
Bases: DictTransform
Scale dictionary tensor entries by their largest absolute value, per channel: \(x' = x / \max(\max_i |x_i|, \epsilon)\).
The statistic comes from the sample itself, so the result lies in \([-1, 1]\) whatever the input range (e.g. a LiDAR return number divided by the highest return number of the scene).
Parameters:
-
keys(KeyCollection) –The keys to scale.
-
eps(float, default:1e-07) –Lower bound on the divisor to prevent division by zero. Defaults to \(10^{-7}\).
-
allow_missing_keys(bool, default:False) –If
True, missing keys are silently ignored.
Compute the smallest ball enclosing a point set (Welzl's move-to-front algorithm).
The recursion only descends on the support set (at most \(C + 1\) points), so the depth is bounded by the dimension while the point loop stays iterative; points already known to be inside are moved to the front so that later checks succeed early.
Parameters:
-
points(Tensor) –Tensor of shape \((N, C)\) with \(N \geq 1\).
Returns:
-
Tuple[Tensor, Tensor]–The ball center \((C,)\) and its radius (a scalar), in the dtype and on the device of
points.
Shape
- Input: \((N, C)\)
- Output: \((C,)\) and \(()\)
Center a point set and rescale it to a unit extent.
Operates along the point dimension dim=-2. Pairs a centering step with a scale-by-extent step that share the same statistics. The scale denominator is a single statistic over all leading dimensions, so the input is treated as one point cloud: rescale packed batches per sample (pre-collate), never on concatenated clouds.
Parameters:
-
points(Tensor) –Tensor of shape \((\ldots, N, C)\) with \(C \geq 1\); min/max and means are over \(N\).
-
eps(float, default:1e-06) –Small constant added to the scale denominator for numerical stability.
-
method(RescaleMethod, default:'centroid') –"centroid": subtract the mean over points, then divide by the max Euclidean distance from the centroid plus \(\epsilon\):
$$ \mathbf{x} \leftarrow \frac{\mathbf{x} - \boldsymbol{\mu}}{\max_i |\mathbf{x}_i - \boldsymbol{\mu}|_2 + \epsilon} $$
"bbox": subtract the axis-aligned bounding-box midpoint (midrange center), then divide by half the longest edge of that box plus \(\epsilon\) (matches common ModelNet-style normalization):
$$ \mathbf{c} = \frac{\mathbf{x}{\min} + \mathbf{x}, \quad r = \frac{1}{2}\max_j (x_{\max,j} - x_{\min,j}) + \epsilon, \quad \mathbf{x} \leftarrow \frac{\mathbf{x} - \mathbf{c}}{r} $$}}{2
"centroid_extent": subtract the centroid then divide by the longest axis-aligned span (the convention used by the published RandLA-Net Toronto-3D / Semantic3D checkpoints):
$$ \mathbf{x} \leftarrow \frac{\mathbf{x} - \boldsymbol{\mu}}{\max_j (x_{\max,j} - x_{\min,j}) + \epsilon} $$
"min_sphere": subtract the center of the minimal enclosing sphere of all points and divide by its radius plus \(\epsilon\) (seeminimal_enclosing_ball; the OctFormer ModelNet40 normalization).
Returns:
-
Tensor–Normalized tensor, same shape as
points.
Raises:
-
ValueError–If
methodis not"centroid","bbox","centroid_extent", or"min_sphere".
normalize(
    x: Tensor,
    mean: Union[Tensor, Sequence[float], float],
    std: Union[Tensor, Sequence[float], float],
    eps: float = 1e-07,
) -> Tensor
Per-channel standardization: \(x' = (x - \mu) / \max(\sigma, \epsilon)\).
Parameters:
-
x(Tensor) –Input tensor. The last dimension is treated as the channel dim.
-
mean(Union[Tensor, Sequence[float], float]) –Per-channel mean(s). Broadcast against the last dimension.
-
std(Union[Tensor, Sequence[float], float]) –Per-channel standard deviation(s).
-
eps(float, default:1e-07) –Lower bound on \(\sigma\) to prevent division by zero.
Returns:
-
Tensor–Standardized tensor, same shape as
x.
Scale a tensor by its largest absolute value, per channel: \(x' = x / \max(\max_i |x_i|, \epsilon)\).
The maximum is taken over every dimension but the last (the channel dimension), so the input is treated as one point cloud: scale packed batches per sample (pre-collate), never on concatenated clouds.
Parameters:
-
x(Tensor) –Input tensor. Integer tensors are cast to
float32. -
eps(float, default:1e-07) –Lower bound on the divisor to prevent division by zero.
Returns:
-
Tensor–The scaled tensor, same shape as
x, with values in \([-1, 1]\).