Overview
Dict-based transforms and their tensor-level functional equivalents.
All transforms in this module operate on a single scene (one sample, pre-collate). The batch key is not consumed at this layer; reductions like mean, min, and max are computed over the whole tensor, not per-batch. Apply transforms before DataLoader collation if you want per-scene behavior.
Transforms are non-mutating: each transform returns a new shallow-copy dict. Tensors inside the dict are not cloned unless the transform's documentation says so.
Sampling keys: a transform that changes the number of points can record how to get back to its input. Voxelizers (Voxelize, DivisiblePad) write inverse, \((N_\text{in},)\), input row to output row, under dst_inverse_key, so preds[inverse] scores at input resolution. Selection samplers (RandomSample, FarthestPointSample, SphereCrop, RemoveNearOrigin, RandomDropout, ShufflePoint, ApplyMask, Slice along dim=0) write index, \((N_\text{out},)\), output row to input row, under dst_index_key. Both compose through a prior value at the same key, so a chain of samplers of one kind stays addressed to the outermost input. Registered evaluation pipelines set these keys and copy the source cloud to origin_pos / origin_segment with CopyItems before their first sampling step.
Modules:
-
augmentation–Random geometric and color augmentations.
-
base–Base classes of the dict transforms and their composition.
-
box–Transforms that build and encode 3D box targets.
-
functional–Functional API of the transforms: the tensor functions of every themed module.
-
geometry–Transforms that move points or derive geometric quantities.
-
masking–Transforms that build or apply point masks.
-
mixing–Transforms that mix two samples into one.
-
octree–Transforms that build an octree and its features.
-
sampling–Transforms that select a subset of the points.
-
scaling–Transforms that rescale or normalize values.
-
utils–Transforms that rename, copy, convert or combine the entries of a sample dict, and element-wise arithmetic.
-
voxelization–Transforms that voxelize the points or pad them to a voxel grid.
Classes:
-
RandomColorAutoContrast–Stretch per-cloud color range to the full extent, then blend back, with probability
p. -
RandomColorDrop–Replace colors with a constant gray value with probability
p. -
RandomColorGrayScale–Convert listed color keys to grayscale (BT.601 luminance) with probability
p. -
RandomColorJitter–Jitter colors by brightness, contrast, and saturation strengths.
-
RandomColorShift–Additive per-channel color shift sampled uniformly per channel.
-
RandomElasticDistortion–Apply a smooth random displacement field (elastic distortion).
-
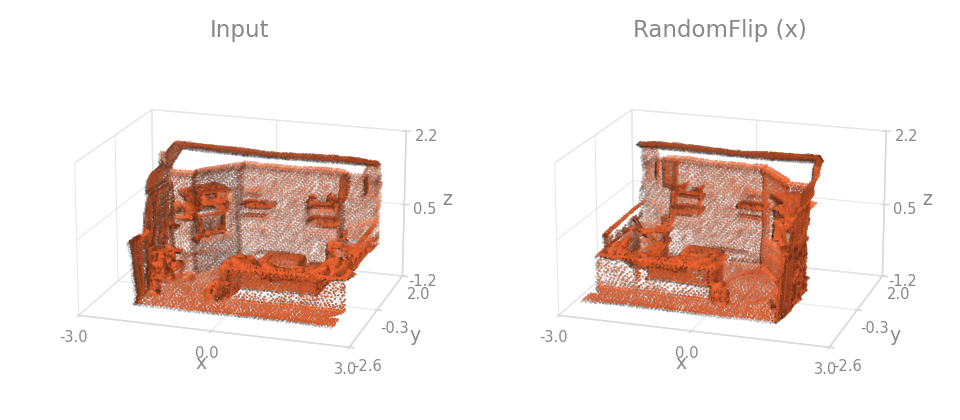
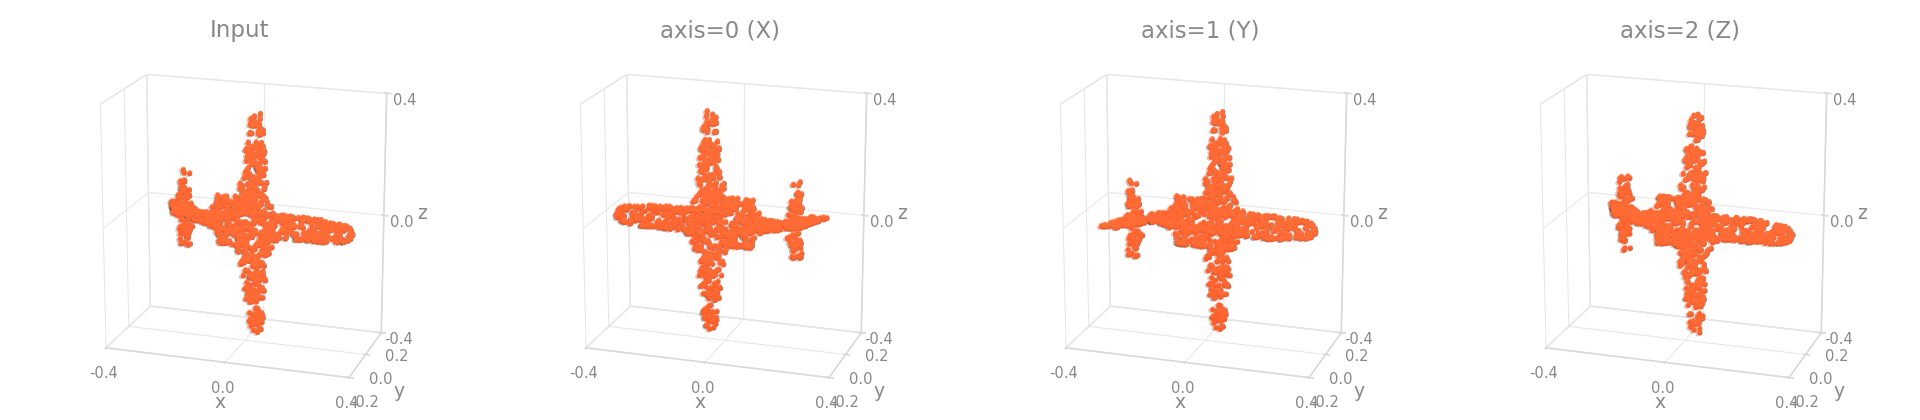
RandomFlip–Flip listed axes (and optionally oriented boxes) with probability
peach. -
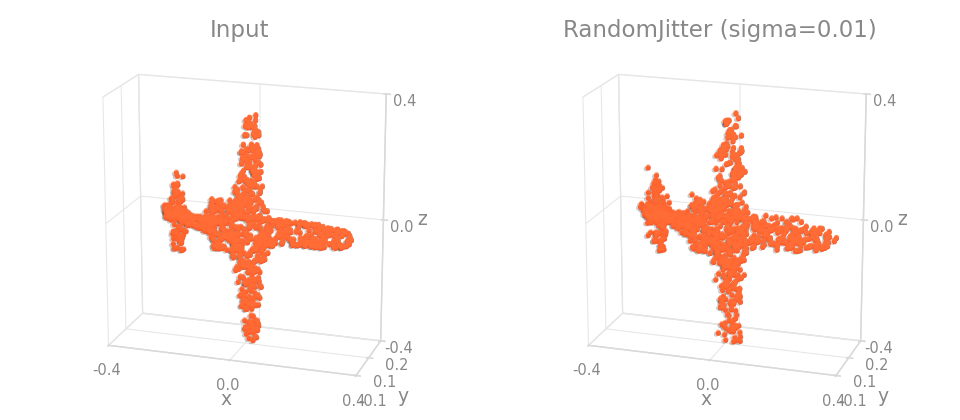
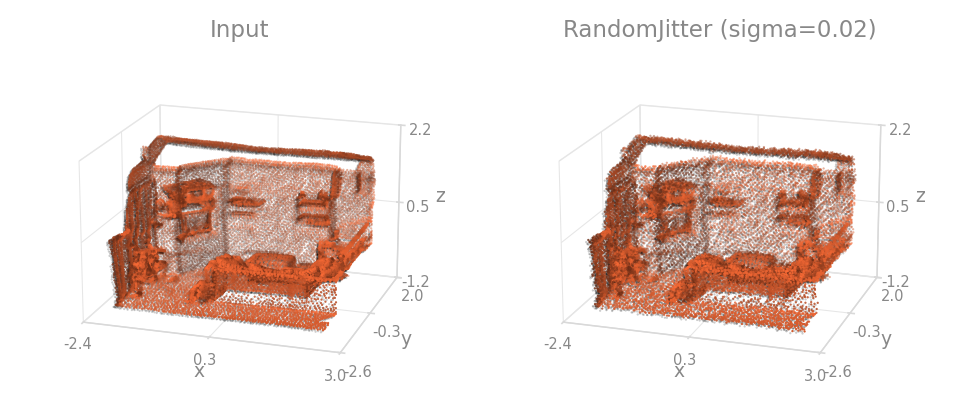
RandomJitter–Add Gaussian noise to listed keys, optionally clipped.
-
RandomRotate–Rotate one or more keys (and optionally oriented boxes) by a uniformly random angle around an axis.
-
RandomRotateChoice–Rotate one or more keys by an angle chosen uniformly from a discrete list.
-
RandomScale–Scale one or more keys (and optionally oriented boxes) by a uniformly random factor.
-
RandomTranslate–Translate listed keys (and optionally oriented boxes) by a uniformly random vector.
-
Compose–Compose multiple transforms into a single transform.
-
DictTransform–Base class for dictionary transforms.
-
RandomApply–Apply a pipeline of transforms with probability
p, else return the data unchanged. -
Transform–Base class for all point cloud transforms.
-
InstanceToBox–Axis-aligned bounding boxes from per-point instance ids (e.g. ScanNet detection targets).
-
PasteBoxes–Paste objects cut out by
cut_boxesinto the scene, a target number per label. -
RelabelBoxes–Map raw box labels to a detection class set and flag don't-care boxes for the AP metric.
-
AxisMinOffset–Per-point offset from a floor reference along a chosen coordinate axis.
-
BBoxCenter–Derive the center of an axis-aligned bbox stored as a flat tensor.
-
EstimateNormals–Estimate per-point surface normals from coordinates via local PCA.
-
Quantize–Integer voxel-grid coordinates of every point, keeping the cloud at full resolution.
-
Shift–Shift dictionary tensor entries by subtracting a computed offset.
-
Translate–Add a constant offset to dictionary tensor entries.
-
ApplyMask–Apply a mask stored in a dictionary to other dictionary entries.
-
BoxMask–Create a boolean mask for points inside an axis-aligned bounding box (AABB).
-
CubeMask–Create a boolean mask for points inside an axis-aligned cube (L∞ / Chebyshev ball).
-
RemoveNearOrigin–Remove points that are within a given radius of the origin from dictionary entries.
-
SphereMask–Create a boolean mask for points inside an L2 (Euclidean) ball.
-
LaserMix–Mix two LiDAR scans by swapping alternating inclination (pitch) bands.
-
Mix3D–Concatenate two scenes into one, offsetting the second scene's instance ids.
-
PolarMix–Mix two LiDAR scans by swapping an azimuth sector and rotate-pasting instance-class points.
-
BuildOctree–Build an octree from positions stored in a dictionary.
-
OctreeFeatures–Extract per-node features from an octree via
octree.get_input_feature. -
FarthestPointSample–Farthest-point sampling (FPS) of a dictionary entry.
-
RandomBlockCrop–Keep the points of a random vertical block: a square window of the ground plane, full height.
-
RandomDropout–Randomly drop a fraction of points across all listed keys.
-
RandomSample–Randomly sample a fixed number of points from dict entries.
-
RandomSampleFaceVertices–Randomly sample a fixed number of vertices from a 3D mesh stored in a dictionary.
-
ShufflePoint–Randomly permute the order of points across listed keys.
-
Slice–Slice each listed tensor along a chosen dimension via standard Python slicing.
-
SphereCrop–Keep only points inside an L2 sphere of given radius.
-
MaxAbsScale–Scale dictionary tensor entries by their largest absolute value, per channel:
-
Normalize–Normalize dictionary tensor entries: \(x' = (x - \mu) / \max(\sigma, \epsilon)\).
-
Rescale–Center a point set and rescale it to a unit extent.
-
Abs–Make dictionary tensor entries absolute.
-
Cat–Concatenates tensors from multiple keys into a single feature tensor.
-
Clamp–Clamp tensor entries to a range (a thin wrapper over
torch.clamp). -
CopyItems–Copy values from source keys to new destination keys.
-
Divide–Divide dictionary tensor entries by a divisor.
-
DivideItems–Divide target keys by the value of a reference key element-wise.
-
KeepItems–Keep only items in the data dictionary that are in the keys list.
-
OneHot–One-hot encode integer-class tensors.
-
OnesLike–Adds a tensor of ones shaped like existing dictionary entries.
-
Reduce–Reduce a tensor along a dimension and store the scalar/vector result.
-
Relabel–Remap integer labels in dictionary entries via a lookup table.
-
RenameItems–Rename keys in the dictionary.
-
Scale–Multiply dictionary tensor entries by a scale factor.
-
SetValue–Set values for keys in the dictionary, creating or overwriting them.
-
SubtractItems–Subtract the value of a reference key from target keys element-wise.
-
ToDevice–Convert dictionary tensor entries to the given device.
-
ToFloat–Cast dictionary tensor entries to float32.
-
ToTensor–Convert dictionary entries to tensors.
-
DivisiblePad–Pad per-point tensors so each batch is divisible by
num_samples. -
HardVoxelize–Hard-voxelize a single scene into the per-voxel point stack consumed by voxel detectors.
-
Voxelize–Voxelize a point cloud by grid-binning and per-voxel reduction.
RandomColorAutoContrast(
    keys: KeyCollection,
    blend: Optional[float] = 0.5,
    int_color: bool = False,
    p: float = 0.2,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Stretch per-cloud color range to the full extent, then blend back, with probability p.
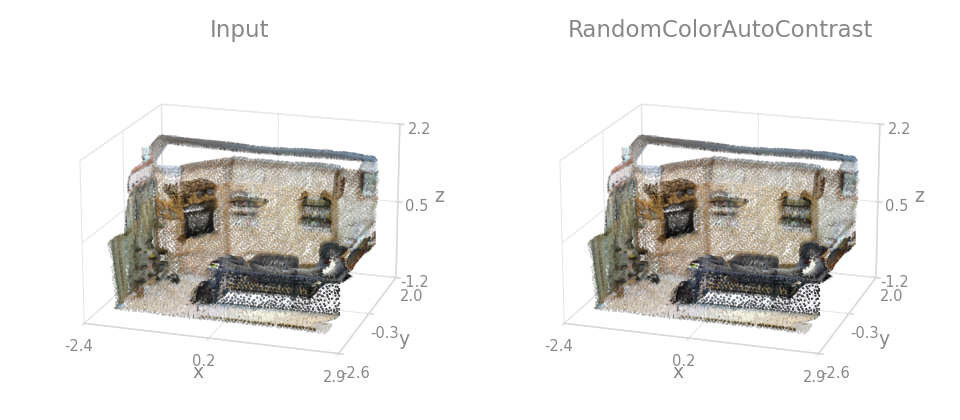
See Also
torch_pointcloud.transforms.functional.color_auto_contrast
Parameters:
-
keys(KeyCollection) –Color keys, shape \((N, 3)\).
-
blend(Optional[float], default:0.5) –Blend weight in
[0, 1].1.0is fully auto-contrasted;0.0is the input;Nonedraws a uniform weight on every application. -
int_color(bool, default:False) –If
True, treat float colors as[0, 255]values; otherwise[0, 1].uint8colors are always treated as[0, 255]regardless of the flag; float colors above 1 withint_color=Falseraise a ValueError. -
p(float, default:0.2) –Probability of applying the transform.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the result.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomColorDrop(
    keys: KeyCollection,
    fill: float = 0.5,
    int_color: bool = False,
    p: float = 0.2,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Replace colors with a constant gray value with probability p.
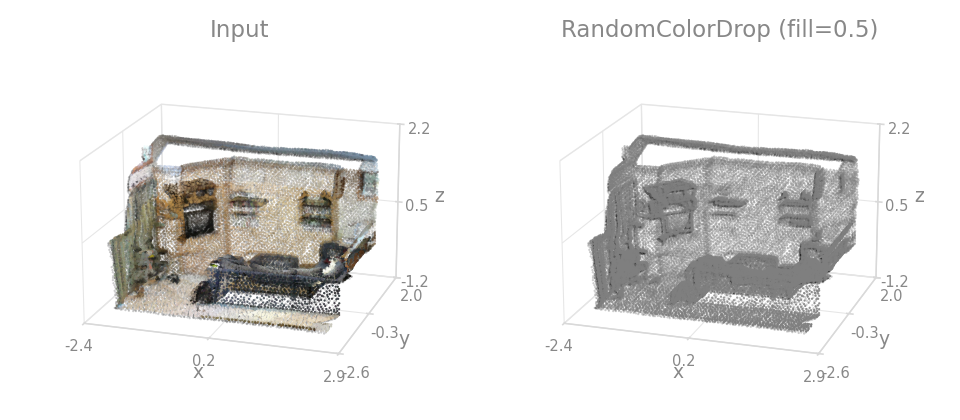
See Also
torch_pointcloud.transforms.functional.color_drop
Parameters:
-
keys(KeyCollection) –Color keys to drop.
-
fill(float, default:0.5) –Replacement value in the range implied by
int_color([0, 1]whenFalse,[0, 255]whenTrue); rescaled to the input's actual range when that differs, so the default0.5fills127onuint8colors. -
int_color(bool, default:False) –If
True, treat float colors as[0, 255]values; otherwise[0, 1].uint8colors are always treated as[0, 255]regardless of the flag; float colors above 1 withint_color=Falseraise a ValueError. -
p(float, default:0.2) –Probability of dropping colors.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the result.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomColorGrayScale(
    keys: KeyCollection,
    int_color: bool = False,
    p: float = 0.2,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Convert listed color keys to grayscale (BT.601 luminance) with probability p.
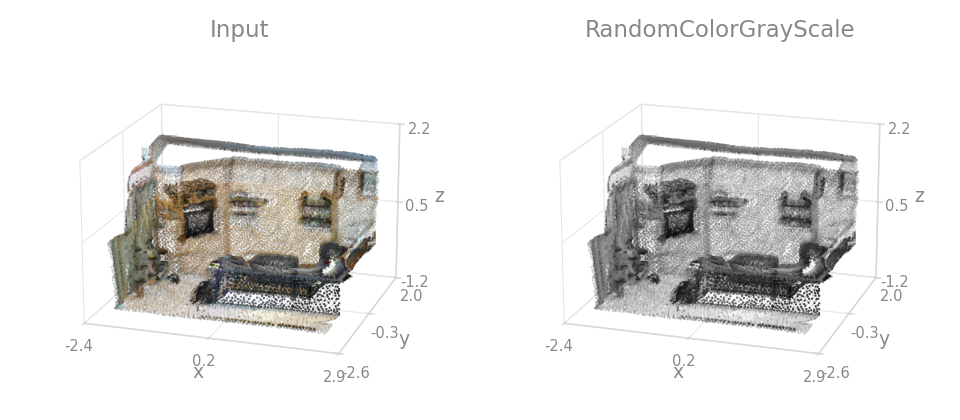
See Also
torch_pointcloud.transforms.functional.color_grayscale
Parameters:
-
keys(KeyCollection) –Color keys, shape \((N, 3)\).
-
int_color(bool, default:False) –If
True, treat colors as[0, 255]ints; otherwise[0, 1]floats. -
p(float, default:0.2) –Probability of converting to grayscale.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the result.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomColorJitter(
    keys: KeyCollection,
    brightness: float = 0.4,
    contrast: float = 0.4,
    saturation: float = 0.2,
    int_color: bool = False,
    p: float = 1.0,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Jitter colors by brightness, contrast, and saturation strengths.
Each strength is a relative delta uniformly sampled from [-x, x]. Sampling is once per call, so the same factors are applied to every listed key.
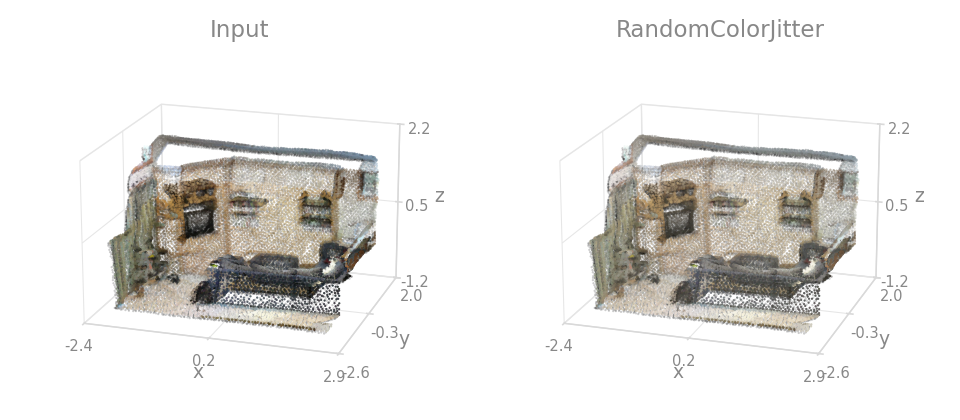
See Also
torch_pointcloud.transforms.functional.color_jitter
Parameters:
-
keys(KeyCollection) –Color keys to jitter, shape \((N, 3)\).
-
brightness(float, default:0.4) –Max relative brightness change in \([0, 1]\).
-
contrast(float, default:0.4) –Max relative contrast change in \([0, 1]\).
-
saturation(float, default:0.2) –Max relative saturation change in \([0, 1]\).
-
int_color(bool, default:False) –If
True, treat float colors as[0, 255]values; otherwise[0, 1].uint8colors are always treated as[0, 255]regardless of the flag; float colors above 1 withint_color=Falseraise a ValueError. -
p(float, default:1.0) –Probability of applying the transform.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the jittered tensors.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomColorShift(
    keys: KeyCollection,
    shift_range: Tuple[float, float] = (-0.05, 0.05),
    int_color: bool = False,
    p: float = 1.0,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
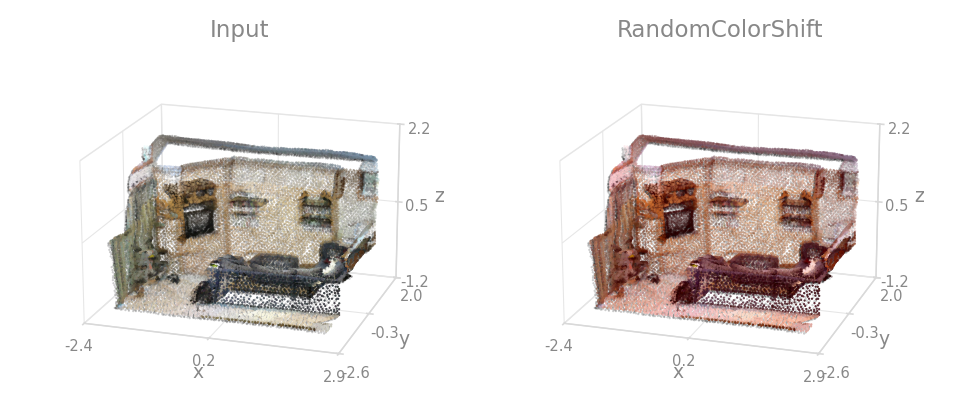
Additive per-channel color shift sampled uniformly per channel.
For each of the 3 channels, sample one offset uniformly from shift_range and add it to every point's value. Sampling is once per call (same shift across all listed keys). Result is clamped to the valid color range.
See Also
torch_pointcloud.transforms.functional.color_shift
Parameters:
-
keys(KeyCollection) –Color keys to shift, shape \((N, 3)\).
-
shift_range(Tuple[float, float], default:(-0.05, 0.05)) –Min and max per-channel offset (in the same range as the colors).
-
int_color(bool, default:False) –If
True, treat float colors as[0, 255]values; otherwise[0, 1].uint8colors are always treated as[0, 255]regardless of the flag; float colors above 1 withint_color=Falseraise a ValueError. -
p(float, default:1.0) –Probability of applying the transform.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the shifted tensors.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomElasticDistortion(
    keys: KeyCollection,
    granularity: Union[float, Sequence[float]] = 0.2,
    magnitude: Union[float, Sequence[float]] = 0.4,
    p: float = 1.0,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
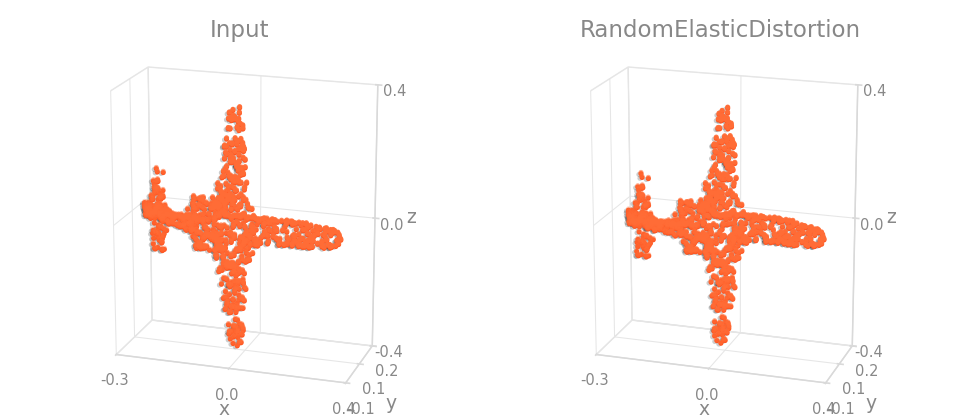
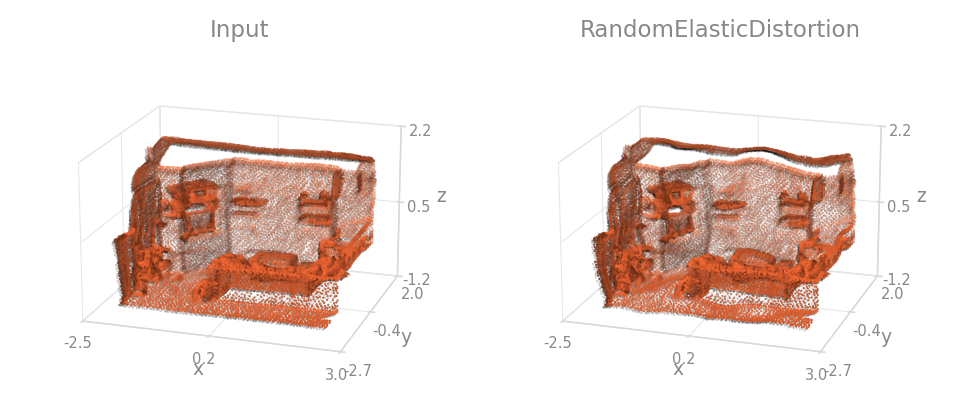
Apply a smooth random displacement field (elastic distortion).
Used in sparse-voxel indoor segmentation recipes. Sampling is done once per call so multi-key consistency is preserved (the same displacement field is applied to every listed key).
For multi-scale distortion (the common default), compose two RandomElasticDistortion calls with different granularity / magnitude.
See Also
torch_pointcloud.transforms.functional.random_elastic_distortion
Parameters:
-
keys(KeyCollection) –Position keys to distort, shape \((N, 3)\). All listed keys must share the same leading dimension \(N\): the per-point displacement is computed once from the first present key and added to every key.
-
granularity(Union[float, Sequence[float]], default:0.2) –Size of the displacement-field grid cells. Smaller values give higher-frequency distortion. Several values (paired with
magnitude) run one pass each, under the same probability gate. -
magnitude(Union[float, Sequence[float]], default:0.4) –Standard deviation of the per-cell Gaussian noise. Larger values give stronger deformation.
-
p(float, default:1.0) –Probability of applying the transform.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the distorted tensors.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomFlip(
    keys: KeyCollection,
    axes: Sequence[int] = (0, 1),
    p: float = 0.5,
    box_key: Optional[str] = None,
    dst_keys: Optional[KeyCollection] = None,
    dst_box_key: Optional[str] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
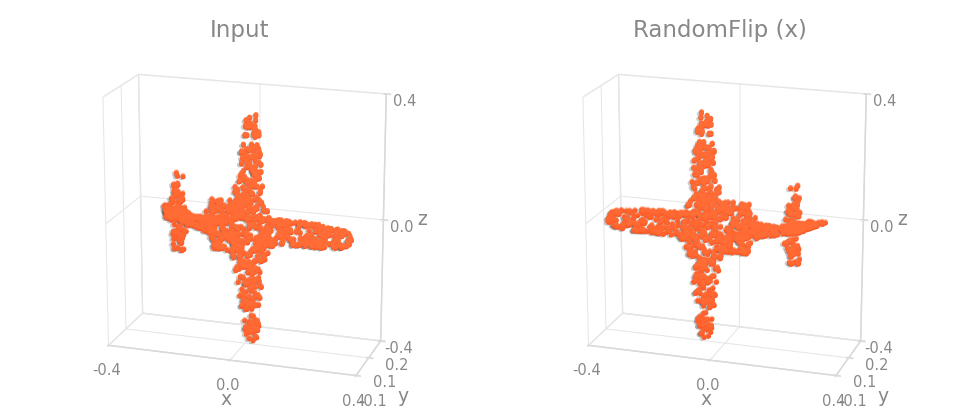
Flip listed axes (and optionally oriented boxes) with probability p each.
Sampling is done once per call: every listed key and the optional box are flipped on the same axes. Each key is a \((\ldots, 3)\) field or a packed \((N, 3G)\) field of tiled 3D offsets (e.g. vote offsets). Pass box_key to also flip a \((K, 7)\) oriented-box tensor (centers negated, heading remapped).
See Also
torch_pointcloud.transforms.functional.flip_vectors, torch_pointcloud.transforms.functional.flip_boxes
Parameters:
-
keys(KeyCollection) –Keys to flip. Each must be a \((\ldots, 3)\) or \((N, 3G)\) vector field.
-
axes(Sequence[int], default:(0, 1)) –Axis indices (into each 3D triple) to consider for flipping.
-
p(float, default:0.5) –Per-axis flip probability.
-
box_key(Optional[str], default:None) –Optional key of a \((K, 7)\) oriented-box tensor to flip jointly; a \((K, 9)\) tensor carries a planar velocity in its last two columns, flipped with the boxes.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the flipped tensors.
-
dst_box_key(Optional[str], default:None) –Where to store the flipped boxes. Defaults to
box_key(in-place). -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomJitter(
    keys: KeyCollection,
    sigma: float = 0.01,
    clip: Optional[float] = 0.05,
    p: float = 1.0,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Add Gaussian noise to listed keys, optionally clipped.
Each key gets its own independent noise tensor (because the noise shape matches the key shape). Pair-rotation-style consistency does not apply here.
See Also
torch_pointcloud.transforms.functional.random_jitter
Parameters:
-
keys(KeyCollection) –Keys to jitter.
-
sigma(float, default:0.01) –Standard deviation of the Gaussian noise.
-
clip(Optional[float], default:0.05) –If not
None, clip the noise to[-clip, clip]. -
p(float, default:1.0) –Probability of applying the transform.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the jittered tensors.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomRotate(
    keys: KeyCollection,
    angle_range: Tuple[float, float] = (-180.0, 180.0),
    axis: int = 2,
    p: float = 1.0,
    box_key: Optional[str] = None,
    center: Union[str, Sequence[float]] = "origin",
    vector_keys: Optional[KeyCollection] = None,
    dst_keys: Optional[KeyCollection] = None,
    dst_box_key: Optional[str] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
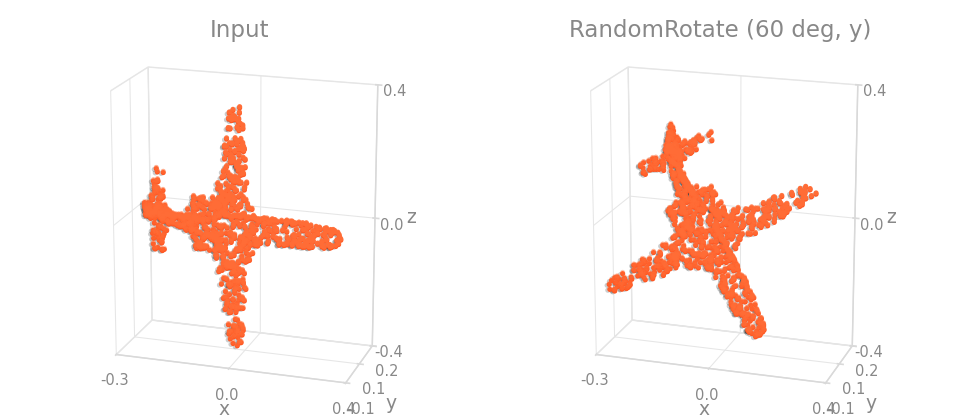
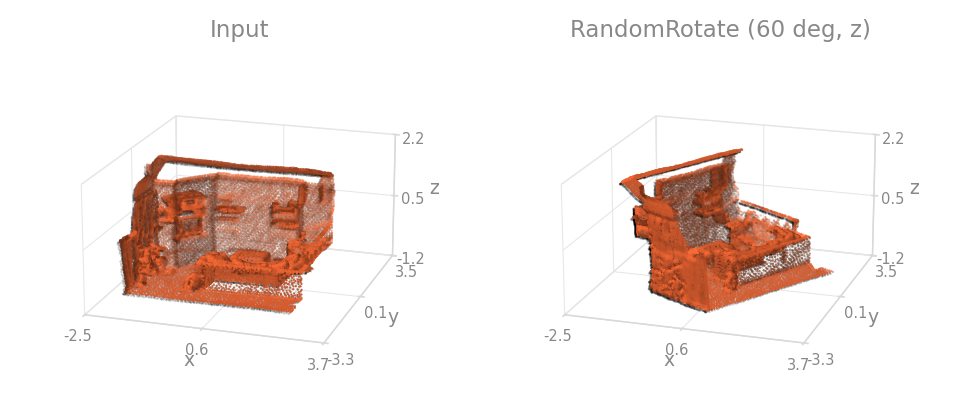
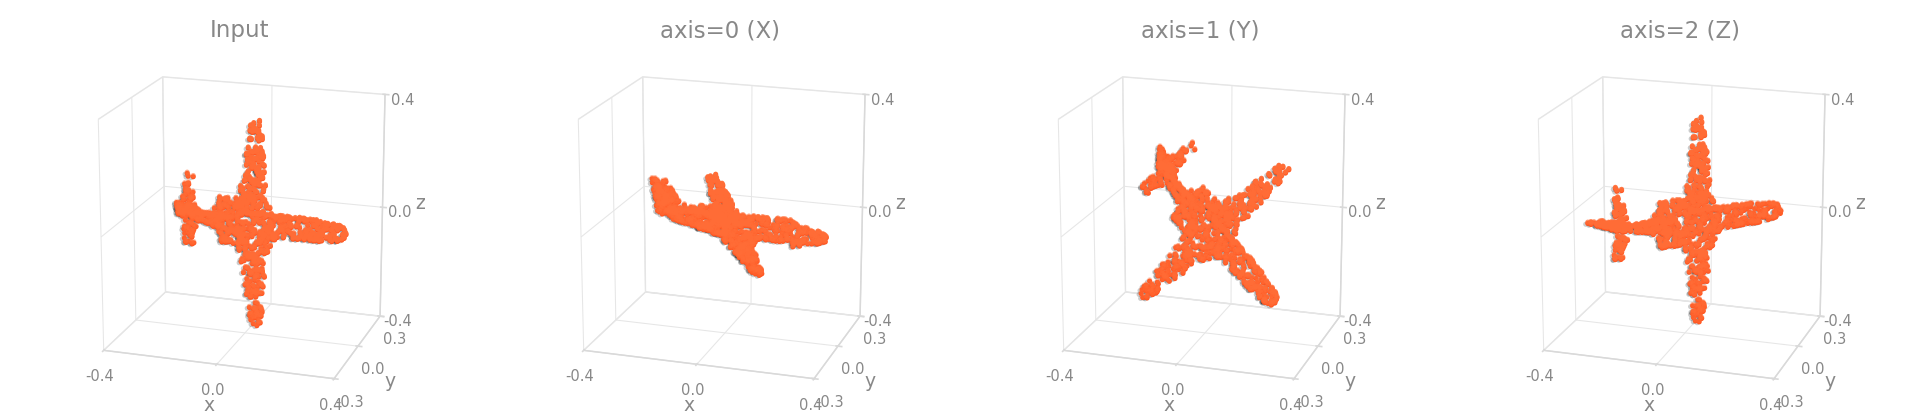
Rotate one or more keys (and optionally oriented boxes) by a uniformly random angle around an axis.
Sampling is done once per call: every listed key and the optional box get the same rotation. Each key is a \((\ldots, 3)\) field or a packed \((N, 3G)\) field of tiled 3D offsets (e.g. vote offsets). Pair keys=("pos", "normal") to keep positions and normals consistent, or pass box_key to also rotate a \((K, 7)\) oriented-box tensor (centers rotated, heading incremented). Box headings are counterclockwise yaw about the up axis, so box_key requires axis=2.
See Also
torch_pointcloud.transforms.functional.rotate_vectors, torch_pointcloud.transforms.functional.rotate_boxes, torch_pointcloud.transforms.functional.rotation_matrix
Parameters:
-
keys(KeyCollection) –Keys to rotate. Each must be a \((\ldots, 3)\) or \((N, 3G)\) vector field.
-
angle_range(Tuple[float, float], default:(-180.0, 180.0)) –Min and max rotation angle, in degrees.
-
axis(int, default:2) –Axis index to rotate around (0=X, 1=Y, 2=Z).
-
p(float, default:1.0) –Probability of applying the transform.
-
box_key(Optional[str], default:None) –Optional key of a \((K, 7)\) oriented-box tensor to rotate jointly (requires
axis=2); a \((K, 9)\) tensor carries a planar velocity in its last two columns, rotated with the boxes. -
center(Union[str, Sequence[float]], default:'origin') –Point the rotation is about:
"origin","bbox"(the midrange of the first key),"centroid"(its mean) or an explicit \((x, y, z)\). -
vector_keys(Optional[KeyCollection], default:None) –Direction fields (normals) rotated without the recentering, whatever
centeris. -
dst_keys(Optional[KeyCollection], default:None) –Where to store the rotated tensors. Defaults to
keys(in-place). -
dst_box_key(Optional[str], default:None) –Where to store the rotated boxes. Defaults to
box_key(in-place). -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomRotateChoice(
    keys: KeyCollection,
    angles: Sequence[float],
    axis: int = 2,
    p: float = 1.0,
    dst_keys: Optional[KeyCollection] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
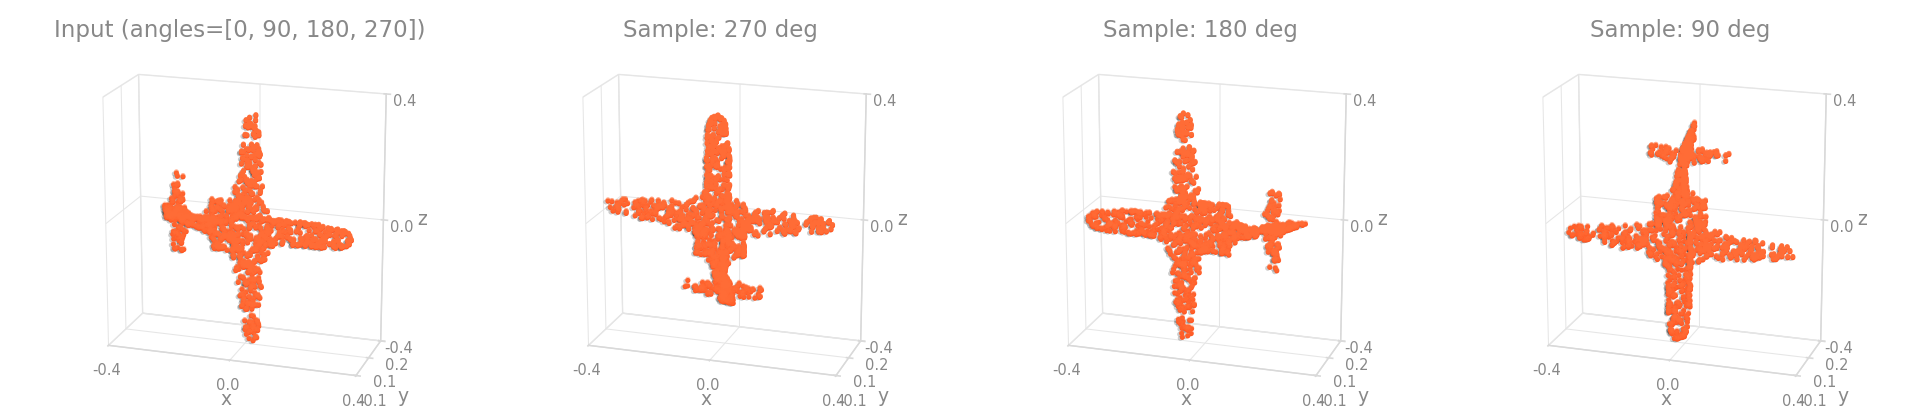
Rotate one or more keys by an angle chosen uniformly from a discrete list.
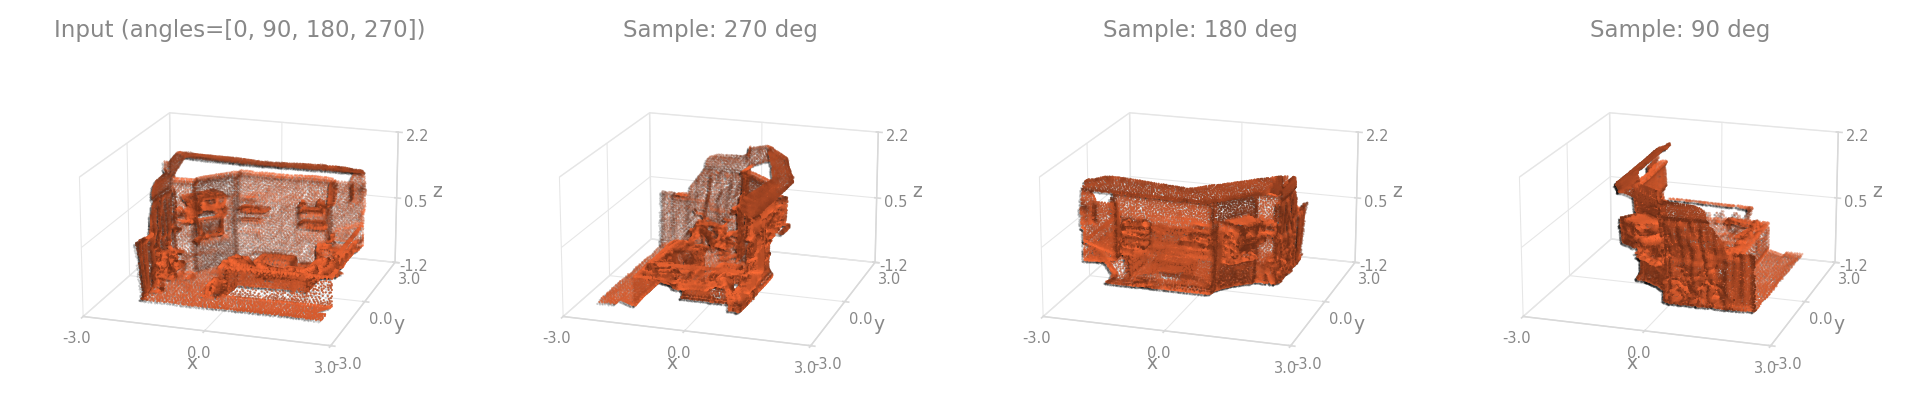
Common use: ModelNet / ScanObjectNN augmentation with angles=[0, 90, 180, 270] around the z-axis. Sampling is done once per call: every listed key gets the same rotation matrix.
See Also
torch_pointcloud.transforms.functional.rotation_matrix, torch_pointcloud.transforms.functional.rotate_vectors
Parameters:
-
keys(KeyCollection) –Keys to rotate. Each must have shape
(..., 3). -
angles(Sequence[float]) –Candidate rotation angles, in degrees. Must be non-empty.
-
axis(int, default:2) –Axis index to rotate around (0=X, 1=Y, 2=Z).
-
p(float, default:1.0) –Probability of applying the transform.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the rotated tensors. Defaults to
keys(in-place). -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomScale(
    keys: KeyCollection,
    scale_range: Tuple[float, float] = (0.8, 1.25),
    anisotropic: bool = False,
    axes: Optional[Sequence[int]] = None,
    p: float = 1.0,
    box_key: Optional[str] = None,
    dst_keys: Optional[KeyCollection] = None,
    dst_box_key: Optional[str] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
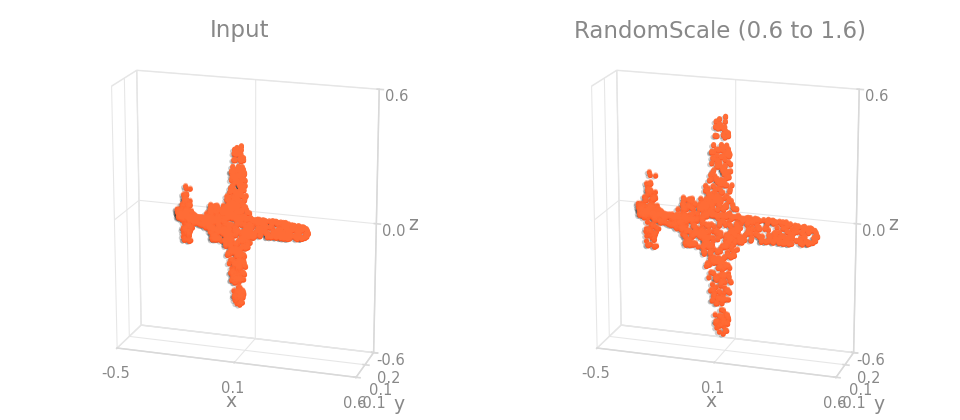
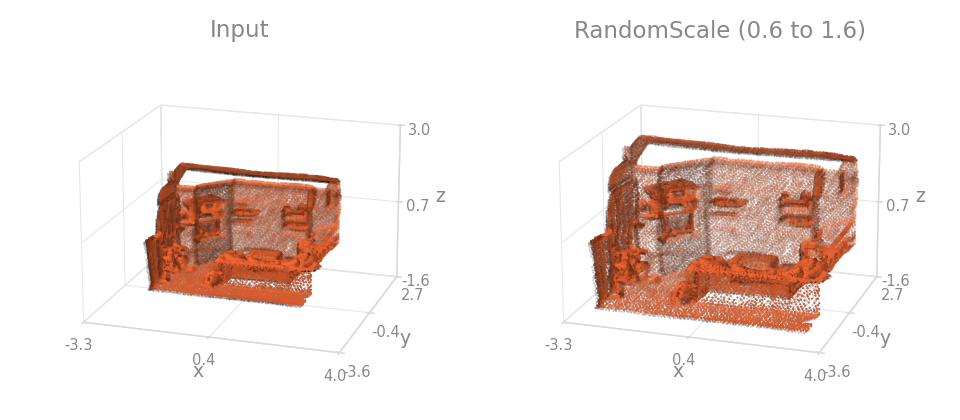
Scale one or more keys (and optionally oriented boxes) by a uniformly random factor.
Sampling is done once per call: every listed key and the optional box are scaled by the same factor (or per-axis factor vector when anisotropic=True). Pass box_key to also scale a \((K, 7)\) oriented-box tensor (centers and sizes). An oriented box has no per-axis scale, so box_key is incompatible with anisotropic=True.
List only point-like keys. Do not list direction vectors such as normal: a scaled normal is no longer unit length, while a true surface normal is unchanged by an isotropic scale (and an anisotropic scale would require the inverse-transpose rule). Simply omit normal keys.
See Also
torch_pointcloud.transforms.functional.scale_boxes
Parameters:
-
keys(KeyCollection) –Keys to scale. Point-like keys only; do not list direction vectors such as
normal. -
scale_range(Tuple[float, float], default:(0.8, 1.25)) –Min and max scaling factor.
-
anisotropic(bool, default:False) –If
True, sample a separate scale per axis of the last dim (incompatible withbox_key). -
axes(Optional[Sequence[int]], default:None) –Channels of the last dim that receive the factor, the others keep their values;
Nonescales them all (incompatible withanisotropicandbox_key). -
p(float, default:1.0) –Probability of applying the transform.
-
box_key(Optional[str], default:None) –Optional key of a \((K, 7)\) oriented-box tensor to scale jointly; a \((K, 9)\) tensor carries a planar velocity in its last two columns, scaled with the boxes.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the scaled tensors.
-
dst_box_key(Optional[str], default:None) –Where to store the scaled boxes. Defaults to
box_key(in-place). -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomTranslate(
    keys: KeyCollection,
    translation_range: Tuple[float, float] = (-0.2, 0.2),
    p: float = 1.0,
    box_key: Optional[str] = None,
    dst_keys: Optional[KeyCollection] = None,
    dst_box_key: Optional[str] = None,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
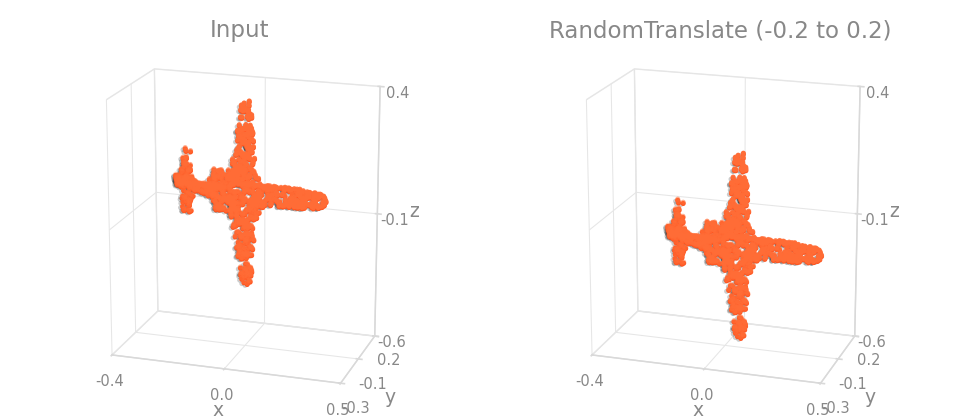
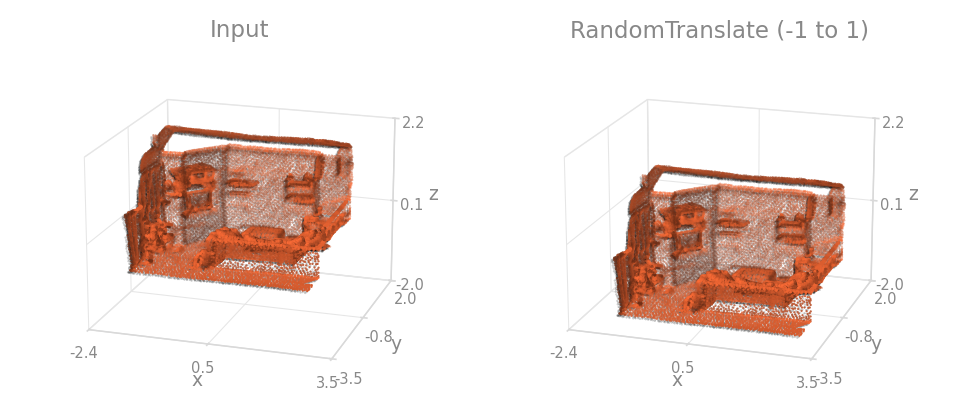
Translate listed keys (and optionally oriented boxes) by a uniformly random vector.
Sampling is done once per call: all listed keys and the optional box are shifted by the same translation vector. Pass box_key to also translate a \((K, 7)\) oriented-box tensor (centers only; sizes and heading unchanged).
List only point-like keys. Do not list direction vectors such as normal: directions are translation-invariant, so a shifted normal is wrong. Simply omit normal keys.
See Also
torch_pointcloud.transforms.functional.translate_boxes
Parameters:
-
keys(KeyCollection) –Keys to translate. Point-like keys only; do not list direction vectors such as
normal. -
translation_range(Tuple[float, float], default:(-0.2, 0.2)) –Min and max per-axis translation.
-
p(float, default:1.0) –Probability of applying the transform.
-
box_key(Optional[str], default:None) –Optional key of a \((K, 7)\) oriented-box tensor to translate jointly.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the shifted tensors.
-
dst_box_key(Optional[str], default:None) –Where to store the shifted boxes. Defaults to
box_key(in-place). -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Compose(
    transforms: Sequence[Transform],
    allow_missing_keys: Optional[bool] = None,
)
Bases: Transform, Randomizable
Compose multiple transforms into a single transform.
This class allows for chaining multiple transforms together.
Note
The order of the transforms is important, as each transform will be applied in the order they are added to the Compose object.
Parameters:
-
transforms(Sequence[Transform]) –The transforms to apply, in order.
-
allow_missing_keys(Optional[bool], default:None) –When set, assigned to every
DictTransformchild, recursively through nestedComposeobjects, overriding what each child was built with (assigning the attribute later does the same). Registered pipelines are shared objects, so setting it on one mutates its children for every user.Noneleaves the children as built.
Example
For example, to chain a random sample and a normalization transform, we can do the following:
Methods:
-
set_random_state–Seed every random transform of the pipeline, each from its own draw of the pipeline's stream.
-
transform–Apply the transforms to the input data.
Seed every random transform of the pipeline, each from its own draw of the pipeline's stream.
Parameters:
-
seed(Optional[int], default:None) –Seed of the pipeline's stream.
None(with nostate) returns every transform to the global generator. -
state(Optional[Generator], default:None) –Generator the pipeline draws the per-transform seeds from.
Returns:
-
Self–The pipeline itself, for chaining.
Bases: Transform
Base class for dictionary transforms.
This class is used to define transforms that operate on a dictionary of data, and implements utility methods for key iteration and error handling.
Note
allow_missing_keys controls the iteration over self.keys performed by iter_keys. Auxiliary keys read by individual transforms (e.g. mask_key in ApplyMask, pos_key in RemoveNearOrigin / FarthestPointSample, face_key in RandomSampleFaceVertices) document their own missing-key behavior in their respective docstrings.
Parameters:
-
keys(Optional[KeyCollection], default:None) –The keys to apply the transform to.
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if keys listed inself.keysare missing from the input dict.
Methods:
-
transform–Apply the transform to the dictionary data.
-
iter_keys–Iterate over
self.keyspresent in the data, honoringallow_missing_keys.
abstractmethod [source] 
Apply the transform to the dictionary data.
Parameters:
-
data(Dict[str, Any]) –The dictionary data to apply the transform to.
Returns:
-
Dict[str, Any]–The transformed dictionary data.
iter_keys(
    data: Dict[str, Any],
    *extra_iterables: Iterable[Any],
    extra_msg: str = "",
) -> Generator[Any, None, None]
Iterate over self.keys present in the data, honoring allow_missing_keys.
Parameters:
-
data(Dict[str, Any]) –The dictionary data the transform is applied to.
-
*extra_iterables(Iterable[Any], default:()) –Per-key values (e.g. one output key per input key) zipped with
self.keys. -
extra_msg(str, default:'') –Message appended to the
KeyErrorraised on a missing key.
Returns:
-
None–A generator yielding each present key, or a tuple of the key and its values from
-
None–extra_iterableswhen any is given.
RandomApply(
    transforms: Sequence[Transform],
    p: float = 0.5,
    seed: Optional[int] = None,
    allow_missing_keys: Optional[bool] = None,
)
Bases: Compose
Apply a pipeline of transforms with probability p, else return the data unchanged.
The transforms run in order, as in Compose, when a draw of the pipeline's random stream falls below p. It gates any transform, e.g. zeroing the normals of a shape one time in five: RandomApply([Scale(keys="normal", scale=0.0)], p=0.2).
Parameters:
-
transforms(Sequence[Transform]) –The transforms to apply, in order.
-
p(float, default:0.5) –Probability of applying the transforms.
-
seed(Optional[int], default:None) –Seed of the gate's random stream, which also seeds the transforms;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(Optional[bool], default:None) –Forwarded to the transforms, as
Composedoes.
Example
Methods:
-
transform–Apply the transforms to the input data with probability
p.
Base class for all point cloud transforms.
A transform is a callable that takes an arbitrary data object and returns a transformed version of it.
While any callable can be used as a transform, this class provides a common interface and some convenience features, such as:
- a
torch_pointcloud.transforms.base.Transform.transformmethod, which implements the actual transformation logic. It will be called by the__call__method to apply the transform. - a
torch_pointcloud.transforms.base.Transform.extra_reprmethod, which returns a string that describes the transform. This will be used by the__repr__method to represent the transform as a string.
Note
A transform should avoid modifying the input data in place. Instead, it should return a new object with the transformed data.
If the transform is in-place, it should be clearly stated in its documentation.
Note
Random transforms take a seed. None draws from the global generator, which PyTorch seeds per DataLoader worker and per epoch. An int gives the transform its own stream, re-derived inside each worker so that workers and epochs keep drawing different numbers (see Randomizable).
See Also
torch_pointcloud.transforms.DictTransform for a version of this class that operates on dictionaries.
Example
For example, to create a transform that scales the points in a point cloud, we can subclass the torch_pointcloud.transforms.Transform class and implement the torch_pointcloud.transforms.Transform.transform method as follows:
import torch
from torch import Tensor

from torch_pointcloud.transforms import Transform

# 1. Subclass the Transform class
class MyScale(Transform):
    def __init__(self, factor: float = 1.0):
        self.factor = factor

    def extra_repr(self) -> str:
        return f"factor={self.factor}"

    def transform(self, tensor: Tensor) -> Tensor:
        return tensor * self.factor

# 2. Initialize the transform
transform = MyScale()
# 3. Apply the transform
tensor = torch.randn(4096, 3)
tensor = transform(tensor)
Methods:
-
transform–Apply the transform to the input data.
InstanceToBox(
    instance_key: str = "instance",
    semantic_key: str = "segment",
    pos_key: str = "pos",
    dst_box_key: str = "box",
    dst_class_key: str = "label",
    ignore_index: int = -1,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
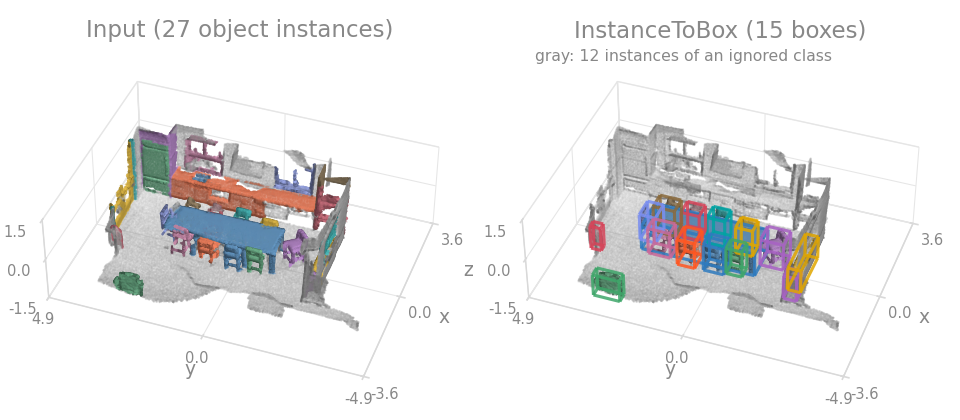
Axis-aligned bounding boxes from per-point instance ids (e.g. ScanNet detection targets).
Each distinct non-negative instance id in instance_key becomes one axis-aligned box covering its pos_key points: the center and full extents with heading \(0\), written to dst_box_key as \((K, 7)\) rows \([c_x, c_y, c_z, d_x, d_y, d_z, 0]\). The box class (the instance's most common semantic_key value) is written separately to dst_class_key as a \((K,)\) long tensor. Negative instance ids mark unlabeled points and never form a box. Instances whose class equals ignore_index are dropped, so mapping the stuff / non-target semantics to ignore_index with a Relabel upstream filters the boxes down to the detection classes.
Parameters:
-
instance_key(str, default:'instance') –Key of the \((N,)\) per-point instance ids.
-
semantic_key(str, default:'segment') –Key of the \((N,)\) per-point class labels the box class is read from.
-
pos_key(str, default:'pos') –Key of the \((N, 3)\) coordinates.
-
dst_box_key(str, default:'box') –Key to write the \((K, 7)\) boxes to.
-
dst_class_key(str, default:'label') –Key to write the \((K,)\) per-box classes to.
-
ignore_index(int, default:-1) –Class value whose instances are dropped (e.g. unlabeled / stuff).
-
allow_missing_keys(bool, default:False) –If
True, return the data unchanged when an input key is missing instead of raising.
PasteBoxes(
    objects: Sequence[Mapping[str, Tensor]],
    num_samples: Mapping[int, int],
    keys: KeyCollection = POS,
    box_key: str = BOX,
    label_key: str = LABEL,
    attribute_keys: Optional[KeyCollection] = None,
    count_existing: bool = True,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Paste objects cut out by cut_boxes into the scene, a target number per label.
For each label of num_samples, objects are drawn at random from objects and pasted: the scene points inside their boxes are removed, the object points, moved to their box center, are placed before the remaining scene points with their features, and the boxes, labels and attributes are appended. A drawn object whose box overlaps in bird's-eye view a box of the scene or of another drawn object is left out. With count_existing the objects of a label already in the scene count towards its target, otherwise the target is pasted in full. Per-box keys of the scene other than box_key, label_key and attribute_keys are not extended: drop them beforehand (e.g. with KeepItems).
Parameters:
-
objects(Sequence[Mapping[str, Tensor]]) –Objects of
cut_boxes, holdingkeys,box_key,label_keyandattribute_keys. -
num_samples(Mapping[int, int]) –Target number of objects per label,
{label: count}. -
keys(KeyCollection, default:POS) –Point keys pasted: the coordinates first, then the features.
-
box_key(str, default:BOX) –Key of the boxes.
-
label_key(str, default:LABEL) –Key of the labels.
-
attribute_keys(Optional[KeyCollection], default:None) –Per-box keys appended with the attributes of the pasted objects (e.g. a velocity).
-
count_existing(bool, default:True) –Count the objects already in the scene towards the targets.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Example
import torch
import torch_pointcloud.transforms as T
import torch_pointcloud.transforms.functional as F

scene = {
    "pos": torch.randn(1000, 3) * 10,
    "intensity": torch.rand(1000, 1),
    "box": torch.tensor([[2.0, 0.0, 0.0, 4.0, 2.0, 1.5, 0.0], [10.0, 5.0, 0.0, 1.0, 1.0, 2.0, 0.3]]),
    "label": torch.tensor([0, 1]),
}
objects = F.cut_boxes(scene, keys=["pos", "intensity"])  # from one scene here, from a dataset in practice
paste = T.PasteBoxes(objects, num_samples={0: 20, 1: 15}, keys=["pos", "intensity"])
out = paste(scene)
print(out["box"].shape[0])
RelabelBoxes(
    keys: KeyCollection,
    mapping: Dict[int, int],
    *,
    label_key: str = LABEL,
    ignore_mapping: Optional[Dict[int, int]] = None,
    ignore_fields: Optional[
        Dict[str, Tuple[Optional[float], Optional[float]]]
    ] = None,
    dst_ignore_mask_key: str = "ignore_mask",
    allow_missing_keys: bool = False,
)
Bases: DictTransform
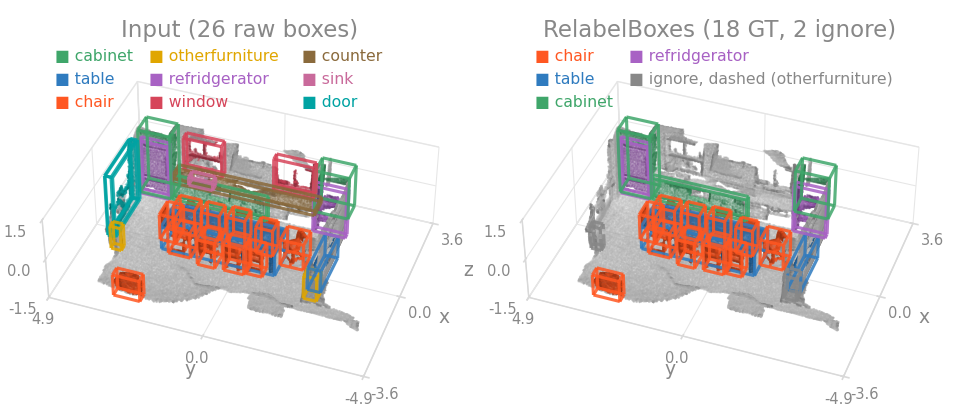
Map raw box labels to a detection class set and flag don't-care boxes for the AP metric.
A detection dataset (e.g. KITTI) returns the raw annotated boxes: every labeled class plus per-box attributes such as occlusion / truncation. This transform turns those into the inputs the 3D AP metric expects, the way Relabel turns raw segmentation ids into a benchmark label set:
- boxes whose raw label is a key of
mappingare kept as ground truth, relabeled tomapping[raw]; - boxes whose raw label is a key of
ignore_mapping(neighboring classes, e.g. KITTIVanforCar) are kept as ignore regions (ignore_mask = True), labeledignore_mapping[raw]: the evaluated class they excuse. They suppress false positives of that class but are not scored; - a kept foreground box that falls outside any range in
ignore_fields(e.g. KITTI's moderate rule: occlusion \(\le 1\), truncation \(\le 0.3\), 2D height \(\ge 25\) px) is downgraded to an ignore region attributed to its mapped class; - every other box is dropped.
All keys in keys (the box tensor and every per-box attribute, including those named in ignore_fields) are filtered together by the keep mask so they stay row-aligned. The output adds the boolean dst_ignore_mask_key consumed by box_matches, which excuses an unmatched prediction only on ignore boxes labeled with its class.
Parameters:
-
keys(KeyCollection) –Per-box tensors to filter together (e.g.
DataKeys.BOX,DataKeys.LABEL,DataKeys.TRUNCATION,DataKeys.OCCLUSION). Must includelabel_keyand every key referenced byignore_fields. -
mapping(Dict[int, int]) –Raw-label to detection-label dict; raw labels absent from it (and from
ignore_mapping) are dropped. -
label_key(str, default:LABEL) –Key holding the raw integer labels (must be one of
keys). -
ignore_mapping(Optional[Dict[int, int]], default:None) –Raw labels kept as ignore regions rather than scored ground truth, mapped to the detection class they excuse (e.g. KITTI
Vanto theCarclass index). -
ignore_fields(Optional[Dict[str, Tuple[Optional[float], Optional[float]]]], default:None) –Per-attribute inclusive ranges
{key: (low, high)}(useNonefor an open side); a foreground box outside any range becomes an ignore region. -
dst_ignore_mask_key(str, default:'ignore_mask') –Output key for the written boolean ignore mask.
-
allow_missing_keys(bool, default:False) –If
True, skip missing keys instead of raising.
Example
import torch_pointcloud.transforms as T

# KITTI: raw 8-class boxes -> 3 detection classes, Van / Person_sitting as ignore regions
# for Car / Pedestrian, moderate difficulty (occlusion <= 1, truncation <= 0.3,
# height >= 25 px) as ignore.
T.RelabelBoxes(
    keys=("box", "label", "truncation", "occlusion", "bbox_height"),
    mapping={0: 0, 3: 1, 5: 2},
    ignore_mapping={1: 0, 4: 1},
    ignore_fields={
        "occlusion": (None, 1),
        "truncation": (None, 0.3),
        "bbox_height": (25, None),
    },
)
AxisMinOffset(
    keys: KeyCollection,
    axis: ValueCollection[int],
    quantile: Optional[float] = None,
    dst_keys: KeyCollection | None = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
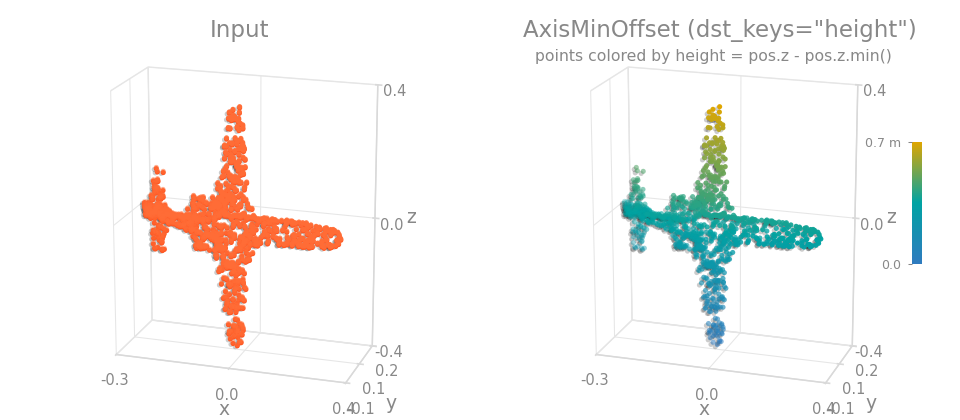
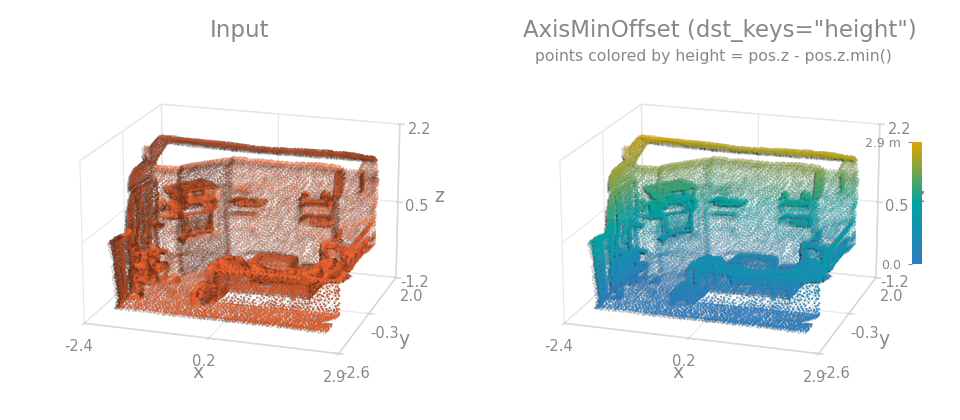
Per-point offset from a floor reference along a chosen coordinate axis.
For each point and a given axis \(a\) along tensor dimension \(d\), computes:
where the floor reference \(r\) is either the strict minimum \(\min_j p_{j,a}\) (default) or, when quantile is set, the empirical quantile \(Q_q(p_{\cdot,a})\). A small positive quantile gives an outlier-robust floor estimate.
The result has the same shape as the input with the coordinate dimension reduced to size 1 (e.g. \((N, 3) \to (N, 1)\) or \((B, N, 3) \to (B, N, 1)\)). For batched inputs, the minimum is computed per-sample.
Parameters:
-
keys(KeyCollection) –Keys holding point positions of shape \((N, D)\).
-
axis(ValueCollection[int]) –Coordinate axis \(a\) along which to compute the offset.
-
quantile(Optional[float], default:None) –Optional quantile \(q \in [0, 1]\) for the floor reference. When
None, the strict per-axis minimum is used. -
dst_keys(KeyCollection | None, default:None) –Keys under which the offset tensors are stored. Defaults to
keys(in-place overwrite). -
allow_missing_keys(bool, default:False) –If True, skip missing keys instead of raising.
Example
Let's say you have a point cloud with positions \((N, 3)\) in XYZ order and you want to compute the offset from the minimum along the z-axis, i.e. computing the height above the local floor.
import torch
from torch_pointcloud.transforms import AxisMinOffset

data = {
    "pos": torch.randn(10, 3),
}
transform = AxisMinOffset(keys="pos", dst_keys="pos_offset", axis=2)
data = transform(data)
Now, the data dictionary will contain the key pos_offset with the shape \((N, 1)\).
BBoxCenter(
    keys: KeyCollection,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
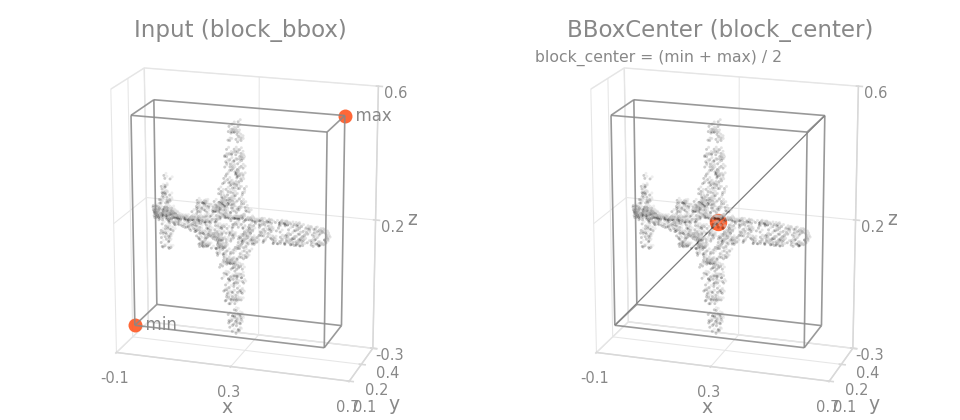
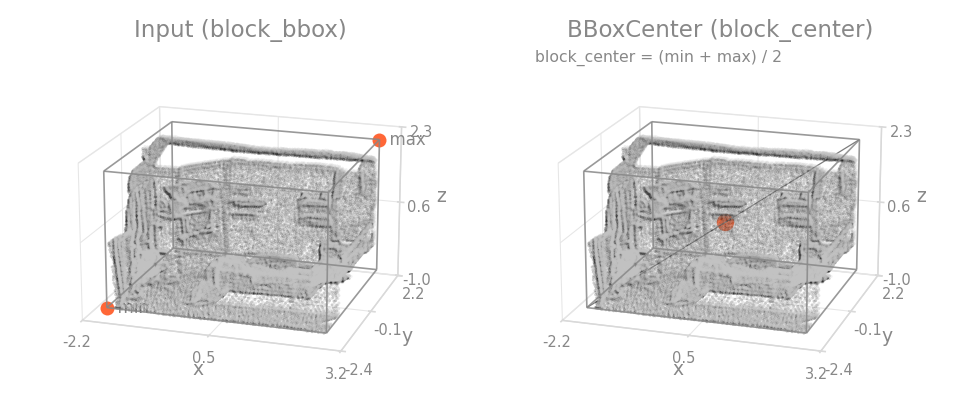
Derive the center of an axis-aligned bbox stored as a flat tensor.
Reads a bbox at each source key, laid out as a \((2D,)\) vector \([\,\min_0, \ldots, \min_{D-1},\, \max_0, \ldots, \max_{D-1}\,]\), and writes the per-axis midpoint \((\min + \max) / 2\) (shape \((D,)\)) at the matching destination key.
Parameters:
-
keys(KeyCollection) –Source keys holding flat bbox tensors of shape \((2D,)\).
-
dst_keys(Optional[KeyCollection], default:None) –Destination keys for the centers. Defaults to overwriting the source keys.
-
allow_missing_keys(bool, default:False) –If
True, silently skip absent source keys.
Example
EstimateNormals(
    keys: KeyCollection,
    dst_keys: KeyCollection = "normal",
    k: int = 16,
    orient_to_centroid: bool = False,
    batch_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
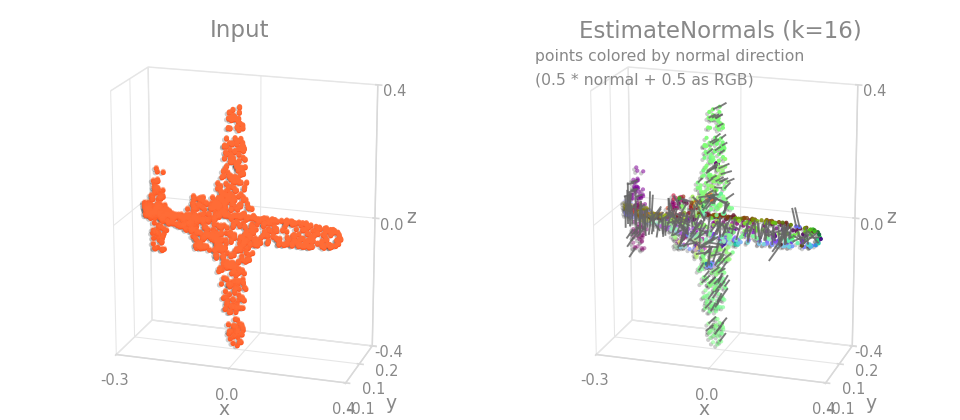
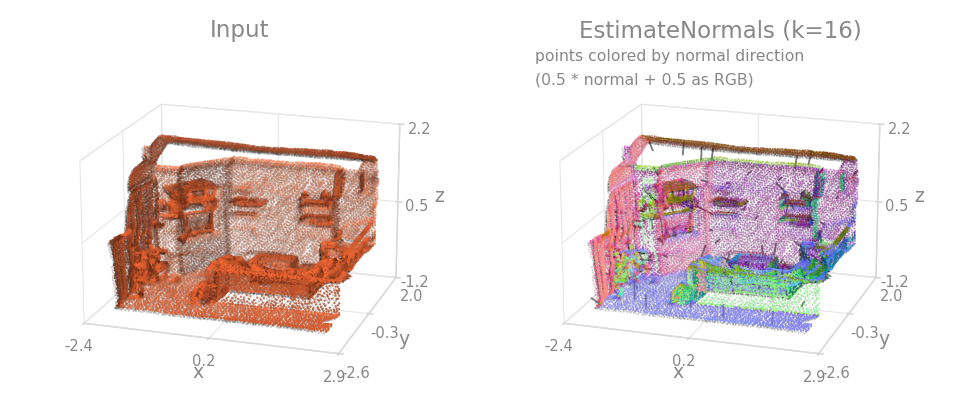
Estimate per-point surface normals from coordinates via local PCA.
Computes unit normals (see torch_pointcloud.transforms.functional.estimate_normals) for clouds that ship without them (e.g. S3DIS). Each normal is the least-variance direction of a point's \(k\) nearest neighbors. With orient_to_centroid, normals are flipped to face the cloud centroid.
See Also
torch_pointcloud.transforms.functional.estimate_normals
Parameters:
-
keys(KeyCollection) –Coordinate keys to estimate normals from.
-
dst_keys(KeyCollection, default:'normal') –Keys under which to store the normals (one per coordinate key). Defaults to
normal. -
k(int, default:16) –Number of nearest neighbors (the point itself included) per local PCA.
-
orient_to_centroid(bool, default:False) –If
True, flip each normal to point towards its cloud's centroid (approximates the inward-facing normals of meshes scanned from inside a room). -
batch_key(Optional[str], default:None) –Optional key holding a per-point batch index so neighbors stay within a cloud.
-
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Quantize(
    keys: KeyCollection,
    size: float,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
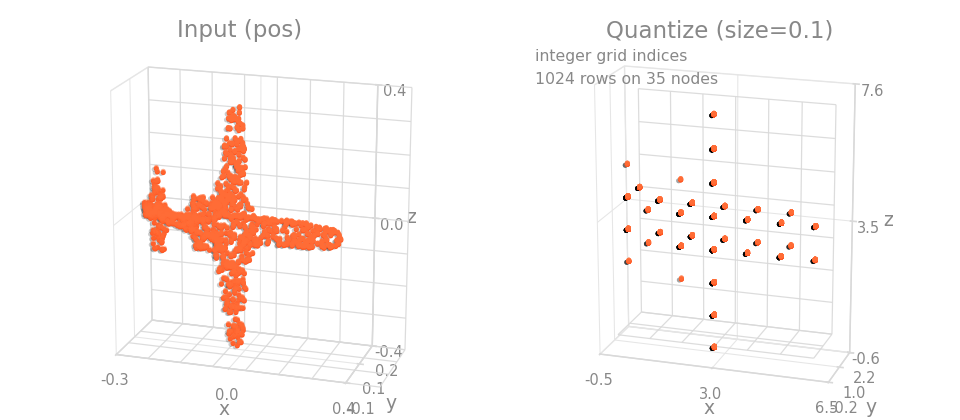
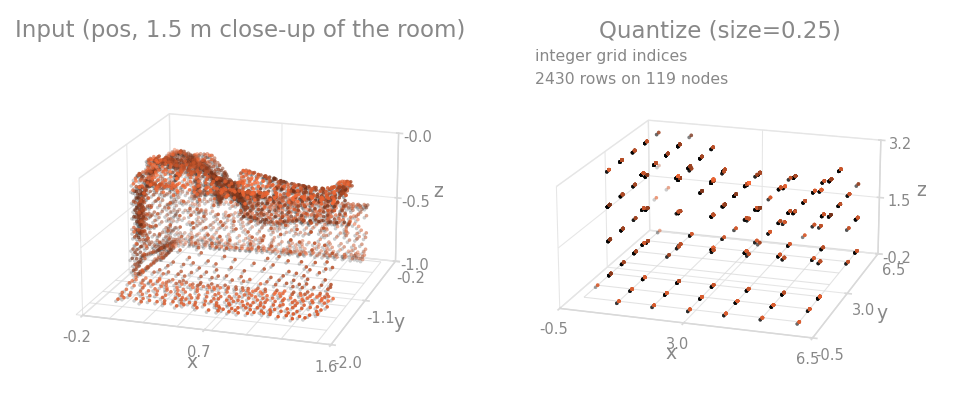
Integer voxel-grid coordinates of every point, keeping the cloud at full resolution.
Stores \(\lfloor p / s \rfloor\) (shifted so the per-axis minimum is \(0\)) for each point of keys under dst_keys. Unlike Voxelize, no reduction happens: points sharing a voxel keep their own rows and get equal coordinates. This is how a voxel-partition evaluation feeds sparse models with every raw point (each sub-cloud holds one point per voxel, so its rows are exactly the voxels), and how test-time views recompute grid coordinates after rotating or scaling the positions.
Parameters:
-
keys(KeyCollection) –Keys holding point positions of shape \((N, D)\).
-
size(float) –Voxel side length in the units of the positions.
-
dst_keys(Optional[KeyCollection], default:None) –Keys under which the grid coordinates are stored. Defaults to
keys(in-place overwrite). -
allow_missing_keys(bool, default:False) –If
True, missing keys are skipped.
Example
Shift(
    keys: KeyCollection,
    method: ValueCollection[ShiftMethod],
    dim: int = 0,
    axes: Optional[Sequence[int]] = None,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
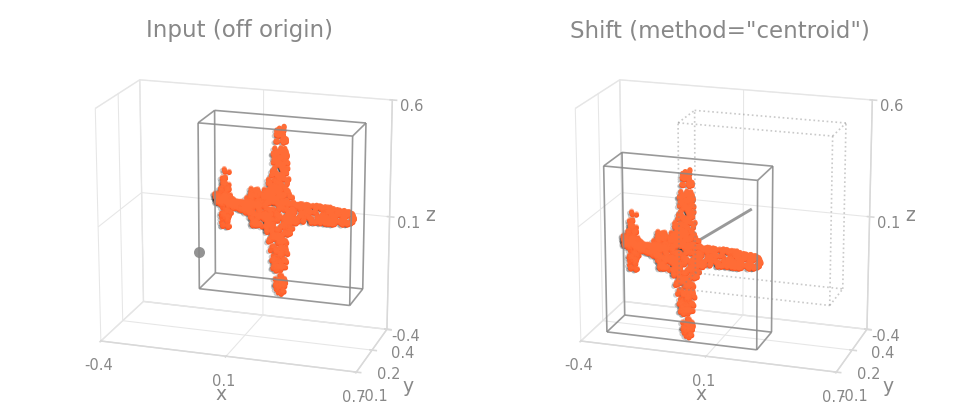
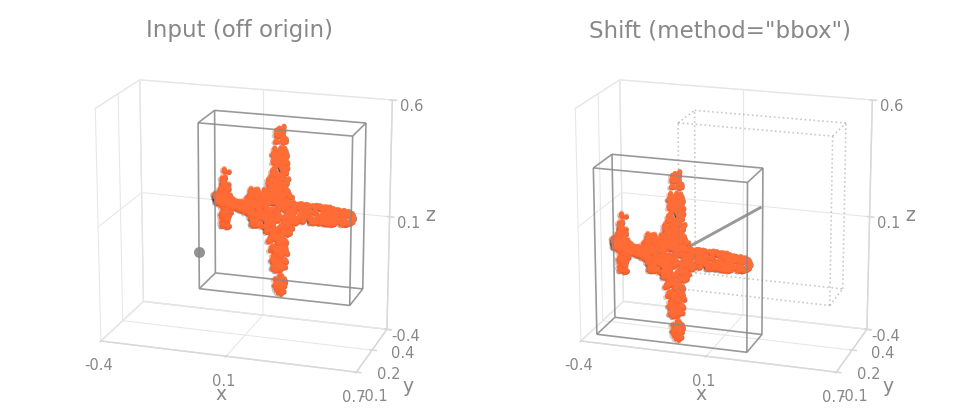
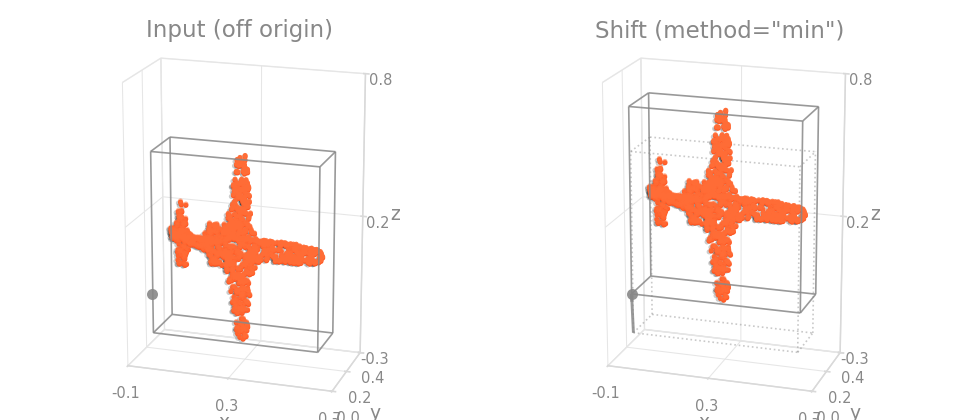
Shift dictionary tensor entries by subtracting a computed offset.
Each key is offset independently. The offset is determined by method:
| Method | Offset |
|---|---|
"bbox" | Midrange: (min + max) / 2 |
"centroid" | Mean across the reduced dimension |
"min" | Per-axis minimum (shifts to the positive octant) |
On empty inputs (size \(0\) along dim) the tensor is returned unchanged.
Parameters:
-
keys(KeyCollection) –The keys to shift.
-
method(ValueCollection[ShiftMethod]) –"bbox"(midrange),"centroid"(mean), or"min"(shift to origin). -
dim(int, default:0) –The dimension to reduce over.
-
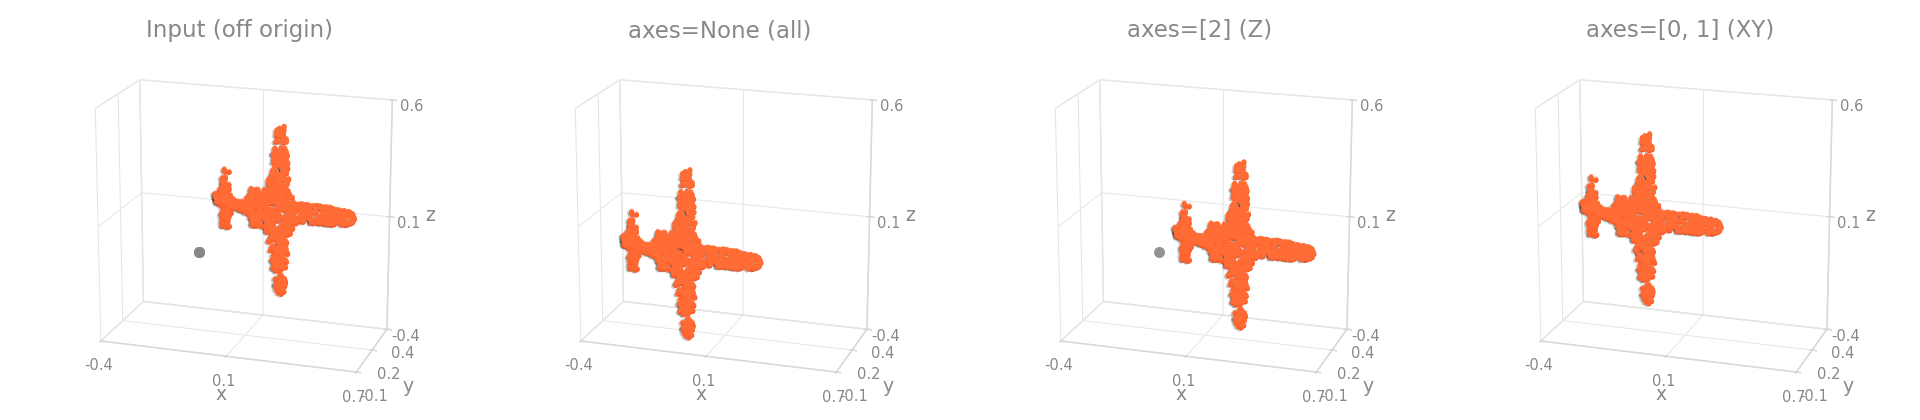
axes(Optional[Sequence[int]], default:None) –Which axes (last-dim indices) to shift.
None(default) shifts every axis; pass e.g.axes=[0, 1]to recenter only XY. Axes outside this list are left unchanged - this is the composable knob for mixed-method shifts. -
dst_keys(Optional[KeyCollection], default:None) –The keys to store the shifted data in.
-
allow_missing_keys(bool, default:False) –If
True, skip missing keys silently.
Example
XY shifted by the bbox midpoint, Z shifted by its minimum (equivalent to the old CenterShift(apply_z=True)):
from torch_pointcloud.transforms import Compose, Shift

center_shift = Compose([
    Shift(keys="pos", method="bbox", axes=[0, 1]),  # XY: bbox midrange
    Shift(keys="pos", method="min",  axes=[2]),     # Z:  min
])
Without the Z step (equivalent to the old CenterShift(apply_z=False)), a single Shift suffices:
Translate(
    keys: KeyCollection,
    offset: Union[float, Sequence[float]],
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Add a constant offset to dictionary tensor entries.
The deterministic counterpart of RandomTranslate and of Shift, whose offsets come from the data; after a Shift to the minimum, Translate(keys="pos", offset=(-0.75, -0.75, 0.0)) centers a 1.5 m block on its middle.
Parameters:
-
keys(KeyCollection) –The keys to translate.
-
offset(Union[float, Sequence[float]]) –Offset added to every row, a scalar or one value per channel of the last dimension.
-
dst_keys(Optional[KeyCollection], default:None) –The keys to store the translated data in.
-
allow_missing_keys(bool, default:False) –If
True, skip missing keys silently.
Example
ApplyMask(
    keys: KeyCollection,
    mask_key: str,
    dst_keys: Optional[KeyCollection] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
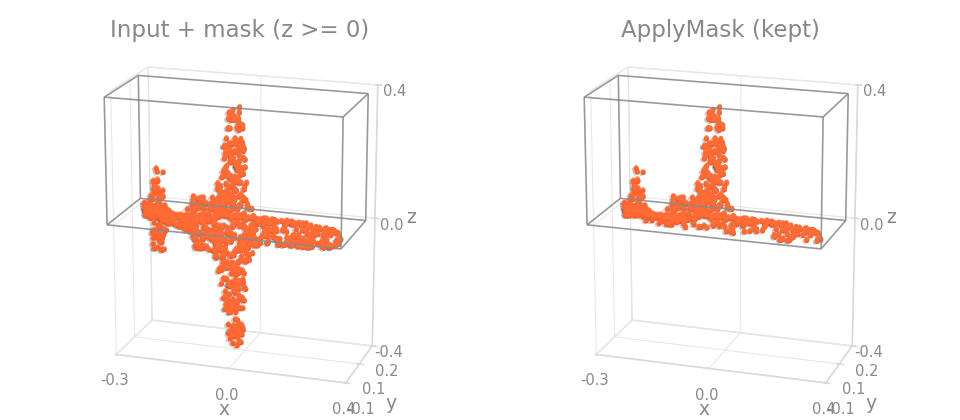
Apply a mask stored in a dictionary to other dictionary entries.
See Also
torch_pointcloud.transforms.functional.apply_mask
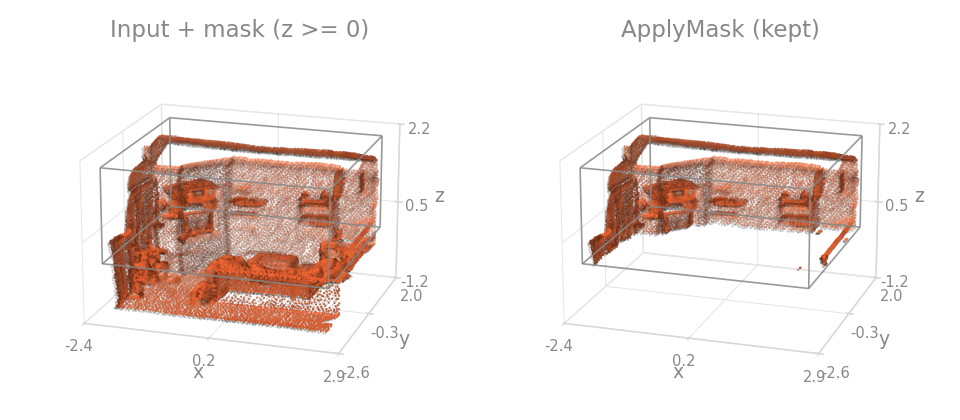
Parameters:
-
keys(KeyCollection) –The keys to apply the mask to.
-
mask_key(str) –The key containing the mask.
-
dst_keys(Optional[KeyCollection], default:None) –The keys to store the transformed data in.
-
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. Leave it unset whendst_keysdiffer fromkeys, since the map would describe thedst_keysrows. -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
BoxMask(
    keys: KeyCollection,
    bbox: tuple[float, ...],
    dst_keys: Optional[KeyCollection] = None,
    dim: int = -1,
    strict: bool = False,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
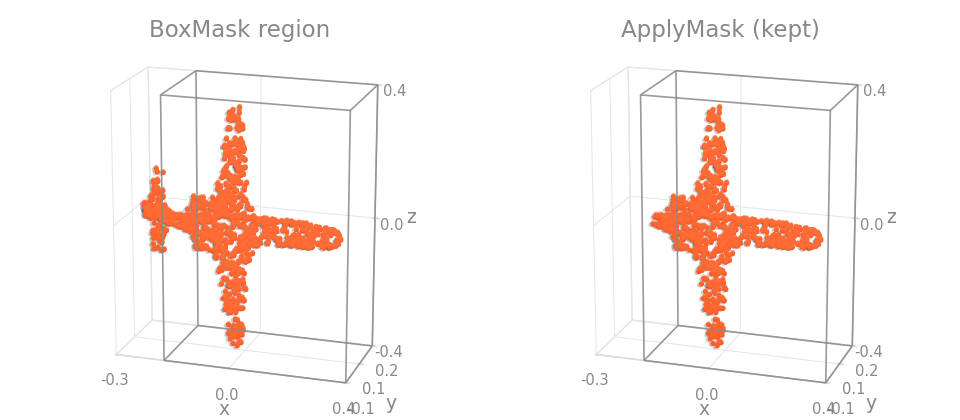
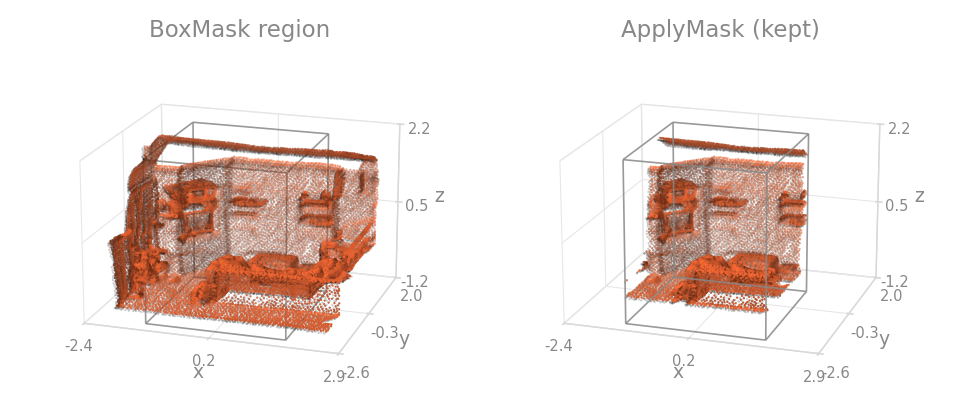
Create a boolean mask for points inside an axis-aligned bounding box (AABB).
Membership condition along dim (default, boundary points included):
where bbox = (*bbmin, *bbmax) is the AABB. With strict=True the inequalities are strict, so boundary points are excluded.
Sibling masks:
CubeMask- L∞ ball (center + radius)SphereMask- L2 ball (center + radius)
See Also
torch_pointcloud.transforms.functional.box_mask
Parameters:
-
keys(KeyCollection) –The keys to create the mask for.
-
bbox(tuple[float, ...]) –The bounding box used to mask input tensors, as
(*bbmin, *bbmax). -
dst_keys(Optional[KeyCollection], default:None) –The keys to store the mask in.
-
dim(int, default:-1) –The dimension to create the mask over.
-
strict(bool, default:False) –If
True, use strict inequalities (points exactly on the boundary are excluded). -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
CubeMask(
    keys: KeyCollection,
    center: ValueCollection[float],
    radius: float,
    dim: int = -1,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
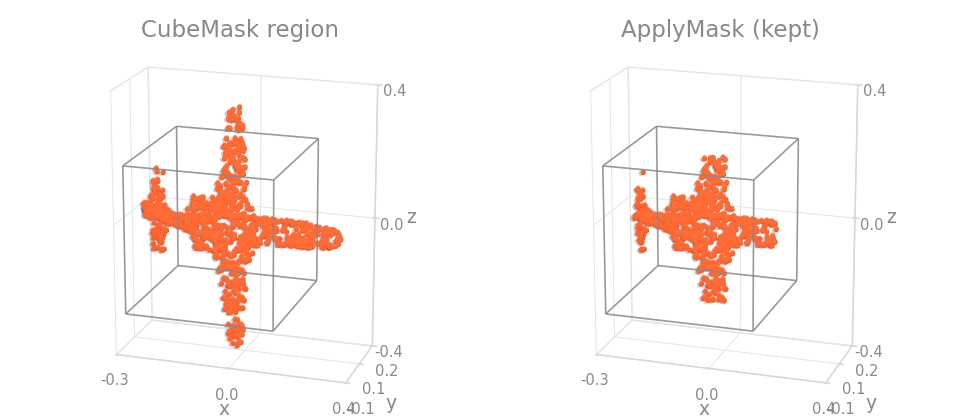
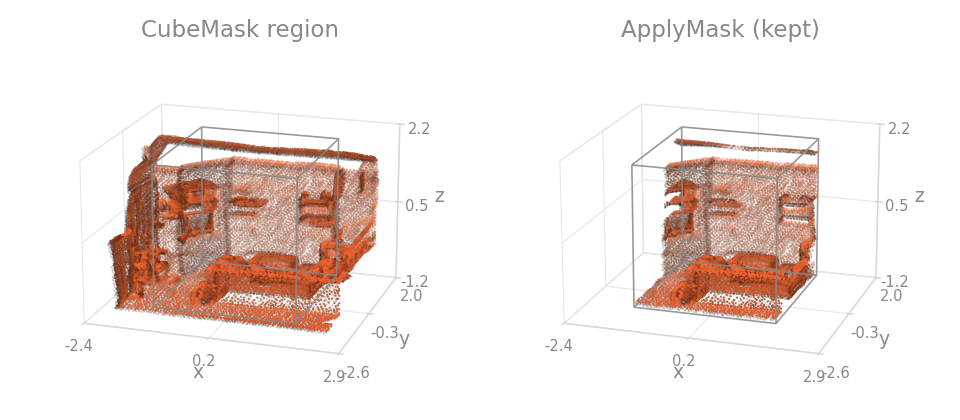
Create a boolean mask for points inside an axis-aligned cube (L∞ / Chebyshev ball).
Membership condition along dim:
Geometrically, the L∞ ball of radius \(r\) centered at \(c\) is a hypercube with edge \(2r\) aligned to the axes. Pair with SphereMask (L2) and BoxMask (AABB) for the mask family.
See Also
torch_pointcloud.transforms.functional.cube_mask
Parameters:
-
keys(KeyCollection) –The keys to create the mask for.
-
center(ValueCollection[float]) –The center of the cube.
-
radius(float) –The radius (half-edge) of the cube.
-
dim(int, default:-1) –The dimension to create the mask over.
-
dst_keys(Optional[KeyCollection], default:None) –The keys to store the mask in.
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
RemoveNearOrigin(
    pos_key: str,
    keys: Optional[KeyCollection] = None,
    radius: float = 0.001,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
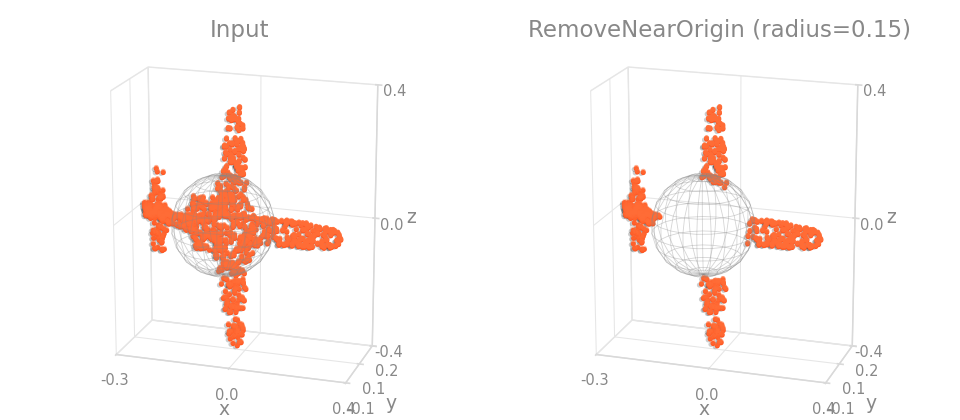
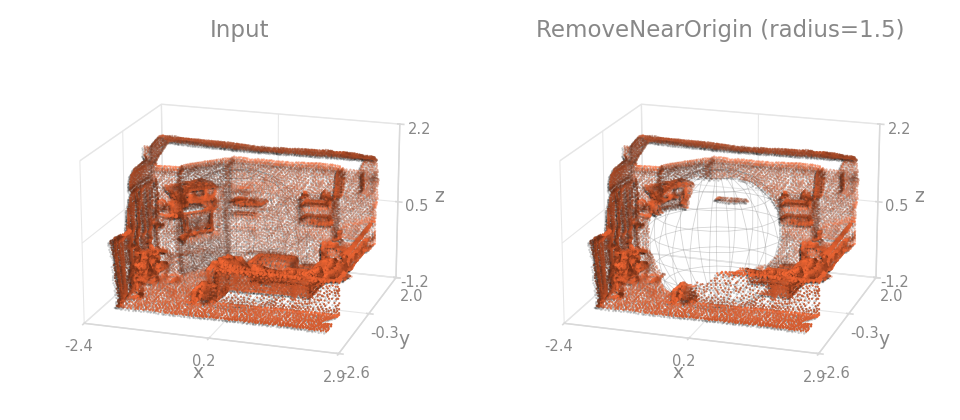
Remove points that are within a given radius of the origin from dictionary entries.
See Also
torch_pointcloud.transforms.functional.remove_near_origin
Parameters:
-
pos_key(str) –The key containing the positions / coordinates, used to compute the distance from the origin.
-
keys(Optional[KeyCollection], default:None) –Extra keys to filter with the same mask.
-
radius(float, default:0.001) –The radius of the sphere.
-
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
SphereMask(
    keys: KeyCollection,
    center: ValueCollection[float],
    radius: float,
    dim: int = -1,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
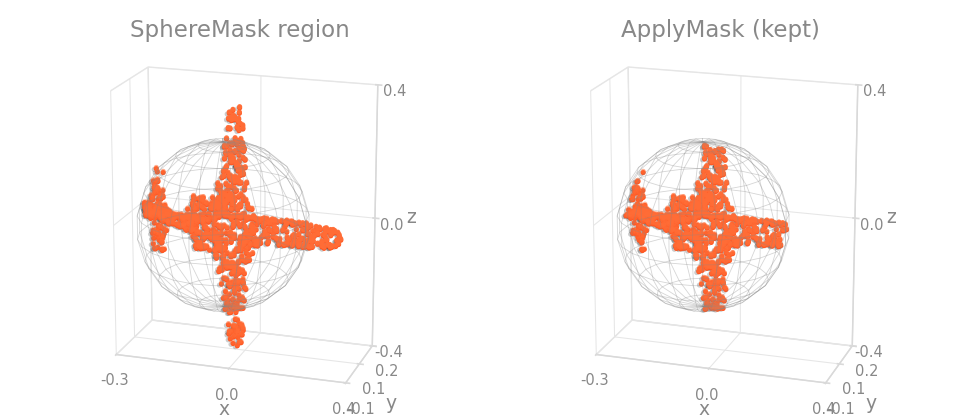
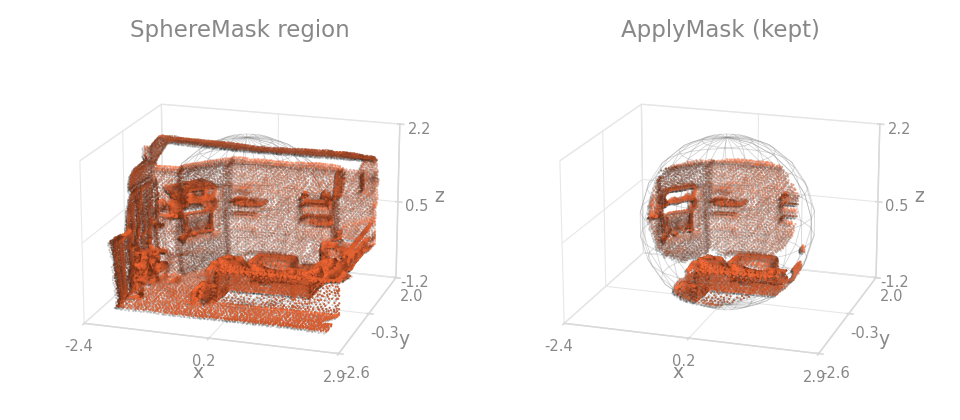
Create a boolean mask for points inside an L2 (Euclidean) ball.
Membership condition along dim:
Pair with CubeMask (L∞) and BoxMask (AABB) for the mask family. RemoveNearOrigin(radius=r) is equivalent to Compose([SphereMask(center=(0,0,0), radius=r, invert=True), ApplyMask(...)]).
See Also
torch_pointcloud.transforms.functional.sphere_mask
Parameters:
-
keys(KeyCollection) –The keys to create the mask for.
-
center(ValueCollection[float]) –The center of the sphere.
-
radius(float) –The radius of the sphere.
-
dim(int, default:-1) –The dimension to compute the Euclidean norm over.
-
dst_keys(Optional[KeyCollection], default:None) –The keys to store the mask in.
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
LaserMix(
    keys: KeyCollection,
    num_areas: Sequence[int],
    pitch_range: Tuple[float, float],
    pos_key: str = "pos",
    p: float = 1.0,
    seed: Optional[int] = None,
)
Bases: Transform, Randomizable
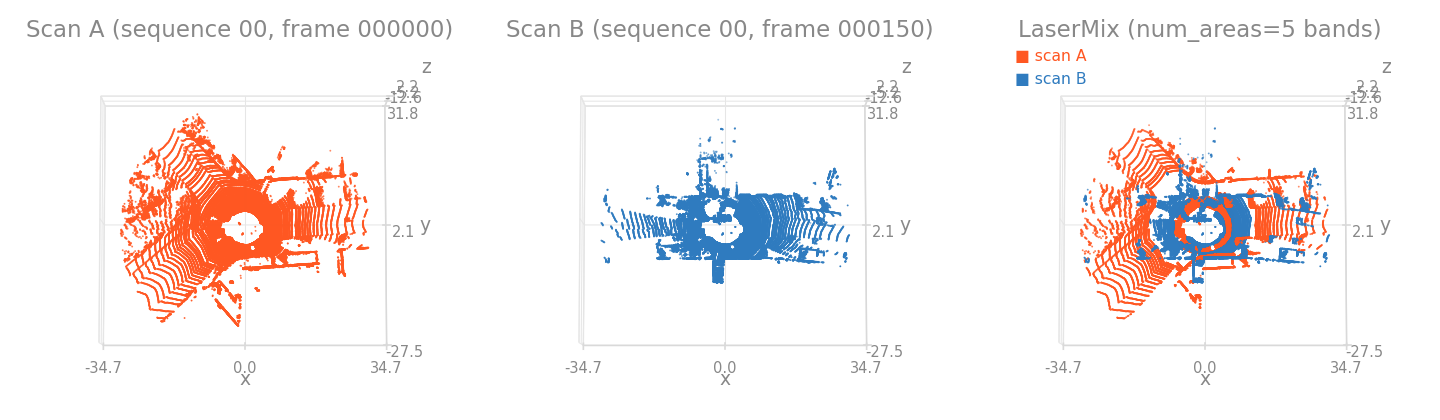
Mix two LiDAR scans by swapping alternating inclination (pitch) bands.
LaserMix for Semi-Supervised LiDAR Semantic Segmentation
Both scans are partitioned into num_areas inclination bands (one count is drawn per call), and alternating bands are taken from each scan so the mixed scene tiles the full field of view. Every key in keys is masked with the same per-scan selection, keeping per-point correspondence.
See Also
torch_pointcloud.transforms.functional.laser_mix_masks
Parameters:
-
keys(KeyCollection) –Point-aligned keys masked jointly (must include
pos_key). -
num_areas(Sequence[int]) –Candidate band counts; one is sampled uniformly per call.
-
pitch_range(Tuple[float, float]) –Inclination range
(min, max)in degrees. -
pos_key(str, default:'pos') –Key of the coordinates used to compute inclination bands.
-
p(float, default:1.0) –Probability of applying the mix; below it the first scene is returned unchanged.
-
seed(Optional[int], default:None) –Seed for the band count, parity and probability draws;
Nonedraws from the global generator (seeRandomizable).
Shape
- each key in
keys: \((N, \ldots)\) and \((M, \ldots)\) inputs, \((N' + M', \ldots)\) output.
Example
import torch
import torch_pointcloud.transforms as T

a = {"pos": torch.randn(100, 3), "segment": torch.randint(0, 10, (100,))}
b = {"pos": torch.randn(120, 3), "segment": torch.randint(0, 10, (120,))}
mix = T.LaserMix(keys=("pos", "segment"), num_areas=(3, 4, 5, 6), pitch_range=(-25.0, 3.0))
out = mix(a, b)
Mix3D(
    keys: KeyCollection,
    instance_key: Optional[str] = "instance",
    ignore_index: int = -1,
    p: float = 1.0,
    seed: Optional[int] = None,
)
Bases: Transform, Randomizable
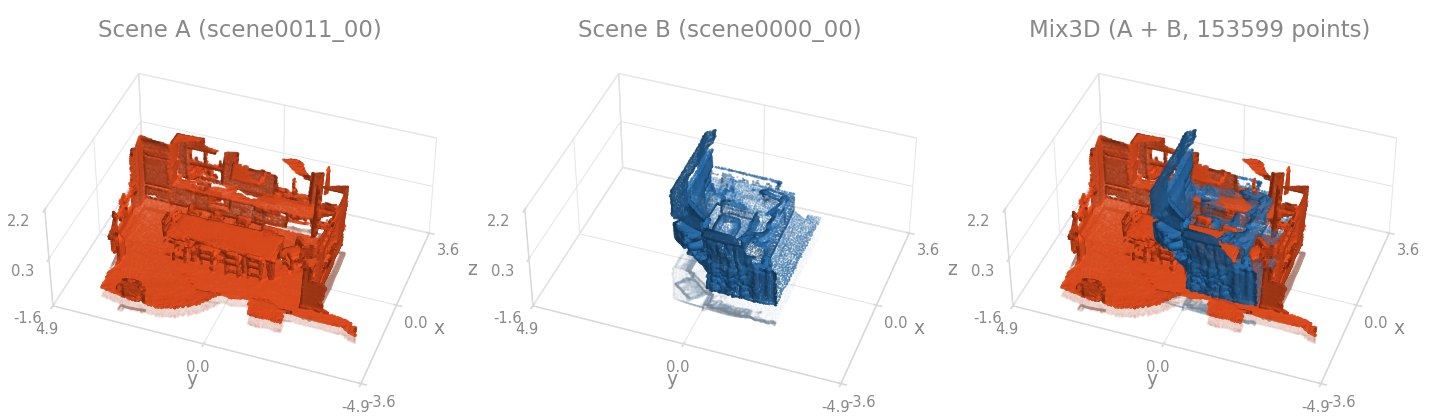
Concatenate two scenes into one, offsetting the second scene's instance ids.
Mix3D: Out-of-Context Data Augmentation for 3D Scenes
Every point-aligned key in keys is concatenated along the point dimension, so the mixed scene holds all points of both inputs. When instance_key is present in both scenes, the second scene's instance ids are shifted past the first scene's maximum id so the merged instances stay disjoint; points labeled ignore_index keep that label and are excluded from the offset.
Unlike the other pairwise mixes, Mix3D keeps all points of both scenes, so the mixed scene has roughly twice as many points as either input.
Parameters:
-
keys(KeyCollection) –Point-aligned keys concatenated jointly (e.g.
pos,color,normal,segment). -
instance_key(Optional[str], default:'instance') –Key of per-point instance ids to offset, or
Noneto skip instance handling. -
ignore_index(int, default:-1) –Instance id treated as "no instance" (kept as-is, ignored by the offset).
-
p(float, default:1.0) –Probability of applying the mix; below it the first scene is returned unchanged.
-
seed(Optional[int], default:None) –Seed for the probability draw;
Nonedraws from the global generator (seeRandomizable).
Shape
- each key in
keys: \((N, \ldots)\) and \((M, \ldots)\) inputs, \((N + M, \ldots)\) output.
Example
PolarMix(
    keys: KeyCollection,
    instance_classes: Sequence[int],
    swap_ratio: float = 0.5,
    rotate_paste_ratio: float = 1.0,
    pos_key: str = "pos",
    segment_key: str = "segment",
    p: float = 1.0,
    seed: Optional[int] = None,
)
Bases: Transform, Randomizable
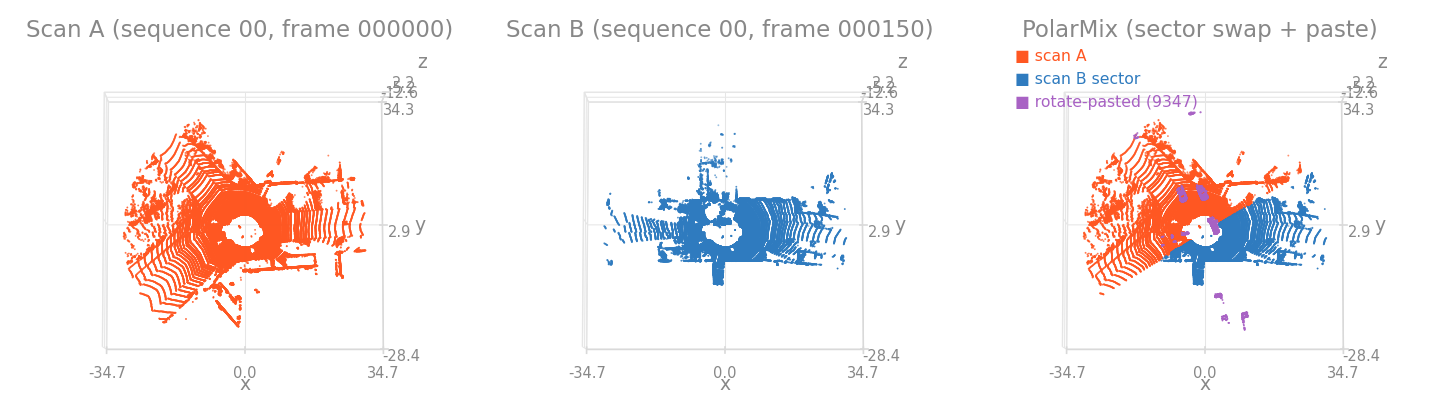
Mix two LiDAR scans by swapping an azimuth sector and rotate-pasting instance-class points.
PolarMix: A General Data Augmentation Technique for LiDAR Point Clouds
Two independent sub-augmentations run per call. With probability swap_ratio, a random azimuth half-sector of the first scan is replaced by the same sector of the second scan. With probability rotate_paste_ratio, points of the second scan whose segment_key label is in instance_classes are rotated by a random angle about the up axis and appended. Only pos_key is rotated for the pasted points; the other keys are copied unchanged.
See Also
torch_pointcloud.transforms.functional.polar_mix_masks
Parameters:
-
keys(KeyCollection) –Point-aligned keys masked and concatenated jointly (must include
pos_key). -
instance_classes(Sequence[int]) –Semantic labels whose points are rotate-pasted from the second scan.
-
swap_ratio(float, default:0.5) –Probability of swapping the azimuth sector.
-
rotate_paste_ratio(float, default:1.0) –Probability of rotate-pasting the instance-class points.
-
pos_key(str, default:'pos') –Key of the coordinates used to compute azimuth sectors and to rotate pasted points.
-
segment_key(str, default:'segment') –Key of per-point semantic labels used to select the instance classes.
-
p(float, default:1.0) –Probability of applying the mix; below it the first scene is returned unchanged.
-
seed(Optional[int], default:None) –Seed for the sector, rotation and probability draws;
Nonedraws from the global generator (seeRandomizable).
Shape
- each key in
keys: \((N, \ldots)\) and \((M, \ldots)\) inputs, \((K, \ldots)\) output.
Example
BuildOctree(
    *,
    pos_key: str,
    dst_octree_key: str,
    depth: int,
    full_depth: int = 2,
    batch_size: int = 1,
    normal_key: str | None = None,
    feature_key: str | None = None,
    label_key: str | None = None,
    batch_key: str | None = None,
    dst_points_key: str | None = None,
)
Bases: DictTransform
Build an octree from positions stored in a dictionary.
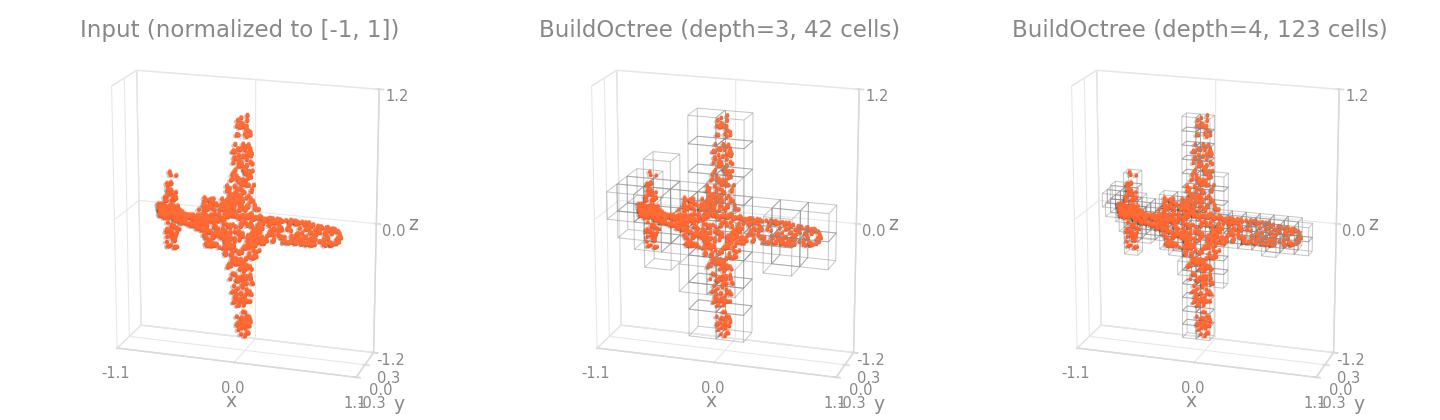
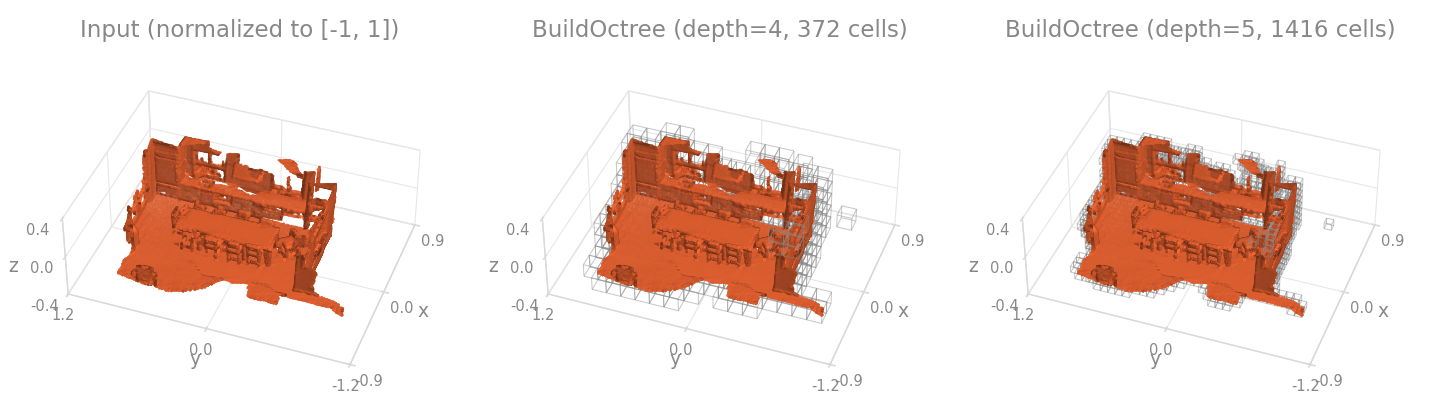
Parameters:
-
pos_key(str) –Key holding the point positions.
-
dst_octree_key(str) –Key under which the octree is stored.
-
depth(int) –Octree depth.
-
full_depth(int, default:2) –Full depth of the octree.
-
batch_size(int, default:1) –Batch size.
-
normal_key(str | None, default:None) –Key holding surface normals.
-
feature_key(str | None, default:None) –Key holding point features.
-
label_key(str | None, default:None) –Key holding per-point labels.
-
batch_key(str | None, default:None) –Key holding batch indices.
-
dst_points_key(str | None, default:None) –Key under which the octree points are stored.
OctreeFeatures(
    keys: KeyCollection,
    features_type: str,
    nempty: bool = False,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Extract per-node features from an octree via octree.get_input_feature.
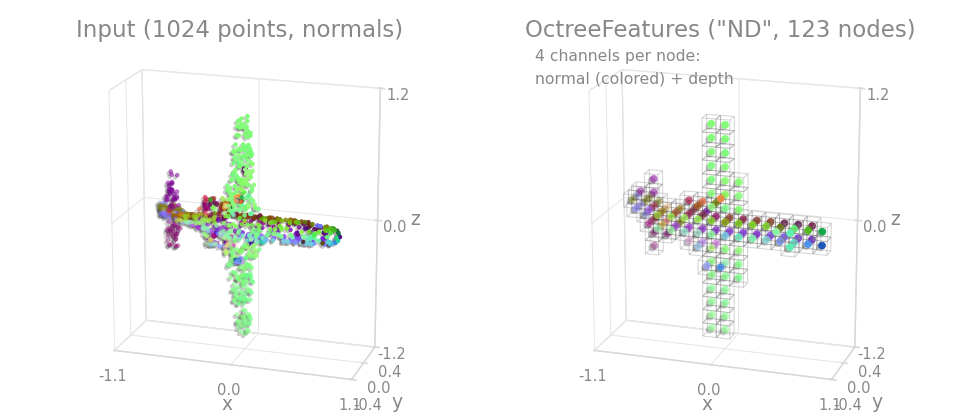
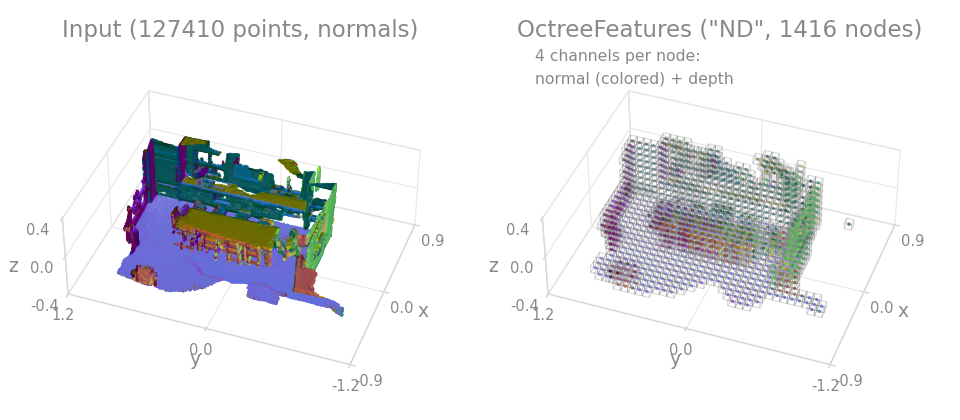
Parameters:
-
keys(KeyCollection) –Keys holding
Octreeinstances to extract features from. -
features_type(str) –Feature spec passed to
octree.get_input_feature(e.g."ND"for normals + depth,"NDFP"for normals + depth + features + position). -
nempty(bool, default:False) –If
True, return features only for non-empty nodes; otherwise include empty-node padding. -
dst_keys(Optional[KeyCollection], default:None) –Where to store the extracted feature tensors. Defaults to
keys. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
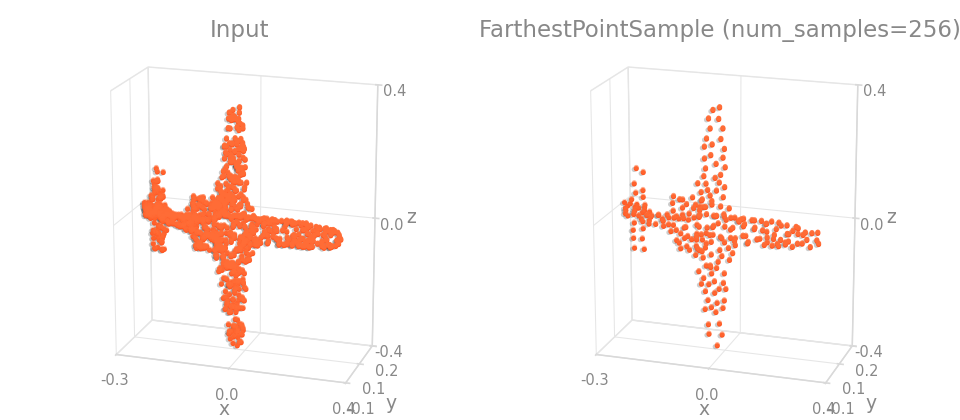
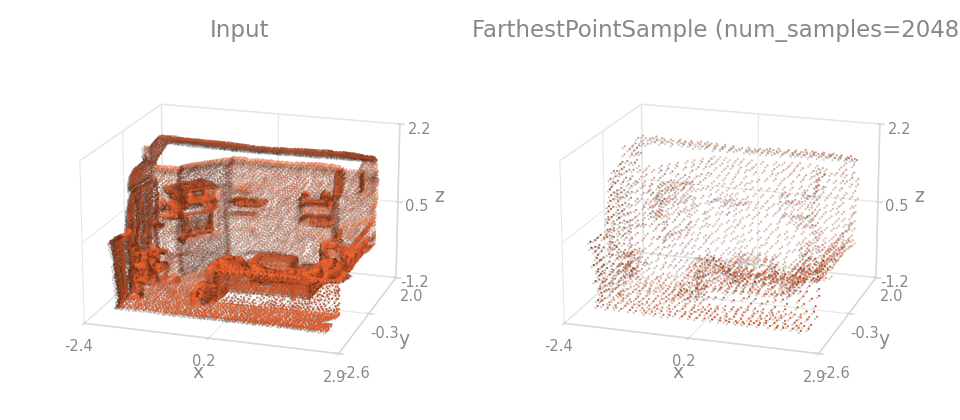
FarthestPointSample(
    pos_key: str,
    keys: Optional[KeyCollection] = None,
    num_samples: Optional[int] = None,
    ratio: Optional[float] = None,
    random_start: bool = False,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Farthest-point sampling (FPS) of a dictionary entry.
Iteratively picks the point that maximizes the minimum distance to the already-selected set, producing a well-distributed subset. Matches the FPS convention used by PointNet++, PointNeXt, KPConv, and others.
See Also
torch_pointcloud.transforms.functional.farthest_point_sample
Note
The underlying fps does not accept a torch.Generator. To make random_start=True reproducible, seed PyTorch globally via torch.manual_seed(...) before applying this transform.
Parameters:
-
pos_key(str) –The key holding the positions used for FPS.
-
keys(Optional[KeyCollection], default:None) –Extra keys to subsample with the same indices.
-
num_samples(Optional[int], default:None) –The number of points to sample.
-
ratio(Optional[float], default:None) –The ratio of points to sample.
-
random_start(bool, default:False) –Whether to start the sampling from a random point.
-
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
RandomBlockCrop(
    pos_key: str,
    keys: Optional[KeyCollection] = None,
    block_size: float = 1.0,
    min_nodes: int = 1024,
    max_tries: int = 100,
    axes: Sequence[int] = (0, 1),
    dst_center_key: Optional[str] = None,
    seed: Optional[int] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Keep the points of a random vertical block: a square window of the ground plane, full height.
A random point centers a block_size x block_size window over axes (the ground plane); the window is redrawn until it holds more than min_nodes points, up to max_tries draws, after which the largest draw is kept. The center is written under dst_center_key so SubtractItems(axes=...) can center the block on it.
Parameters:
-
pos_key(str) –Key holding the positions, \((N, D)\).
-
keys(Optional[KeyCollection], default:None) –Extra per-point keys to crop with the same mask.
-
block_size(float, default:1.0) –Side of the window, in the units of the positions.
-
min_nodes(int, default:1024) –A draw is accepted once the window holds more than this many points.
-
max_tries(int, default:100) –Number of draws before the largest window is kept.
-
axes(Sequence[int], default:(0, 1)) –Axes of the window (the other axes are unbounded).
-
dst_center_key(Optional[str], default:None) –Key receiving the window center, the drawn point \((D,)\);
Nonedoes not store it. -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) does not record it. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Example
import torch
from torch_pointcloud.transforms import RandomBlockCrop
crop = RandomBlockCrop(pos_key="pos", keys="segment", block_size=1.0, min_nodes=10, seed=0)
data = {"pos": torch.rand(500, 3) * 4, "segment": torch.zeros(500, dtype=torch.long)}
out = crop(data)
bool((out["pos"].max(0).values - out["pos"].min(0).values)[:2].max() <= 1.0)  # True
RandomDropout(
    keys: KeyCollection,
    drop_ratio_range: Tuple[float, float] = (0.1, 0.1),
    p: float = 1.0,
    seed: Optional[int] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
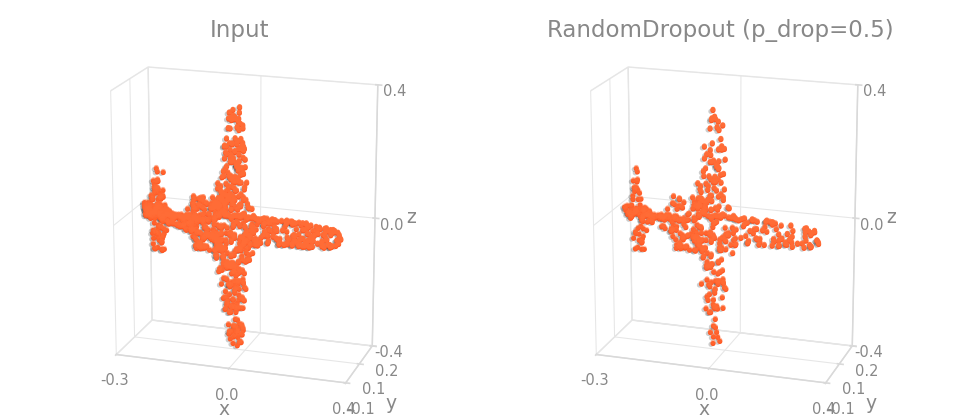
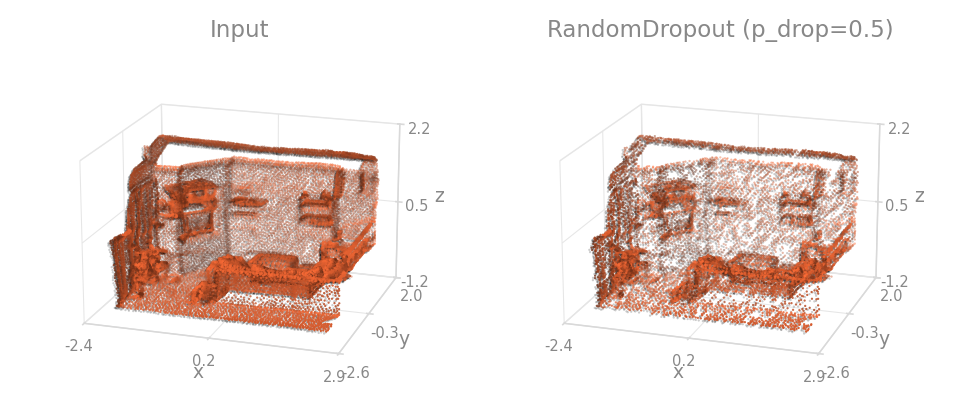
Randomly drop a fraction of points across all listed keys.
The same boolean keep-mask is applied to every key so per-point correspondence is preserved. Sampling is once per call, with a drop ratio drawn uniformly from drop_ratio_range.
See Also
torch_pointcloud.transforms.functional.random_dropout_mask
Parameters:
-
keys(KeyCollection) –Keys to subset. All must share the same leading dimension \(N\).
-
drop_ratio_range(Tuple[float, float], default:(0.1, 0.1)) –Min and max fraction of points to drop;
(r, r)drops a fixed fraction. Must lie in \([0, 1)\). -
p(float, default:1.0) –Probability of applying the transform.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
RandomSample(
    keys: KeyCollection,
    num_samples: int,
    replace: bool = False,
    seed: Optional[int] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
    allow_fewer: bool = False,
)
Bases: DictTransform, Randomizable
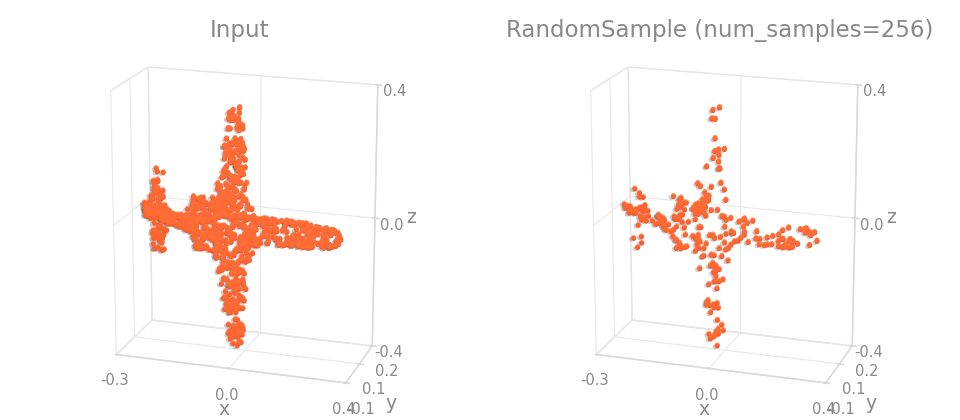
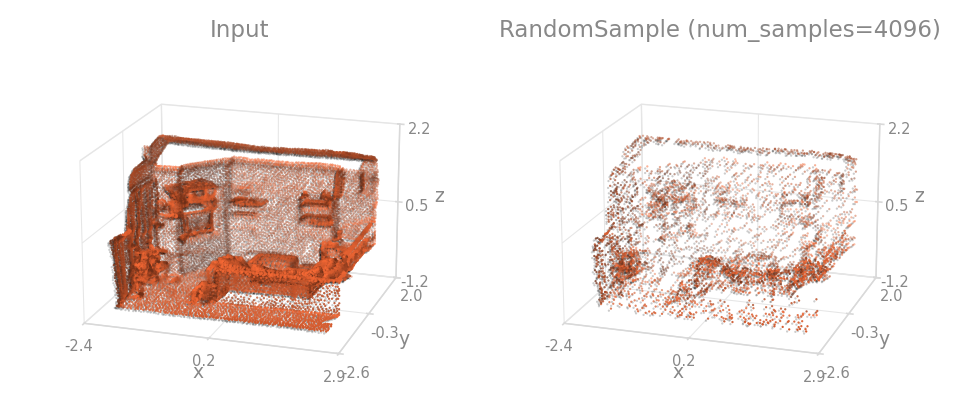
Randomly sample a fixed number of points from dict entries.
If multiple keys are provided, the same indices are used for all keys, ensuring correspondence between the sampled values.
See Also
torch_pointcloud.transforms.functional.random_sample
Parameters:
-
keys(KeyCollection) –The keys to sample from.
-
num_samples(int) –The number of values to sample.
-
replace(bool, default:False) –If
True, sample with replacement (duplicates allowed). IfFalse(default), sample without replacement when the first sampled key has at leastnum_samplespoints; whennum_samplesexceeds that count the draw falls back to replacement so the output always hasnum_samplesrows. -
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data. -
allow_fewer(bool, default:False) –If
True, a cloud with at mostnum_samplespoints passes through unchanged instead of being completed by draws with replacement.
Raises:
-
ValueError–If the first sampled tensor is empty and
num_samples > 0.
RandomSampleFaceVertices(
    *,
    keys: KeyCollection,
    face_key: KeyCollection,
    dst_normal_key: Optional[KeyCollection] = "normal",
    num_samples: int,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
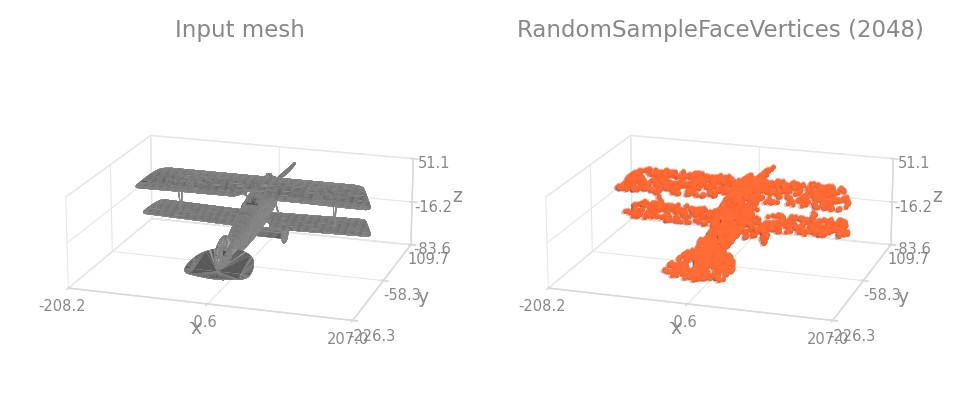
Randomly sample a fixed number of vertices from a 3D mesh stored in a dictionary.
See Also
torch_pointcloud.transforms.functional.random_sample_face_vertices
Parameters:
-
keys(KeyCollection) –The keys holding vertex positions.
-
face_key(KeyCollection) –The keys holding the face indices.
-
dst_normal_key(Optional[KeyCollection], default:'normal') –The key to store the computed normals in.
-
num_samples(int) –The number of vertices to sample.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
ShufflePoint(
    keys: KeyCollection,
    p: float = 1.0,
    seed: Optional[int] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
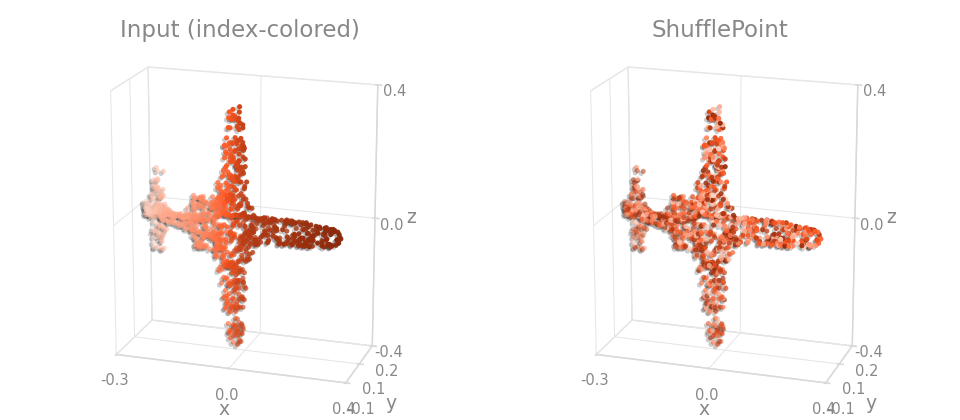
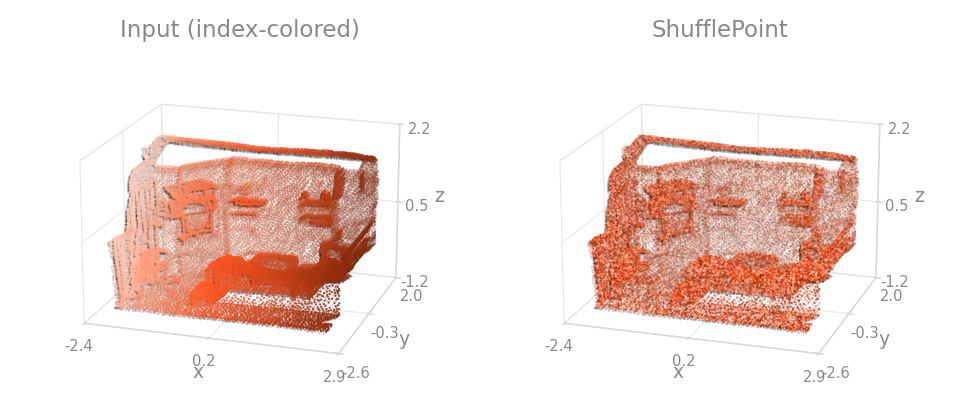
Randomly permute the order of points across listed keys.
The same permutation is applied to every key so per-point correspondence is preserved. Useful before RandomSample when you want to break any structural ordering in the input.
See Also
torch_pointcloud.transforms.functional.shuffle_indices
Parameters:
-
keys(KeyCollection) –Keys to permute. All must share the same leading dimension \(N\).
-
p(float, default:1.0) –Probability of applying the transform.
-
seed(Optional[int], default:None) –Seed of the transform's own random stream;
Nonedraws from the global generator (seeRandomizable). -
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Slice(
    keys: KeyCollection,
    start: Optional[int] = None,
    stop: Optional[int] = None,
    step: Optional[int] = None,
    dim: int = 0,
    dst_keys: Optional[KeyCollection] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
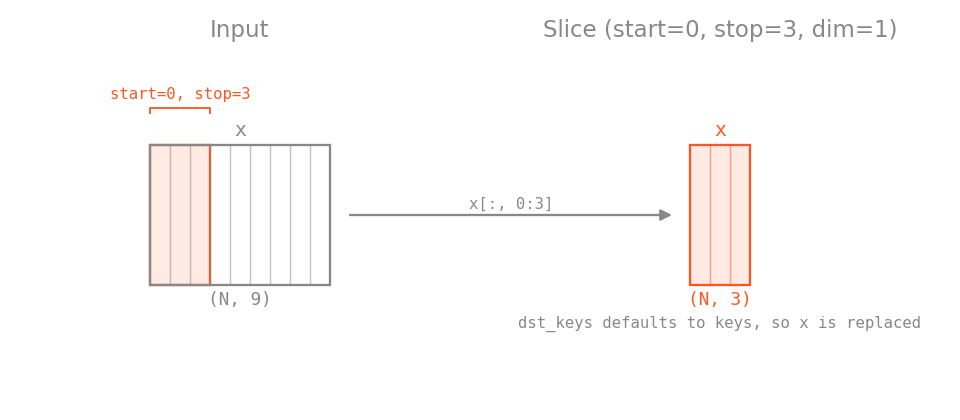
Slice each listed tensor along a chosen dimension via standard Python slicing.
Useful for taking the first \(N\) rows (e.g. on FPS-sorted point clouds), or extracting a single column of pos into a separate key (set dim=1 with start=axis, stop=axis+1).
Parameters:
-
keys(KeyCollection) –Keys to slice.
-
start(Optional[int], default:None) –Start index (inclusive).
Noneis equivalent to0. -
stop(Optional[int], default:None) –Stop index (exclusive).
Nonemeans "to the end". -
step(Optional[int], default:None) –Stride between selected positions.
Noneis equivalent to1. -
dim(int, default:0) –Dimension along which to slice. Defaults to
0(the row axis). -
dst_keys(Optional[KeyCollection], default:None) –Where to store results. Defaults to
keys. -
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys), written only when
dim == 0;None(the default) disables it. Leave it unset whendst_keysdiffer fromkeys, since the map would describe thedst_keysrows. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Example
SphereCrop(
    pos_key: str,
    radius: float,
    max_nodes: Optional[int] = None,
    keys: Optional[KeyCollection] = None,
    center: Any = "centroid",
    p: float = 1.0,
    seed: Optional[int] = None,
    dst_index_key: Optional[str] = None,
    allow_missing_keys: bool = False,
    max_ratio: Optional[float] = None,
    dst_center_key: Optional[str] = None,
)
Bases: DictTransform, Randomizable
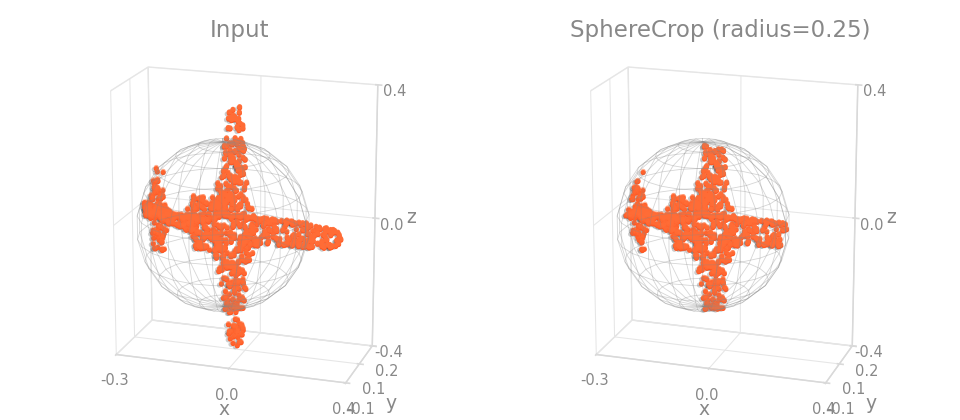
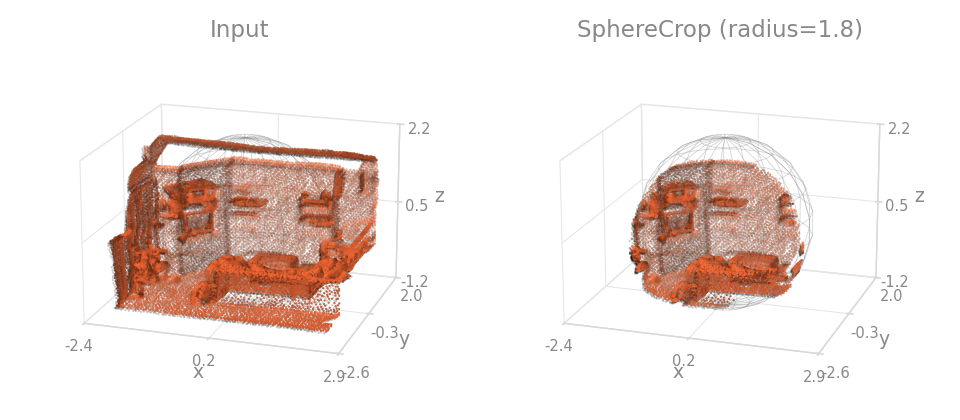
Keep only points inside an L2 sphere of given radius.
The mask is computed from pos_key and applied to every listed keys. Equivalent to Compose([SphereMask(...), ApplyMask(...)]), kept as a convenience preset (the dual of RemoveNearOrigin).
When max_nodes is set and the sphere holds more than max_nodes points, only the max_nodes nearest the center are kept, bounding memory on large scenes.
Parameters:
-
pos_key(str) –Key with positions used to compute the mask.
-
keys(Optional[KeyCollection], default:None) –Extra keys to filter with the same mask.
-
center(Any, default:'centroid') –Center of the sphere. If
"centroid", uses the per-cloud centroid; if"random_point", picks a random point as the center; otherwise treat as a 3-vector. -
radius(float) –Radius of the sphere (Euclidean).
-
max_nodes(Optional[int], default:None) –Optional cap on the number of kept points. If
None(default), no cap is applied; otherwise themax_nodespoints nearest the center are kept. -
max_ratio(Optional[float], default:None) –Optional cap as a fraction of the input point count (keeps that fraction of the points nearest the center); combined with
max_nodesby the minimum. -
dst_center_key(Optional[str], default:None) –Key receiving the center \((D,)\) the crop was taken around;
Nonedoes not store it. -
p(float, default:1.0) –Probability of applying the transform.
-
seed(Optional[int], default:None) –Seed for the random center (
center="random_point") and the probability draw;Nonedraws from the global generator (seeRandomizable). -
dst_index_key(Optional[str], default:None) –Key for the output-to-input row map (see the module docs on sampling keys);
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Bases: DictTransform
Scale dictionary tensor entries by their largest absolute value, per channel: \(x' = x / \max(\max_i |x_i|, \epsilon)\).
The statistic comes from the sample itself, so the result lies in \([-1, 1]\) whatever the input range (e.g. a LiDAR return number divided by the highest return number of the scene).
Parameters:
-
keys(KeyCollection) –The keys to scale.
-
eps(float, default:1e-07) –Lower bound on the divisor to prevent division by zero. Defaults to \(10^{-7}\).
-
allow_missing_keys(bool, default:False) –If
True, missing keys are silently ignored.
Normalize(
    keys: KeyCollection,
    mean: Sequence[float],
    std: Sequence[float],
    eps: float = 1e-07,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Normalize dictionary tensor entries: \(x' = (x - \mu) / \max(\sigma, \epsilon)\).
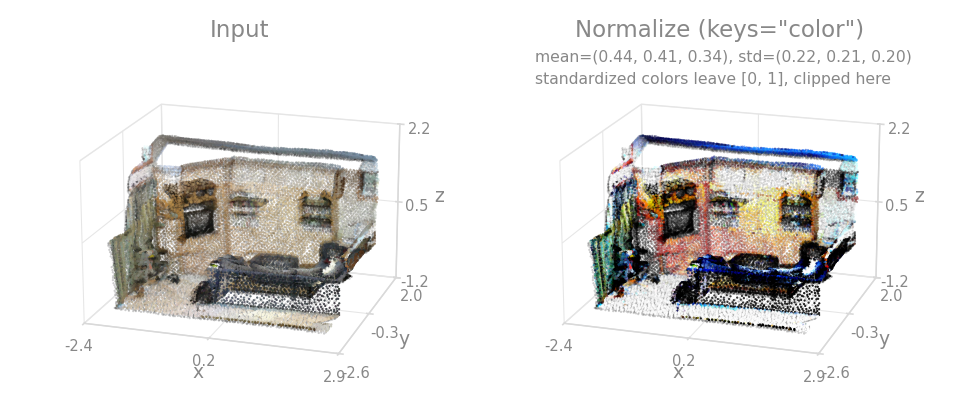
Parameters:
-
keys(KeyCollection) –The keys to standardize.
-
mean(Sequence[float]) –Per-channel mean(s). Broadcast against the last dimension of each tensor.
-
std(Sequence[float]) –Per-channel standard deviation(s).
-
eps(float, default:1e-07) –Lower bound on \(\sigma\) to prevent division by zero. Defaults to \(10^{-7}\).
-
allow_missing_keys(bool, default:False) –If
True, missing keys are silently ignored.
Rescale(
    keys: KeyCollection,
    eps: float = 1e-06,
    method: RescaleMethod = "centroid",
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Center a point set and rescale it to a unit extent.
Bundles a centering step and a divide-by-extent step that depend on the same statistics. Four methods, each pairing a center and a denominator:
method | Center on | Divide by |
|---|---|---|
"centroid" | centroid (mean) | max Euclidean distance to center |
"bbox" | bbox midpoint | half of the longest axis extent |
"centroid_extent" | centroid (mean) | longest axis extent |
"min_sphere" | min-sphere center | min-sphere radius |
Empty inputs (N=0) are returned unchanged.
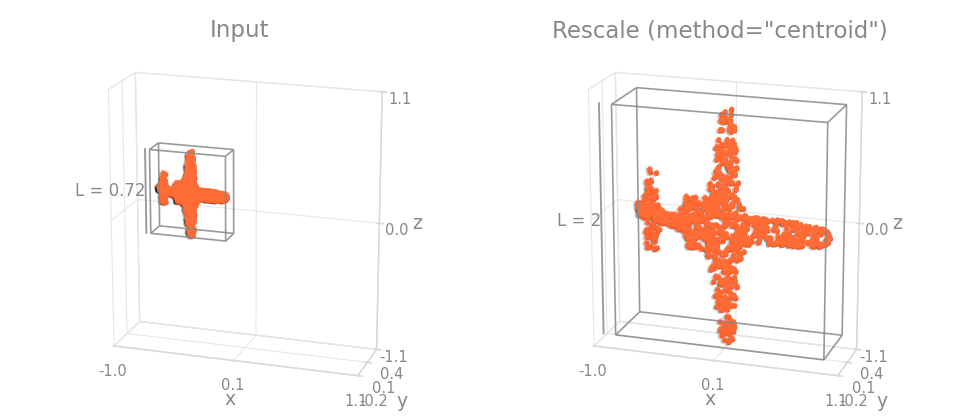
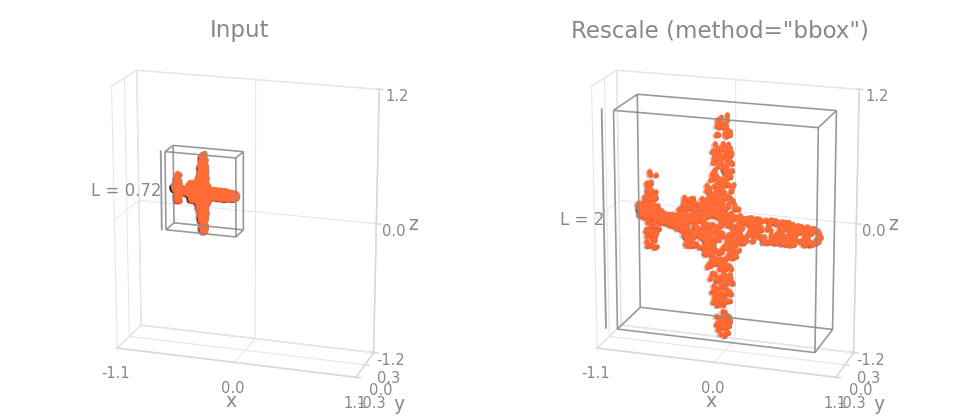
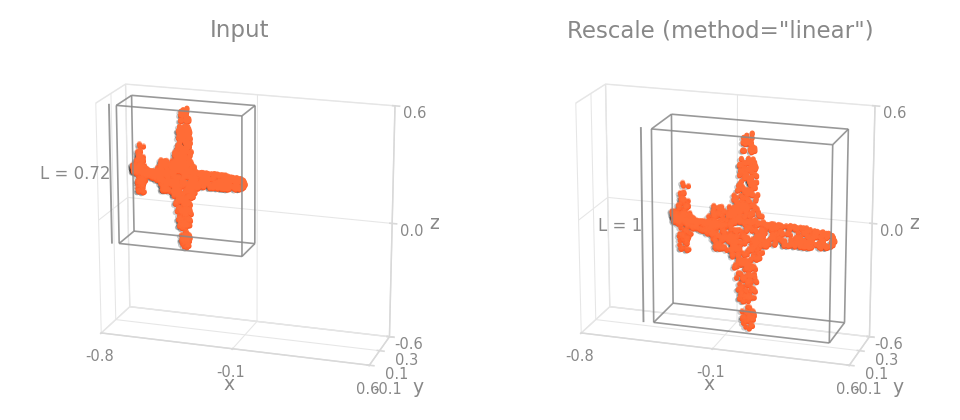
See Also
torch_pointcloud.transforms.functional.rescale
Parameters:
-
keys(KeyCollection) –The keys to rescale.
-
eps(float, default:1e-06) –Small constant added to the denominator for numerical stability.
-
method(RescaleMethod, default:'centroid') –"centroid","bbox","centroid_extent", or"min_sphere". -
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
Bases: DictTransform
Make dictionary tensor entries absolute.
See Also
torch_pointcloud.transforms.functional.absolute
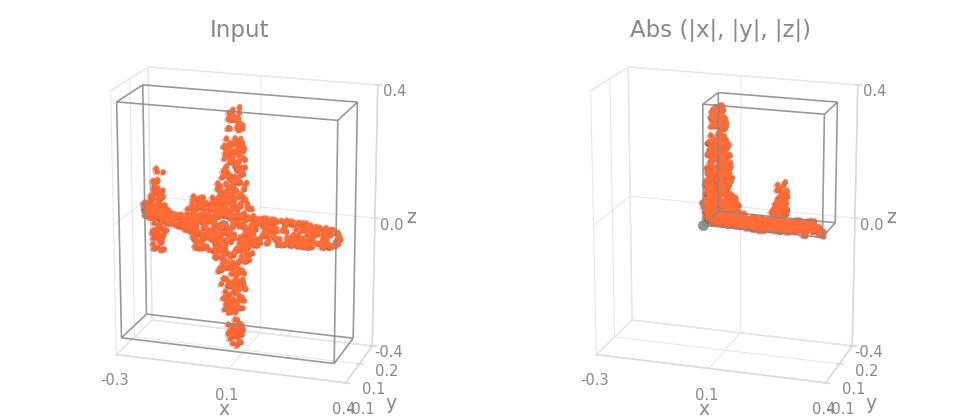
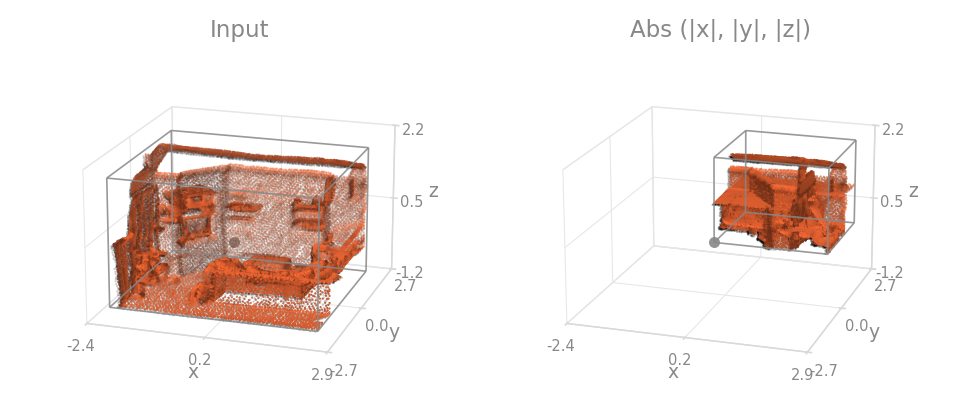
Parameters:
-
keys(KeyCollection) –The keys to make absolute.
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
Bases: DictTransform
Concatenates tensors from multiple keys into a single feature tensor.
Note
This transform is mostly used to concatenate multiple features into a single tensor to feed into your model.
Integer inputs are cast to float32; floating inputs keep their dtype. When the inputs mix floating dtypes, the result uses the widest one (so float64 is preserved, never downcast).
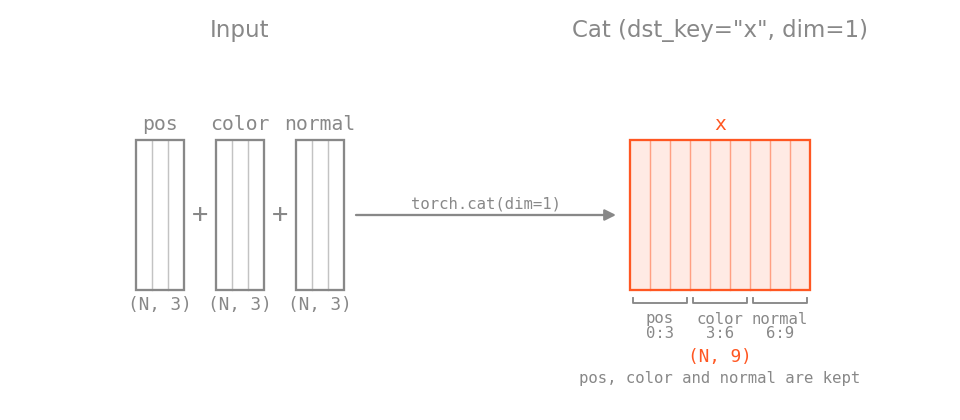
Parameters:
-
keys(KeyCollection) –Keys whose tensors are concatenated (in order).
-
dst_key(str) –Key under which the result is stored.
-
dim(int, default:-1) –Dimension along which to concatenate.
-
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Example
If you have a point cloud data containing position, color and normal and want to concatenate them into a single feature tensor (to feed into your model), you can do the following:
import torch

from torch_pointcloud.transforms import Cat

data = {
    "pos": torch.randn(10, 3),
    "color": torch.randn(10, 3),
    "normal": torch.randn(10, 3),
}
transform = Cat(keys=["pos", "color", "normal"], dst_key="x", dim=1)
data = transform(data)
Now, the data dictionary will contain the key x with the shape \((10, 9)\).
Clamp(
    keys: KeyCollection,
    min: Union[float, Sequence[float], None] = None,
    max: Union[float, Sequence[float], None] = None,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Clamp tensor entries to a range (a thin wrapper over torch.clamp).
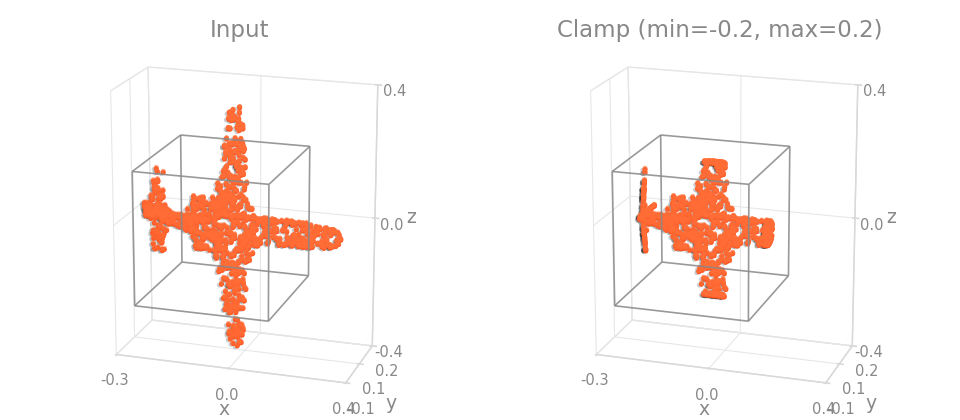
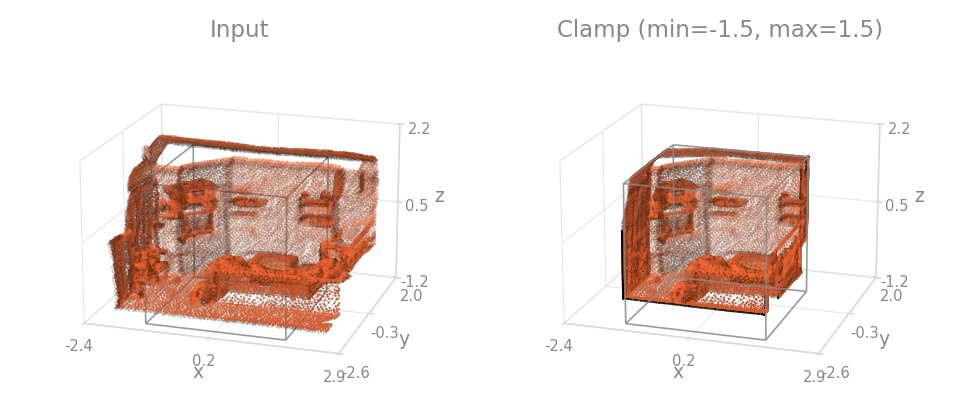
Parameters:
-
keys(KeyCollection) –Keys to clamp.
-
min(Union[float, Sequence[float], None], default:None) –Lower bound, one value or one per channel of the last dim.
Nonedisables the lower clamp. -
max(Union[float, Sequence[float], None], default:None) –Upper bound, one value or one per channel of the last dim.
Nonedisables the upper clamp. -
dst_keys(Optional[KeyCollection], default:None) –Where to store the result. Defaults to
keys(in-place overwrite). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Bases: DictTransform
Copy values from source keys to new destination keys.
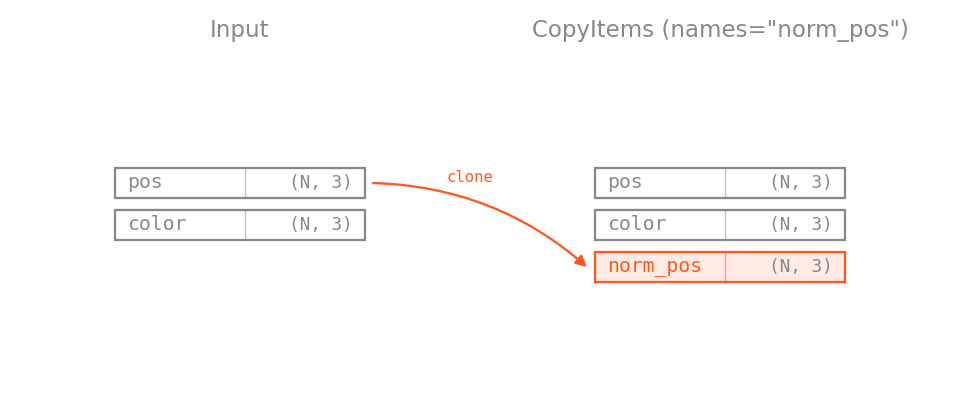
Parameters:
-
keys(KeyCollection) –Source keys to copy from.
-
dst_keys(KeyCollection) –Destination keys to copy to (same length as
keys). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent source keys.
Bases: DictTransform
Divide dictionary tensor entries by a divisor.
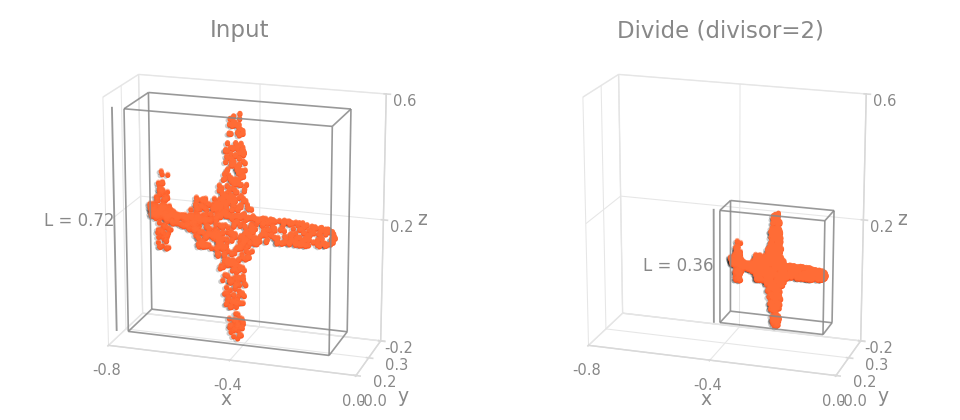
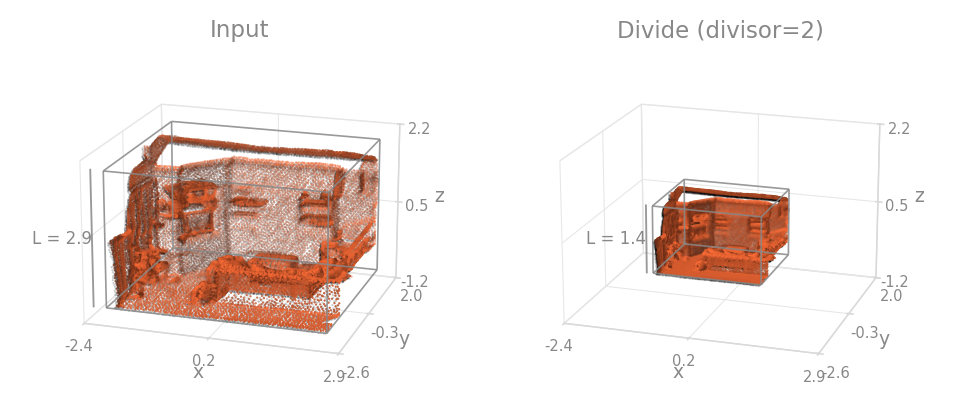
Parameters:
-
keys(KeyCollection) –The keys to divide.
-
divisor(float | Sequence[float]) –The divisor(s).
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
DivideItems(
    keys: KeyCollection,
    div_keys: KeyCollection,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Divide target keys by the value of a reference key element-wise.
Computes data[key] = data[key] / data[div_key] for each key.
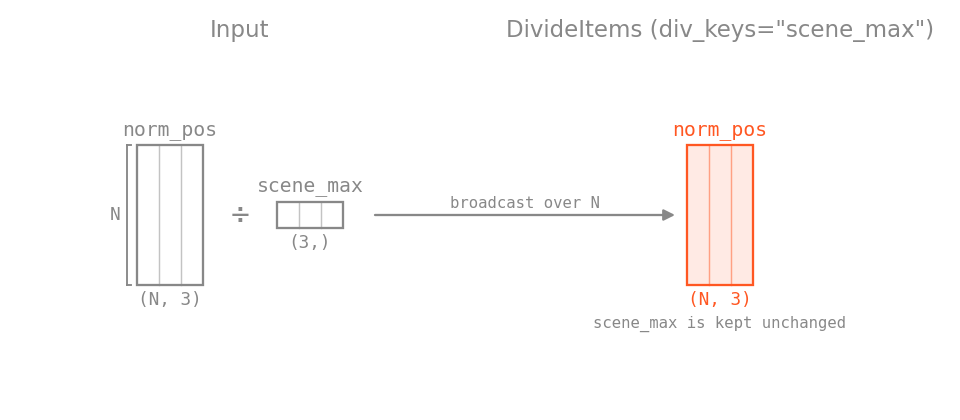
Parameters:
-
keys(KeyCollection) –Keys whose tensors are divided.
-
div_keys(KeyCollection) –Keys whose values are used as the divisors.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store results. Defaults to
keys. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent target keys.
Bases: DictTransform
Keep only items in the data dictionary that are in the keys list.
Note
This transform is useful if during augmentation process you constructed multiple tensors and want to drop intermediate tensors for memory efficiency.
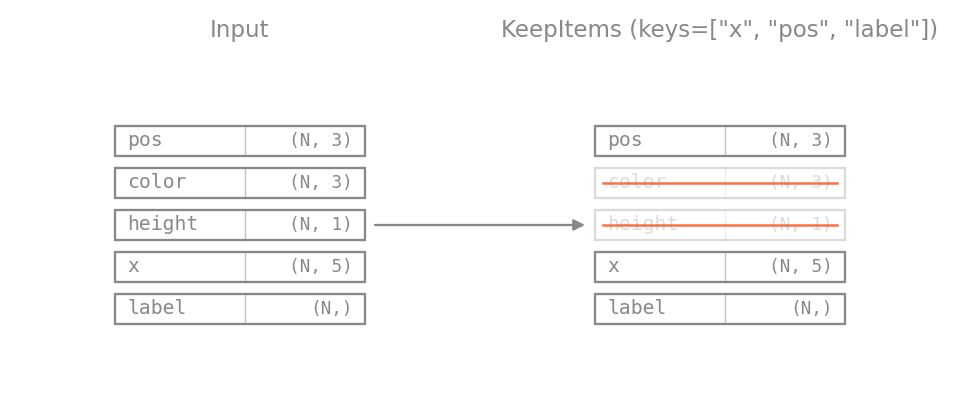
Parameters:
-
keys(KeyCollection) –The keys to keep in the data dictionary.
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
Example
If you have a data dictionary containing position, color and normal and want to keep only the position and color, you can do the following:
import torch

from torch_pointcloud.transforms import KeepItems

data = {
    "pos": torch.randn(10, 3),
    "color": torch.randn(10, 3),
    "normal": torch.randn(10, 3),
}
transform = KeepItems(keys=["pos", "color"])
data = transform(data)
Now, the data dictionary will contain only the keys pos and color. The key normal will be removed.
OneHot(
    keys: KeyCollection,
    num_classes: ValueCollection[int],
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
One-hot encode integer-class tensors.
Wraps torch.nn.functional.one_hot and casts the result to float so the output is ready to feed into a model.
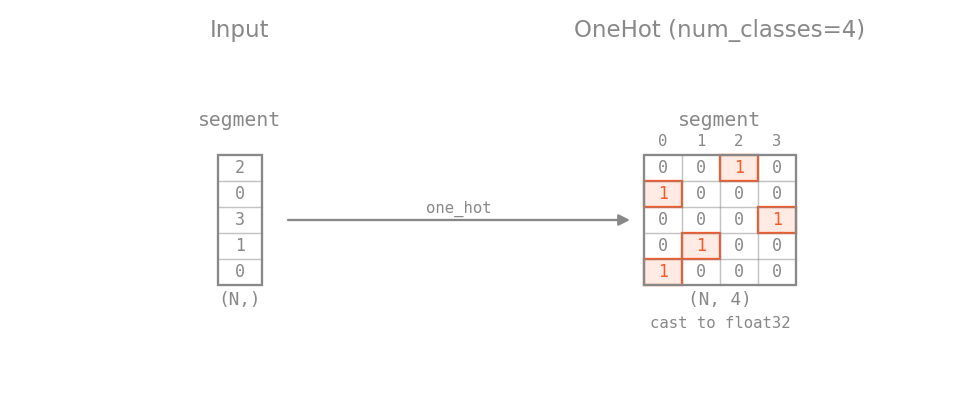
Parameters:
-
keys(KeyCollection) –Keys holding integer (long) class indices.
-
num_classes(ValueCollection[int]) –Number of classes \(C\) in the one-hot encoding.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store the one-hot tensors. Defaults to
keys. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Shape
Input class tensor of shape \((N,)\) becomes \((N, C)\). A scalar input becomes shape \((C,)\), which after batched collate stacks to \((B, C)\).
OnesLike(
    keys: KeyCollection,
    memory_format: ValueCollection[memory_format]
    | None = None,
    dtype: ValueCollection[dtype] | None = None,
    layout: ValueCollection[layout] | None = None,
    device: ValueCollection[device] | None = None,
    pin_memory: ValueCollection[bool] | None = False,
    requires_grad: ValueCollection[bool] | None = False,
    dst_keys: KeyCollection | None = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Adds a tensor of ones shaped like existing dictionary entries.
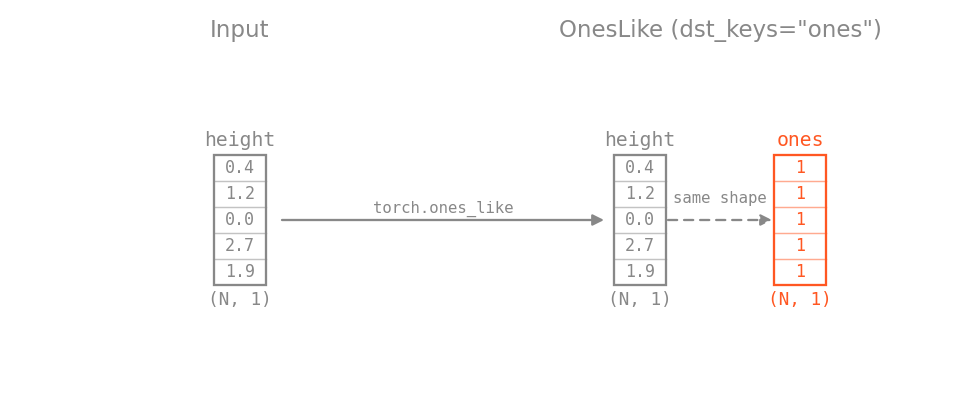
Parameters:
-
keys(KeyCollection) –Reference keys used to determine tensor shape.
-
dst_keys(KeyCollection | None, default:None) –Keys under which the ones tensors are stored.
Reduce(
    keys: KeyCollection,
    op: ValueCollection[ReduceOp],
    dim: ValueCollection[int] = 0,
    keepdim: bool = False,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Reduce a tensor along a dimension and store the scalar/vector result.
Useful for capturing per-sample statistics (e.g. axis-wise scene maxima or centroids) as standalone keys that downstream transforms can reference.
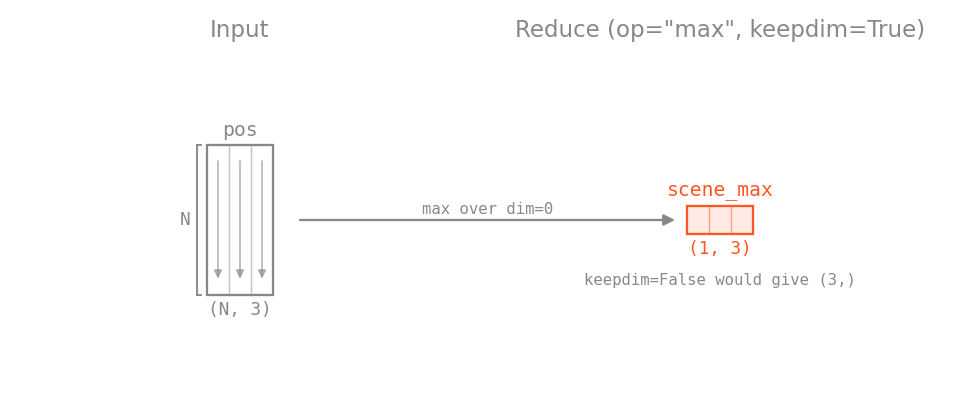
Parameters:
-
keys(KeyCollection) –Keys to reduce.
-
op(ValueCollection[ReduceOp]) –Reduction operator:
"min","max","mean", or"sum"(matches the vocabulary used byVoxelize)."mean"keeps the input's floating dtype (float64included); integer inputs are cast tofloat32. -
dim(ValueCollection[int], default:0) –Dimension to reduce. Defaults to
0. -
keepdim(bool, default:False) –Pass
keepdim=Trueto keep the reduced axis as size \(1\). This is helpful when the result is meant to broadcast against a \((N, D)\) tensor (e.g. per-sample bbox stats) and to survive the packed-batch collate - a \((1, D)\) tensor collates to \((B, D)\) viatorch.cat, whereas a \((D,)\) tensor would concatenate to \((B \cdot D,)\). -
dst_keys(Optional[KeyCollection], default:None) –Output keys. Defaults to
keys(in-place overwrite). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent keys.
Relabel(
    keys: KeyCollection,
    labels: Sequence[int] | Dict[int, int],
    default: int = 0,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Remap integer labels in dictionary entries via a lookup table.
labels can be either:
- a sequence of source values (1:1) - each value at index
iis mapped toi; - a
dict[int, int](general source → target) - supports N-to-1 merges (e.g. SemanticKITTI'smoving-carandcarboth → 0).
Source values not listed in labels are set to default.
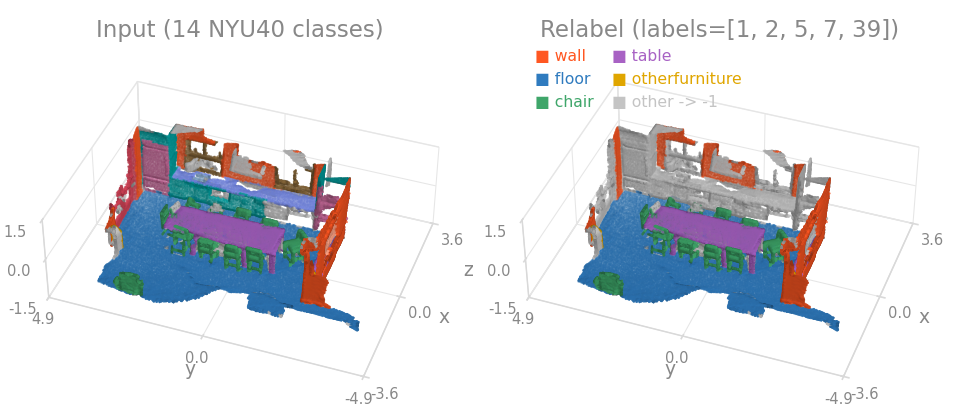
Parameters:
-
keys(KeyCollection) –Keys holding label tensors to remap.
-
labels(Sequence[int] | Dict[int, int]) –Source-value listing (1:1) or explicit
{source: target}dict (N:1). -
default(int, default:0) –Value assigned to source values not listed in
labels. -
allow_missing_keys(bool, default:False) –If
True, skip missing keys instead of raising.
Example
import torch
import torch_pointcloud.transforms as T

# 1:1 - keep raw NYU40 ids 1, 2, 3, 4, 5 and remap them to 0..4
relabel = T.Relabel(keys="segment", labels=[1, 2, 3, 4, 5], default=255)
relabel({"segment": torch.tensor([1, 3, 5, 7])})["segment"]  # tensor([0, 2, 4, 255])

# N:1 - SemanticKITTI 19-class benchmark (merges moving-* into static)
relabel = T.Relabel(
    keys="segment",
    labels={
        10: 0, 252: 0,    # car        (+ moving-car)
        11: 1,             # bicycle
        15: 2,             # motorcycle
        18: 3, 258: 3,    # truck      (+ moving-truck)
        # ...
    },
    default=255,
)
relabel({"segment": torch.tensor([10, 252, 11, 99])})["segment"]  # tensor([0, 0, 1, 255])
Bases: DictTransform
Rename keys in the dictionary.
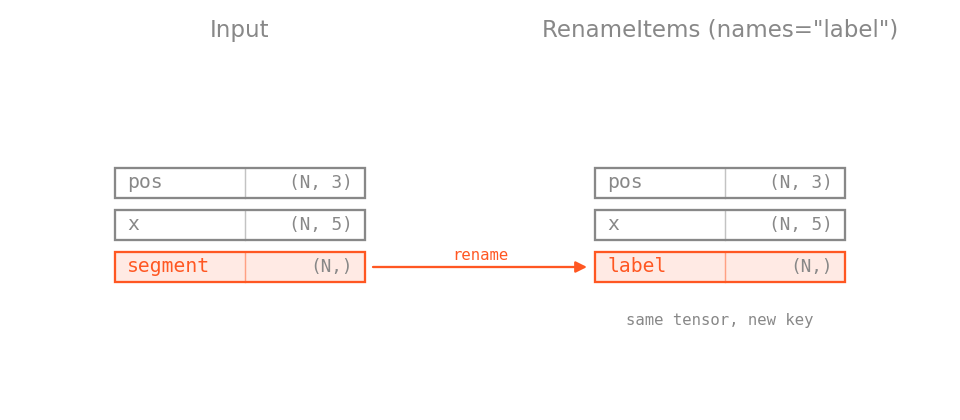
Parameters:
-
keys(KeyCollection) –Source keys to rename.
-
dst_keys(KeyCollection) –New key names (same length as
keys). -
allow_missing_keys(bool, default:False) –If
True, silently skip absent source keys.
Bases: DictTransform
Multiply dictionary tensor entries by a scale factor.
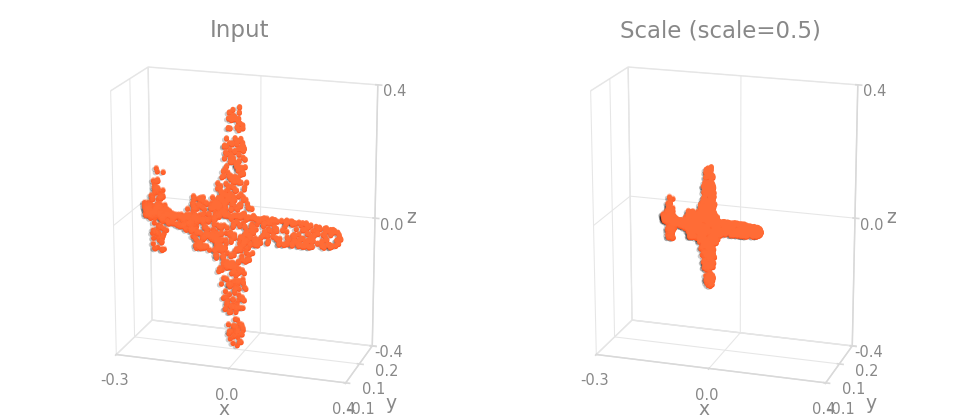
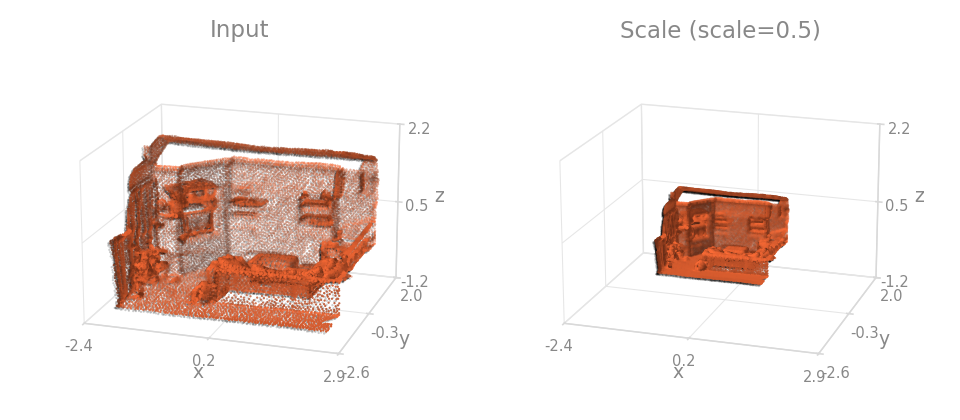
Parameters:
-
keys(KeyCollection) –The keys to scale.
-
scale(float | Sequence[float]) –The scale factor(s).
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
Bases: DictTransform
Set values for keys in the dictionary, creating or overwriting them.
Unlike most DictTransform subclasses, SetValue does not read existing values, so allow_missing_keys has no meaning and is not accepted.
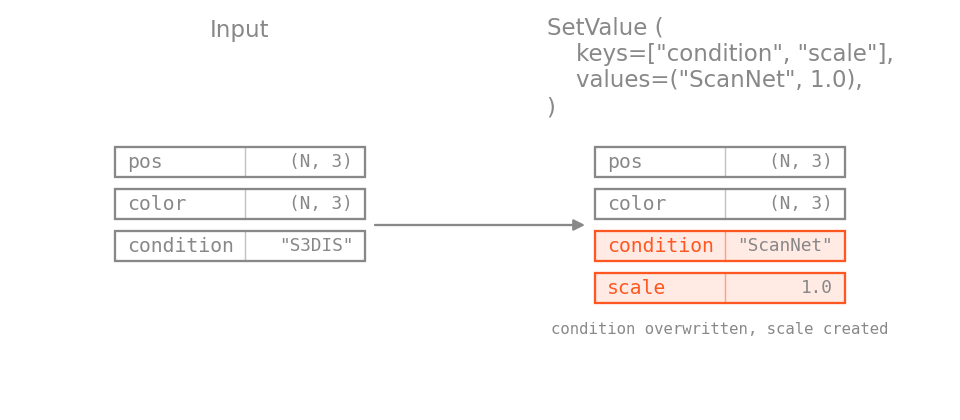
Parameters:
-
keys(KeyCollection) –The keys to set.
-
values(Any) –The values to set. Either a single value broadcast to every key, or a sequence of values the same length as
keys.
SubtractItems(
    keys: KeyCollection,
    sub_keys: KeyCollection,
    dst_keys: Optional[KeyCollection] = None,
    axes: Optional[Sequence[int]] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Subtract the value of a reference key from target keys element-wise.
Computes data[key] = data[key] - data[sub_key] for each key. With axes set, only the listed last-dim indices are subtracted; the other components pass through unchanged (useful to shift only XY while keeping Z absolute).
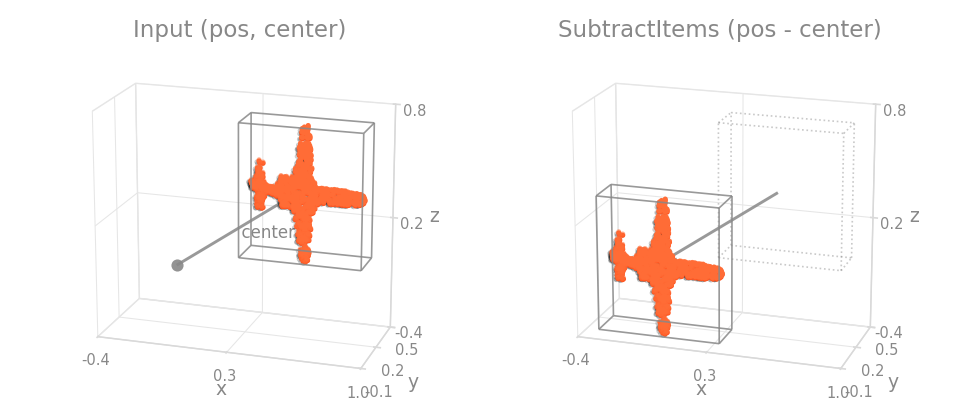
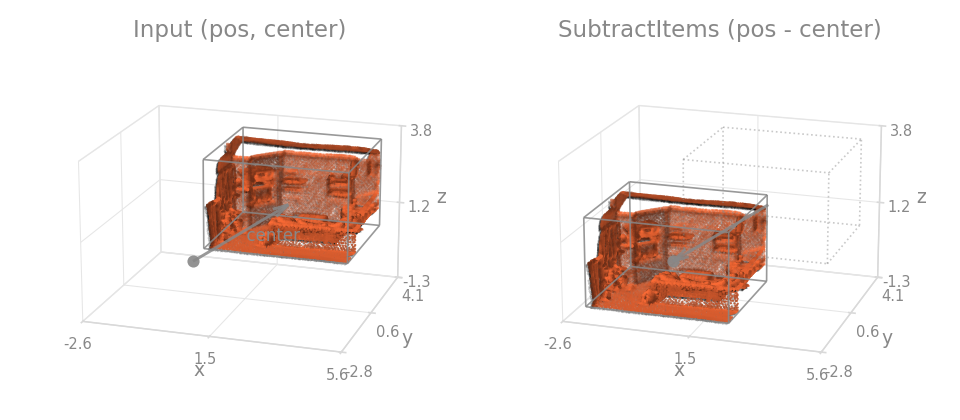
Parameters:
-
keys(KeyCollection) –Keys whose tensors are modified (subtracted from).
-
sub_keys(KeyCollection) –Keys whose values are subtracted from each target key.
-
dst_keys(Optional[KeyCollection], default:None) –Where to store results. Defaults to
keys. -
axes(Optional[Sequence[int]], default:None) –Optional indices into the last dim restricting which components are subtracted.
None(default) subtracts every component. -
allow_missing_keys(bool, default:False) –If
True, silently skip absent target keys.
ToDevice(
    keys: KeyCollection,
    device: ValueCollection[str | device],
    non_blocking: ValueCollection[bool] = False,
    copy: ValueCollection[bool] = True,
    memory_format: ValueCollection[
        memory_format | None
    ] = None,
    dst_keys: Optional[KeyCollection] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Convert dictionary tensor entries to the given device.
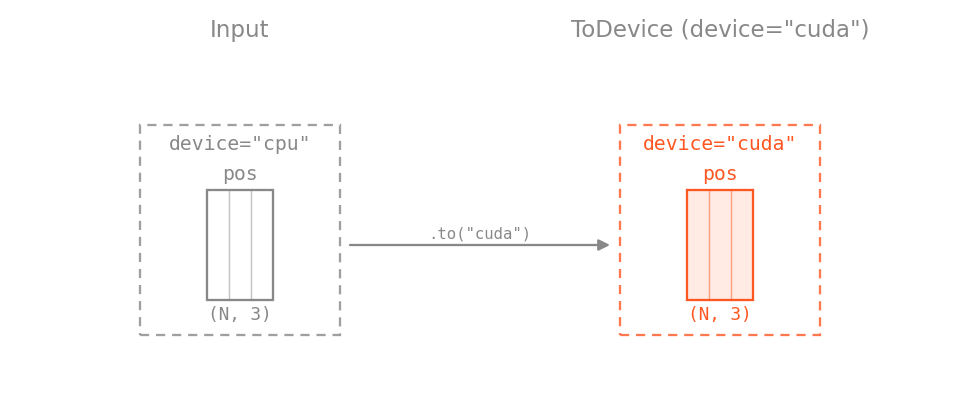
Parameters:
-
keys(KeyCollection) –The keys to convert the tensors to the given device.
-
device(ValueCollection[str | device]) –The device to convert the tensors to.
-
non_blocking(ValueCollection[bool], default:False) –If
True, the transfer will be done asynchronously. -
copy(ValueCollection[bool], default:True) –If
True, the tensor will be copied to the new device. -
memory_format(ValueCollection[memory_format | None], default:None) –The memory format to use for the tensor.
-
dst_keys(Optional[KeyCollection], default:None) –The keys to store the converted tensors in.
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
Bases: DictTransform
Cast dictionary tensor entries to float32.
Useful when tensors are stored in integer formats (e.g. uint8 for colors) and need to be promoted to floating point before arithmetic transforms like Divide or Normalize.
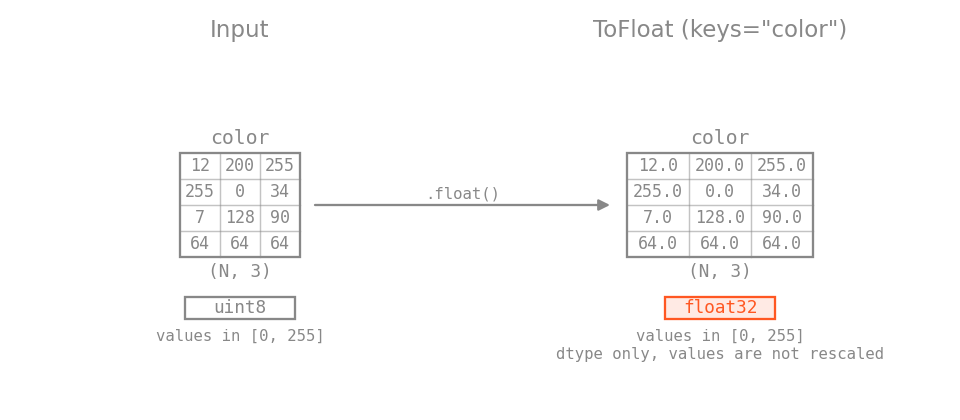
Parameters:
-
keys(KeyCollection) –The keys to cast.
-
allow_missing_keys(bool, default:False) –If
True, missing keys are silently ignored.
ToTensor(
    keys: KeyCollection,
    dtype: ValueCollection[str | dtype] | None = None,
    device: ValueCollection[str | device] | None = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Convert dictionary entries to tensors.
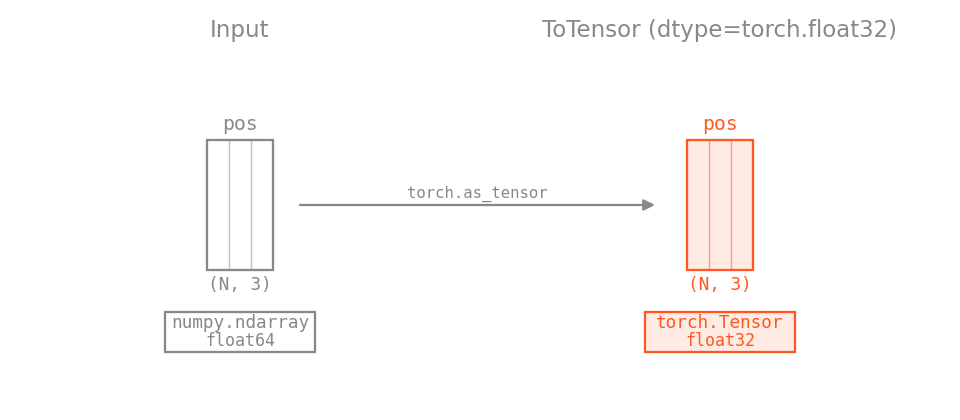
Parameters:
-
keys(KeyCollection) –The keys to convert.
-
dtype(ValueCollection[str | dtype] | None, default:None) –Target dtype(s).
-
device(ValueCollection[str | device] | None, default:None) –Target device(s).
-
allow_missing_keys(bool, default:False) –If
True, the transform will not raise an error if the keys are not present in the data.
DivisiblePad(
    num_samples: int,
    pad_fill: PadFill = "cycle",
    ref_key: str = POS,
    batch_key: str = BATCH,
    seed: Optional[int] = None,
    dst_inverse_key: Optional[str] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Pad per-point tensors so each batch is divisible by num_samples.
Thin dict wrapper around divisible_pad; see its docstring for the full behavior of each pad_fill strategy ("cycle", "replicate", "random"). The tensor at ref_key defines the packed count \(n\) and the device. If a batch index tensor lives at batch_key, padding is done per-batch; otherwise a single zero batch is synthesized. Every tensor in the dict whose first dim equals \(n\) (positions, features, labels, ...) is re-indexed by the same gather map, so per-point correspondence is preserved.
When dst_inverse_key is set, the transform also records a source-to-padded index map under that dict key: a 1-D long tensor of length \(n\) with values in \([0, n_\text{padded})\) giving the canonical padded row for each source row. If the key already holds a prior inverse map (from an earlier invertible transform), the new map composes with it via gather, so the stored tensor always maps from the outermost source space to the current predictor space. Consumers such as SlidingWindowInferer read this key once and gather predictions back to the source rows.
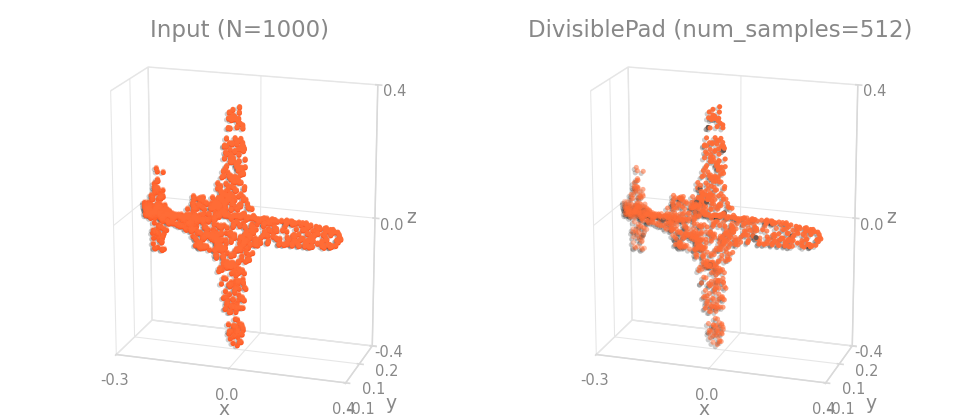
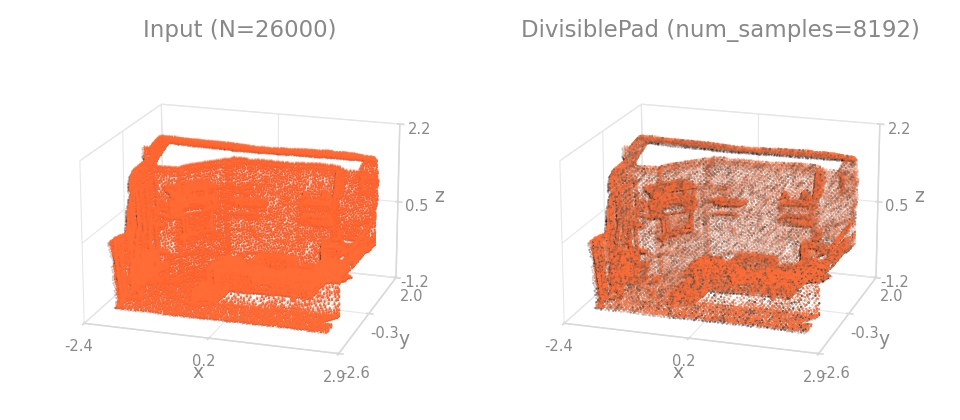
Parameters:
-
num_samples(int) –Target chunk size \(k\) for divisibility.
-
pad_fill(PadFill, default:'cycle') –Fill strategy passed through to
divisible_pad. -
ref_key(str, default:POS) –Key whose tensor defines \(n\) and the device.
-
batch_key(str, default:BATCH) –Key for an optional batch index tensor. When present in the data, padding runs per-batch; otherwise a single zero batch is synthesized for the whole scene.
-
seed(Optional[int], default:None) –Seed for the random padding (only used when
pad_fill="random");Nonedraws from the global generator (seeRandomizable). -
dst_inverse_key(Optional[str], default:None) –Key for the source-to-padded row map (see the module docs on sampling keys); composes with any prior value at the same key.
None(the default) disables it. -
allow_missing_keys(bool, default:False) –If
True, return the data unchanged whenref_keyis missing instead of raising.
Example
HardVoxelize(
    pos_key: str,
    voxel_size: Sequence[float],
    point_cloud_range: Sequence[float],
    max_num_points: int,
    max_num_voxels: int,
    feature_key: Optional[str] = None,
    dst_voxel_key: str = VOXEL,
    dst_pos_voxel_key: str = POS_VOXEL,
    dst_num_points_key: str = VOXEL_NUM_POINTS,
    allow_missing_keys: bool = False,
)
Bases: DictTransform
Hard-voxelize a single scene into the per-voxel point stack consumed by voxel detectors.
Moves the transform_points_to_voxels step of voxel detectors (PointPillars, SECOND) out of the model and into the data pipeline, mirroring how BuildOctree produces an octree for OctFormer. The model then receives already-voxelized input and focuses on the network math.
Reads pos_key (and optionally feature_key), runs hard_voxelize on the single sample (the batch index is all zeros), and adds three keys while keeping pos / x:
dst_voxel_key: the per-voxel point stack.dst_pos_voxel_key: integer voxel grid indices \((z, y, x)\) (the single-sample batch column is dropped; the per-voxel scene index is synthesized at collation).dst_num_points_key: the per-voxel point counts.
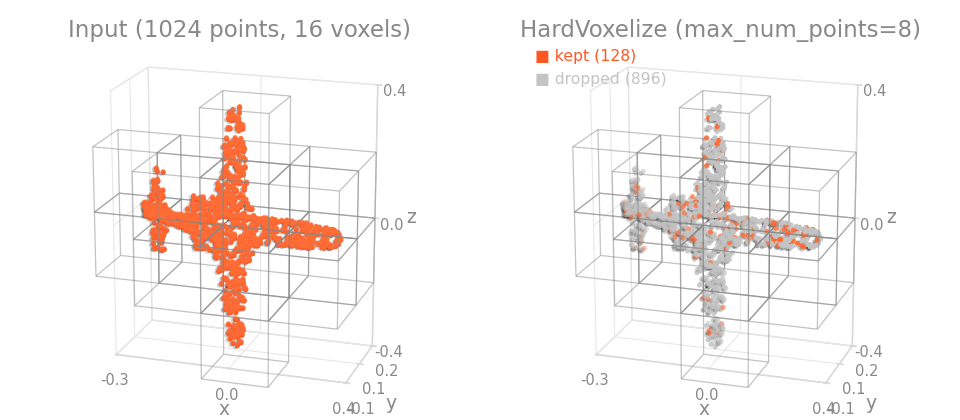
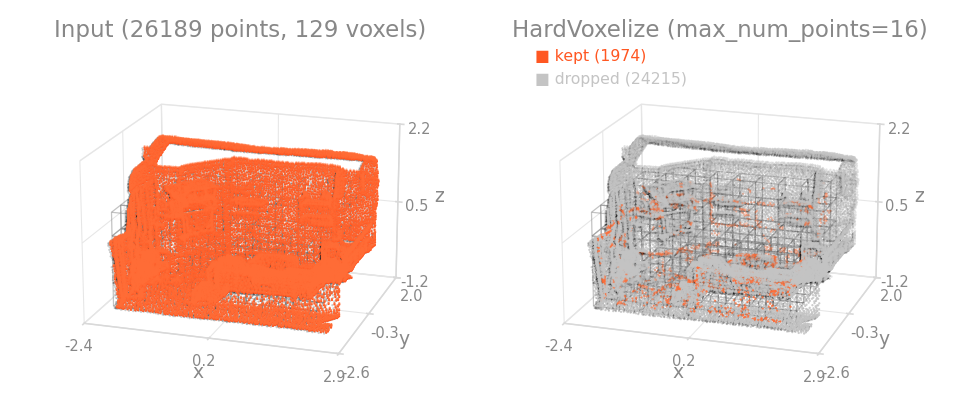
Parameters:
-
pos_key(str) –Key holding the point positions \((N, 3)\).
-
voxel_size(Sequence[float]) –Voxel size \((v_x, v_y, v_z)\).
-
point_cloud_range(Sequence[float]) –Range \((x_\min, y_\min, z_\min, x_\max, y_\max, z_\max)\).
-
max_num_points(int) –Maximum number of points kept per voxel.
-
max_num_voxels(int) –Maximum number of voxels kept per scene.
-
feature_key(Optional[str], default:None) –Optional key holding extra point features \((N, C)\) concatenated after \(xyz\).
-
dst_voxel_key(str, default:VOXEL) –Output key for the per-voxel point stack.
-
dst_pos_voxel_key(str, default:POS_VOXEL) –Output key for the integer voxel grid indices.
-
dst_num_points_key(str, default:VOXEL_NUM_POINTS) –Output key for the per-voxel point counts.
-
allow_missing_keys(bool, default:False) –Unused (
pos_keyis always required); kept for interface parity.
Shape
dst_voxel_key: \((V, \text{max\_num\_points}, 3 + C)\).dst_pos_voxel_key: \((V, 3)\) with columns \((z, y, x)\).dst_num_points_key: \((V,)\).
Example
import torch
import torch_pointcloud.transforms as T

data = {"pos": torch.rand(1000, 3) * 50.0, "x": torch.rand(1000, 1)}
transform = T.HardVoxelize(
    pos_key="pos",
    feature_key="x",
    voxel_size=(0.16, 0.16, 4.0),
    point_cloud_range=(0.0, -39.68, -3.0, 69.12, 39.68, 1.0),
    max_num_points=32,
    max_num_voxels=40000,
)
data = transform(data)
print(data["voxel"].shape, data["pos_voxel"].shape, data["voxel_num_points"].shape)
Voxelize(
    pos_key: str,
    pos_reduce: VoxelPosReduce,
    size: float,
    method: VoxelMethod = "grid",
    reduce: Optional[ValueCollection[VoxelReduce]] = None,
    keys: Optional[KeyCollection] = None,
    dst_inverse_key: Optional[str] = None,
    dst_pos_grid_key: Optional[str] = None,
    random_first: bool = False,
    seed: Optional[int] = None,
    allow_missing_keys: bool = False,
)
Bases: DictTransform, Randomizable
Voxelize a point cloud by grid-binning and per-voxel reduction.
Sub-samples a point cloud to one representative point per occupied voxel, and optionally records a source-to-voxel index map for full-resolution back-projection.
Operates on a single sample (pre-collate). With dst_inverse_key set, the stored tensor has shape \((N_\text{full},)\) with values in \([0, N_\text{voxel})\): for each original point \(i\), the voxel it belongs to. Downstream code can recover full-resolution predictions with preds_full = preds_voxel[inverse].
If the key already holds a prior inverse map (e.g. from an earlier invertible transform), the new map composes with it via gather, so the stored tensor always maps from the outermost source space to the current predictor space.
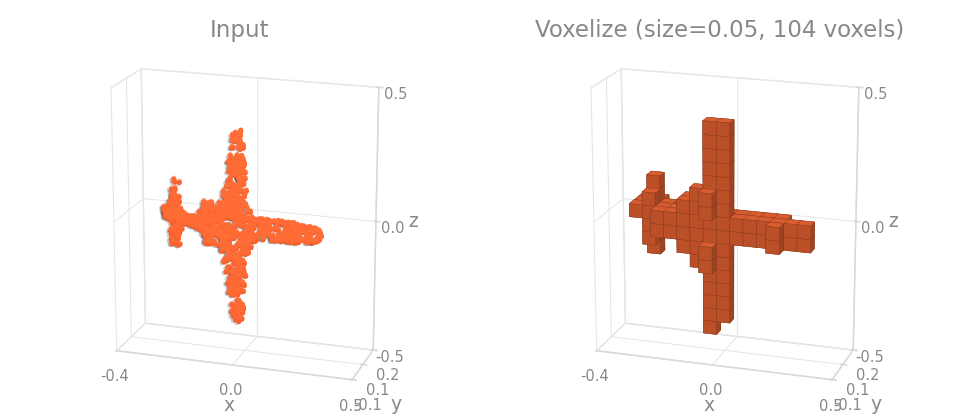
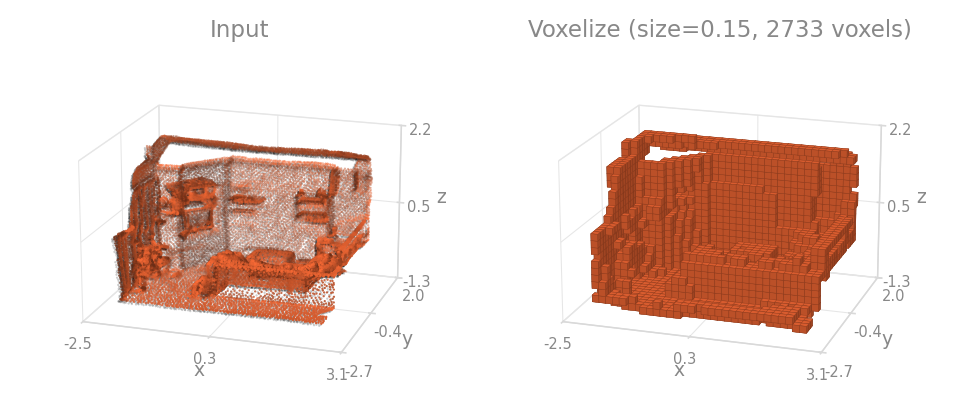
Parameters:
-
pos_key(str) –Key holding the positions to sub-sample.
-
pos_reduce(VoxelPosReduce) –How to reduce positions per voxel (
mean/min/max/sum/first/grid). -
size(float) –Voxel edge length in the same units as the positions. Must be positive.
-
method(VoxelMethod, default:'grid') –How voxel ids are computed, which fixes the output voxel order:
grid(the default) uses the linear grid index,fnvan FNV-1a hash of the grid coordinates, as hash-based reference pipelines do. -
reduce(Optional[ValueCollection[VoxelReduce]], default:None) –Per-key reduction for
keys.None(the default) resolves per key tomeanfor floating-point tensors andfirstfor integer tensors (e.g.segment). Integer keys keep their dtype: non-firstreductions compute in float and cast back. Thefirstrepresentative is the first point of each voxel in input order, deterministic across devices (unlessrandom_first=True). -
keys(Optional[KeyCollection], default:None) –Additional per-point keys to sub-sample (e.g.
color,segment). -
dst_inverse_key(Optional[str], default:None) –Key for the source-to-voxel row map (see the module docs on sampling keys); composes with any prior value at the same key.
None(the default) disables it. -
dst_pos_grid_key(Optional[str], default:None) –When set, also store the integer voxel-grid coordinates under this key. Useful when a model needs both real-valued positions (e.g. for rotary position embedding) and integer grid coordinates (for serialization / sparse-conv stems); with
pos_reduce="grid"it holds the same grid aspos_key. -
random_first(bool, default:False) –If
True, the per-voxel representative used byreduce="first"(and thepos/grid_posderivations) is chosen randomly within each voxel on every call. Per-voxel random sampling is a meaningful training augmentation; leaveFalse(default) for deterministic validation. -
seed(Optional[int], default:None) –Seed for the random voxel representative (
random_first);Nonedraws from the global generator (seeRandomizable). -
allow_missing_keys(bool, default:False) –If
True, return the data unchanged whenpos_keyis missing and skip absentkeys.
Raises:
-
ValueError–If
sizeis not positive, orpos_reduce/method/ anyreduceentry is not one of its allowed values.