voxelnext
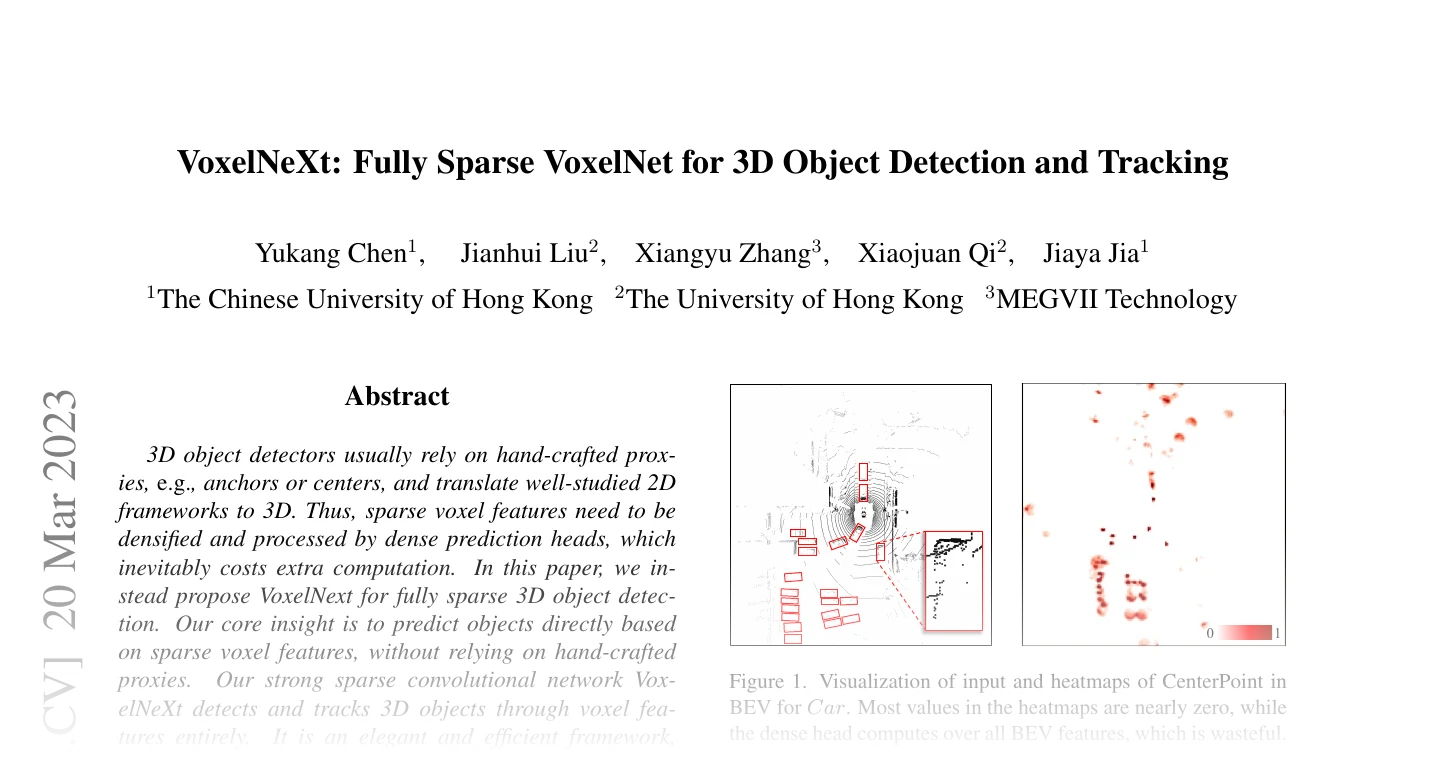
VoxelNeXt detection model.
Classes:
-
VoxelNeXtHeadOutput–Raw per-voxel predictions of the fully sparse VoxelNeXt head.
-
VoxelResBackbone8xVoxelNeXt–Fully sparse residual voxel backbone (
VoxelResBackBone8xVoxelNeXt), \(8\times\) BEV stride. -
VoxelNeXtSeparateHead–Per-group sparse regression head (
SeparateHead). -
VoxelNeXtHead–Fully sparse multi-group detection head (
VoxelNeXtHead). -
VoxelNeXtDetection–VoxelNeXt fully sparse 3D object detector (packed point format).
Bases: TypedDict
Raw per-voxel predictions of the fully sparse VoxelNeXt head.
Each entry is a list with one tensor per class group. voxel_indices are the sparse positions \((\text{batch}, y, x)\) of the BEV feature map that every prediction row is anchored to.
Attributes:
-
hm(List[Tensor]) –Per-group classification logits, each of shape \((V, n_g)\) for \(n_g\) classes in the group.
-
center(List[Tensor]) –Per-group BEV center offset, each \((V, 2)\).
-
center_z(List[Tensor]) –Per-group absolute box height, each \((V, 1)\).
-
dim(List[Tensor]) –Per-group log box size, each \((V, 3)\).
-
rot(List[Tensor]) –Per-group \((\cos\theta, \sin\theta)\), each \((V, 2)\).
-
vel(List[Tensor]) –Per-group BEV velocity, each \((V, 2)\).
-
voxel_indices(Tensor) –Sparse BEV indices \((V, 3)\) with columns \((\text{batch}, y, x)\).
VoxelResBackbone8xVoxelNeXt(
    in_channels: int,
    *,
    channels: Sequence[int] = (16, 32, 64, 128, 128),
    out_channels: int = 128,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Fully sparse residual voxel backbone (VoxelResBackBone8xVoxelNeXt), \(8\times\) BEV stride.
Extends the SECOND residual backbone with two extra downsampling stages (conv5, conv6) whose outputs are folded back onto the stage-4 sparse tensor (their indices rescaled by \(2\) and \(4\)), so the receptive field grows without densifying. The merged 3D sparse tensor is then collapsed along height into a 2D BEV sparse tensor (bev_out), refined by a 2D conv_out + shared_conv, and returned as a 2D spconv.SparseConvTensor for the fully sparse head (no dense BEV map).
Parameters:
-
in_channels(int) –Input voxel feature channels (\(5\) for nuScenes \(x, y, z, \text{intensity}, \Delta t\)).
-
channels(Sequence[int], default:(16, 32, 64, 128, 128)) –Per-stage channel widths \((c_1, \ldots, c_5)\) for
conv1-conv6. -
out_channels(int, default:128) –Output channels of the 2D
conv_out/shared_conv. -
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
bev_out–Collapses the height axis by summing the features of every voxel sharing the same BEV cell.
VoxelNeXtSeparateHead(
    in_channels: int,
    head_dict: Dict[str, Dict[str, int]],
    *,
    head_kernel_size: int,
    use_bias: bool,
    init_bias: float = -2.19,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Per-group sparse regression head (SeparateHead).
One small sparse 2D conv stack per box attribute (hm, center, ...). Every attribute has num_conv \(- 1\) hidden SubMConv2d blocks (kernel head_kernel_size) followed by a \(1\times1\) SubMConv2d projecting to the attribute's output channels. Runs directly on the BEV sparse tensor and returns per-voxel feature tensors (no dense map).
Parameters:
-
in_channels(int) –Shared-conv feature channels feeding every attribute stack.
-
head_dict(Dict[str, Dict[str, int]]) –Mapping attribute name ->
{"out_channels": int, "num_conv": int}. -
head_kernel_size(int) –Kernel size of the hidden
SubMConv2dblocks. -
use_bias(bool) –Whether the hidden conv carries a bias (
USE_BIAS_BEFORE_NORM). -
init_bias(float, default:-2.19) –Bias initialization of the heatmap output conv.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
reset_parameters–Start the heatmap logits at
init_bias, the regression convs at Kaiming-normal weights and zero biases.
VoxelNeXtHead(
    in_channels: int,
    class_groups: Sequence[Sequence[int]],
    *,
    head_dict: Dict[str, Dict[str, int]],
    head_kernel_size: int,
    num_hm_conv: int,
    use_bias: bool,
    feature_map_stride: int,
    voxel_size: Sequence[float],
    point_cloud_range: Sequence[float],
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Fully sparse multi-group detection head (VoxelNeXtHead).
A stack of VoxelNeXtSeparateHeads, one per class group, predicting CenterPoint-style attributes directly on the BEV sparse voxels. decode performs per-group top-\(K\) voxel selection, recovers oriented boxes from the sparse indices, then per-group 3D NMS.
Parameters:
-
in_channels(int) –Shared-conv feature channels feeding each separate head.
-
class_groups(Sequence[Sequence[int]]) –Class-index groups (0-based), one per separate head.
-
head_dict(Dict[str, Dict[str, int]]) –Per-attribute config shared by every group (
hmis appended per group). -
head_kernel_size(int) –Kernel size of the hidden head convs.
-
num_hm_conv(int) –Number of convs in the classification (
hm) stack. -
use_bias(bool) –Whether hidden head convs carry a bias.
-
feature_map_stride(int) –BEV stride relating sparse indices to metric coordinates.
-
voxel_size(Sequence[float]) –Voxel size \((v_x, v_y, v_z)\).
-
point_cloud_range(Sequence[float]) –Range \((x_\min, y_\min, z_\min, x_\max, y_\max, z_\max)\).
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
decode–Decode raw sparse head outputs into raw candidate detections (no score threshold or NMS).
decode(
    out: VoxelNeXtHeadOutput,
    *,
    batch_size: int,
    top_k: int = 500,
) -> Detection3D
Decode raw sparse head outputs into raw candidate detections (no score threshold or NMS).
Selects the top-\(K\) scoring voxels per group and scene and recovers an oriented box, score and label per candidate, along with the predicted BEV velocity \((v_x, v_y)\) under velocity. The full candidate set is returned; the evaluation pipeline applies score thresholding and per-class 3D NMS via the torch_pointcloud.ops.box3d utilities (see the benchmark example).
Parameters:
-
out(VoxelNeXtHeadOutput) –A
VoxelNeXtHeadOutputfromforward. -
batch_size(int) –Number of scenes \(B\) in the batch.
-
top_k(int, default:500) –Per-group, per-scene voxel cap.
Returns:
-
Detection3D–Packed candidate detections
{"boxes": (K, 7), "scores": (K,), "labels": (K,), "batch": (K,)} -
Detection3D–(PyG layout), plus
"velocity"\((K, 2)\).
VoxelNeXtDetection(
    in_channels: int = 5,
    num_classes: int = 10,
    *,
    voxel_size: Sequence[float] = (0.075, 0.075, 0.2),
    point_cloud_range: Sequence[float] = (
        -54.0,
        -54.0,
        -5.0,
        54.0,
        54.0,
        3.0,
    ),
    head_class_groups: Sequence[Sequence[int]],
    feature_map_stride: int,
    channels: Sequence[int] = (16, 32, 64, 128, 128),
    shared_conv_channels: int = 128,
    head_kernel_size: int = 1,
    num_hm_conv: int = 2,
    use_bias_before_norm: bool = True,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: DetectionModel
VoxelNeXt fully sparse 3D object detector (packed point format).
Reference: VoxelNeXt: Fully Sparse VoxelNet for 3D Object Detection and Tracking (Chen et al., 2023). Reference implementation: dvlab-research/VoxelNeXt (ported via open-mmlab/OpenPCDet, cbgs_voxel0075_voxelnext). A residual sparse 3D backbone (VoxelResBackbone8xVoxelNeXt) collapses to a 2D BEV sparse tensor that a fully sparse multi-group head (VoxelNeXtHead) predicts boxes on directly, with no dense bird's-eye-view map. Input points carry 5 features (\(x, y, z, \text{intensity}, \Delta t\)).
Parameters:
-
in_channels(int, default:5) –Raw point feature channels including xyz (5 for nuScenes).
-
num_classes(int, default:10) –Number of foreground classes (10 for nuScenes).
-
voxel_size(Sequence[float], default:(0.075, 0.075, 0.2)) –Voxel size \((v_x, v_y, v_z)\).
-
point_cloud_range(Sequence[float], default:(-54.0, -54.0, -5.0, 54.0, 54.0, 3.0)) –Range \((x_\min, y_\min, z_\min, x_\max, y_\max, z_\max)\).
-
head_class_groups(Sequence[Sequence[int]]) –Class-index groups, one per separate head (e.g.
[[0], [1, 2], ...]). -
feature_map_stride(int) –BEV feature-map stride of the head.
-
channels(Sequence[int], default:(16, 32, 64, 128, 128)) –Per-stage channel widths of the 3D backbone.
-
shared_conv_channels(int, default:128) –Output channels of the backbone's 2D shared conv (head input).
-
head_kernel_size(int, default:1) –Kernel size of the hidden head convs.
-
num_hm_conv(int, default:2) –Number of convs in the classification (
hm) stack. -
use_bias_before_norm(bool, default:True) –Whether hidden head convs carry a bias before their norm.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable for the backbone and head.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable for the backbone and head.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
configure_backbone_3d–Build the fully sparse residual voxel backbone.
-
configure_head–Build the fully sparse multi-group detection head.
-
decode–Decode a forward output into raw candidate detections (see
VoxelNeXtHead.decode). -
reset_classifier–Replace the classification branch of the detection head for
num_classesoutputs.
Attributes:
-
num_features(int) –Channel count \(C\) of the sparse voxel features entering the head.
property 
Channel count \(C\) of the sparse voxel features entering the head.
configure_backbone_3d() -> VoxelResBackbone8xVoxelNeXt
Build the fully sparse residual voxel backbone.
configure_head() -> VoxelNeXtHead
Build the fully sparse multi-group detection head.
decode(
    out: VoxelNeXtHeadOutput, *, top_k: int = 500
) -> Detection3D
Decode a forward output into raw candidate detections (see VoxelNeXtHead.decode).