threedetr
3DETR: an end-to-end transformer detector for 3D point clouds.
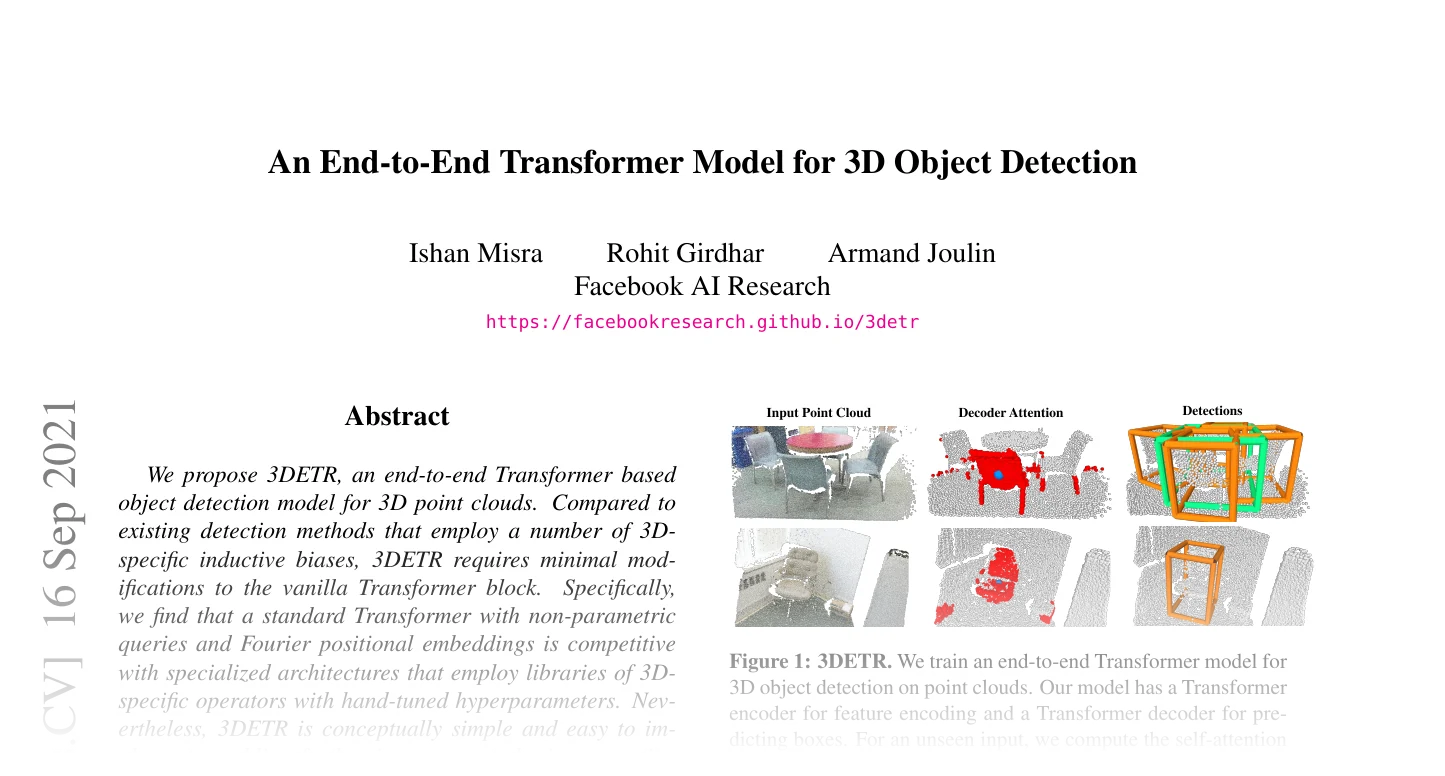
Reference: An End-to-End Transformer Model for 3D Object Detection (Misra et al., 2021). Reference implementation: facebookresearch/3detr.
Classes:
-
ThreeDETROutput–Decoded 3DETR predictions for a batch of \(B\) scenes with \(Q\) queries each (last decoder layer).
-
ThreeDETRTrainOutput–Training-mode 3DETR output: the eval
ThreeDETROutputplus the per-decoder-layer head outputs. -
PointnetSAModuleVotes–Set-abstraction tokenizer mirroring 3DETR's
PointnetSAModuleVotes(single-scale, max pool). -
TransformerEncoder–Stack of
num_layersidentical pre-norm encoder layers (no final norm), per 3DETR'svanilla. -
MaskedTransformerEncoder–3DETR-m encoder: pre-norm layers with radius self-attention masks and one interim downsampling.
-
TransformerDecoder–Stack of
num_layerspre-norm decoder layers with a shared final norm applied to every output. -
PositionEmbeddingFourier–Fixed Fourier-feature positional embedding (Tancik et al.) over normalized coordinates.
-
GenericConvMLP–\(1\times1\)-conv MLP over \((B, C, N)\) tokens, mirroring 3DETR's
GenericMLP(head / projection block). -
ThreeDETRDetection–3DETR end-to-end transformer 3D object detector (packed point format).
Bases: TypedDict
Decoded 3DETR predictions for a batch of \(B\) scenes with \(Q\) queries each (last decoder layer).
Bases: ThreeDETROutput
Training-mode 3DETR output: the eval ThreeDETROutput plus the per-decoder-layer head outputs.
aux_outputs holds one dict per decoder layer (the last entry mirrors the top-level eval fields), each carrying the normalized and unnormalized head quantities the set-prediction loss consumes, and point_cloud_dims is the per-scene \((\text{lo}, \text{hi})\) min-max extent used to normalize centers and sizes. These extra keys are present only when the model is in training mode; the eval forward returns exactly the ThreeDETROutput keys.
PointnetSAModuleVotes(
    in_channels: int,
    channels: List[int],
    *,
    num_points: int,
    radius: float,
    num_neighbors: int,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Set-abstraction tokenizer mirroring 3DETR's PointnetSAModuleVotes (single-scale, max pool).
Wraps PointNet2SetAbstraction with the reference settings: farthest-point-sampled centroids, a ball query that normalizes the relative position by the radius and concatenates it before the grouped features (pos_first), and a shared MLP whose first width already accounts for the \(3\) position channels. Returns the sampling index so the encoder can trace tokens back to the input.
Parameters:
-
in_channels(int) –Input feature channels per point (excluding xyz).
-
channels(List[int]) –Shared-MLP widths after the input layer, e.g.
[64, 128, 256]. -
num_points(int) –Number of farthest-point-sampled centroids.
-
radius(float) –Ball-query radius.
-
num_neighbors(int) –Ball-query neighbor cap.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
TransformerEncoder(
    embed_dim: int,
    num_heads: int,
    mlp_dim: int,
    num_layers: int,
    dropout: float,
    *,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Stack of num_layers identical pre-norm encoder layers (no final norm), per 3DETR's vanilla.
Parameters:
-
embed_dim(int) –Token embedding dimension.
-
num_heads(int) –Number of attention heads.
-
mlp_dim(int) –Hidden width of the feed-forward block.
-
num_layers(int) –Number of stacked encoder layers.
-
dropout(float) –Dropout probability.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
MaskedTransformerEncoder(
    embed_dim: int,
    num_heads: int,
    mlp_dim: int,
    num_layers: int,
    dropout: float,
    *,
    masking_radius: List[float],
    interim_downsampling: PointnetSAModuleVotes,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
3DETR-m encoder: pre-norm layers with radius self-attention masks and one interim downsampling.
The first layer attends within masking_radius[0], then a set-abstraction layer halves the token count, and the remaining layers attend within the later radii. Mirrors the reference MaskedTransformerEncoder.
Parameters:
-
embed_dim(int) –Token embedding dimension.
-
num_heads(int) –Number of attention heads.
-
mlp_dim(int) –Hidden width of the feed-forward block.
-
num_layers(int) –Number of stacked encoder layers (must equal
len(masking_radius)). -
dropout(float) –Dropout probability.
-
masking_radius(List[float]) –Per-layer attention radius (a value \(\le 0\) disables masking for that layer).
-
interim_downsampling(PointnetSAModuleVotes) –Set-abstraction layer applied after the first encoder layer.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
Methods:
-
compute_mask–Builds the boolean attention mask hiding token pairs farther apart than
radius.
staticmethod [source] 
Builds the boolean attention mask hiding token pairs farther apart than radius.
Parameters:
-
pos(Tensor) –Dense token positions, shape \((B, P, 3)\).
-
radius(float) –Attention radius.
Returns:
-
Tensor–Mask of shape \((B, P, P)\),
Truewhere attention is blocked.
TransformerDecoder(
    embed_dim: int,
    num_heads: int,
    mlp_dim: int,
    num_layers: int,
    dropout: float,
    *,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Stack of num_layers pre-norm decoder layers with a shared final norm applied to every output.
Mirrors the reference 3DETR decoder with return_intermediate=True: each layer's output is normed and collected so the box heads can be applied per layer (only the last is kept at eval).
Parameters:
-
embed_dim(int) –Token embedding dimension.
-
num_heads(int) –Number of attention heads.
-
mlp_dim(int) –Hidden width of the feed-forward block.
-
num_layers(int) –Number of stacked decoder layers.
-
dropout(float) –Dropout probability.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
Bases: Module
Fixed Fourier-feature positional embedding (Tancik et al.) over normalized coordinates.
Mirrors 3DETR's PositionEmbeddingCoordsSine(pos_type="fourier"): coordinates are min-max normalized to \([0, 1]\) against the per-scene point-cloud range, scaled by \(2\pi\), projected by a fixed Gaussian matrix and mapped through sine/cosine.
Parameters:
-
d_pos(int) –Output embedding dimension (must be even).
-
d_in(int, default:3) –Input coordinate dimension.
GenericConvMLP(
    in_channels: int,
    hidden_channels: List[int],
    out_channels: int,
    *,
    norm: Union[str, Callable, None] = None,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    dropout: float = 0.0,
    hidden_bias: bool = False,
    out_bias: bool = True,
    out_use_norm: bool = False,
    out_use_act: bool = False,
)
Bases: Module
\(1\times1\)-conv MLP over \((B, C, N)\) tokens, mirroring 3DETR's GenericMLP (head / projection block).
Each hidden layer is a Conv1d optionally followed by batch norm, activation and dropout; the output layer is a bare Conv1d (optionally with norm and activation). The reference uses this both for the encoder-to-decoder projection (norm + activation on the output) and for every box head (dropout, no output norm).
Parameters:
-
in_channels(int) –Input channel count.
-
hidden_channels(List[int]) –Hidden layer widths.
-
out_channels(int) –Output channel count.
-
norm(Union[str, Callable, None], default:None) –Hidden-layer normalization type or callable (applied to each hidden layer).
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
dropout(float, default:0.0) –Dropout probability after each hidden layer (0 disables).
-
hidden_bias(bool, default:False) –Whether hidden convolutions carry a bias.
-
out_bias(bool, default:True) –Whether the output convolution carries a bias.
-
out_use_norm(bool, default:False) –Whether to apply the hidden norm to the output as well.
-
out_use_act(bool, default:False) –Whether to apply the activation to the output as well.
ThreeDETRDetection(
    in_channels: int,
    num_classes: int,
    *,
    num_heading_bins: int,
    num_queries: int,
    preencoder_num_points: int = 2048,
    encoder_type: str = "vanilla",
    encoder_embed_dim: int = 256,
    encoder_num_heads: int = 4,
    encoder_feedforward_channels: int = 128,
    encoder_depth: int = 3,
    encoder_dropout: float = 0.1,
    decoder_embed_dim: int = 256,
    decoder_num_heads: int = 4,
    decoder_feedforward_channels: int = 256,
    decoder_depth: int = 8,
    decoder_dropout: float = 0.1,
    mlp_dropout: float = 0.3,
    preenc_radius: float = 0.2,
    preenc_nsample: int = 64,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: DetectionModel
3DETR end-to-end transformer 3D object detector (packed point format).
Reference: An End-to-End Transformer Model for 3D Object Detection (Misra et al., 2021). Reference implementation: facebookresearch/3detr.
A set-abstraction tokenizer downsamples the cloud to a fixed set of point tokens, a transformer encoder (vanilla, or masked with one interim downsampling for 3DETR-m) refines them, a fixed number of object queries are farthest-point-sampled from the encoder tokens, and a transformer decoder attends them against the encoder memory. Five MLP heads decode each query into a class, center, size and heading. Box centers and sizes are predicted in a per-scene min-max normalized frame and unnormalized against the point-cloud extent.
Parameters:
-
in_channels(int) –Input feature channels per point excluding xyz (\(0\) for xyz-only, \(3\) for RGB).
-
num_classes(int) –Number of semantic classes (the class head adds one background slot).
-
num_heading_bins(int) –Heading-angle bins (\(1\) for axis-aligned ScanNet, \(12\) for oriented SUN RGB-D).
-
num_queries(int) –Number of object queries (decoded boxes) per scene.
-
preencoder_num_points(int, default:2048) –Token count after the set-abstraction tokenizer.
-
encoder_type(str, default:'vanilla') –"vanilla"(encoder keepspreencoder_num_pointstokens) or"masked"(3DETR-m: radius attention masks plus one interim downsampling to \(\text{preenc\_npoints} // 2\)). -
encoder_embed_dim(int, default:256) –Encoder token dimension.
-
encoder_num_heads(int, default:4) –Encoder attention heads.
-
encoder_feedforward_channels(int, default:128) –Encoder feed-forward width.
-
encoder_depth(int, default:3) –Encoder layers.
-
encoder_dropout(float, default:0.1) –Encoder dropout.
-
decoder_embed_dim(int, default:256) –Decoder token dimension.
-
decoder_num_heads(int, default:4) –Decoder attention heads.
-
decoder_feedforward_channels(int, default:256) –Decoder feed-forward width.
-
decoder_depth(int, default:8) –Decoder layers.
-
decoder_dropout(float, default:0.1) –Decoder dropout.
-
mlp_dropout(float, default:0.3) –Dropout inside each box head.
-
preenc_radius(float, default:0.2) –Tokenizer ball-query radius.
-
preenc_nsample(int, default:64) –Tokenizer ball-query neighbor cap.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable for the convolutional blocks (tokenizer, projection, heads).
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
configure_pre_encoder–Build the set-abstraction tokenizer.
-
configure_encoder–Build the transformer encoder (masked with one interim downsampling for 3DETR-m).
-
configure_encoder_to_decoder_projection–Build the projection from encoder tokens to the decoder dimension.
-
configure_pos_embedding–Build the Fourier position embedding.
-
configure_query_projection–Build the query projection.
-
configure_decoder–Build the transformer decoder.
-
configure_mlp_heads–Build the per-query class, center, size and heading heads.
-
run_encoder–Tokenizes the point cloud with the pre-encoder and runs the masked transformer encoder.
-
get_query_embeddings–Samples the query positions among the encoder tokens and embeds them into decoder queries.
-
decode–Decode a forward output into raw per-query detections (no NMS, threshold, or filtering).
Attributes:
-
num_features(int) –Channel count \(C\) of the encoder tokens entering the decoder.
property 
Channel count \(C\) of the encoder tokens entering the decoder.
configure_pre_encoder() -> PointnetSAModuleVotes
Build the set-abstraction tokenizer.
Build the transformer encoder (masked with one interim downsampling for 3DETR-m).
configure_encoder_to_decoder_projection() -> GenericConvMLP
Build the projection from encoder tokens to the decoder dimension.
configure_pos_embedding() -> PositionEmbeddingFourier
Build the Fourier position embedding.
configure_query_projection() -> GenericConvMLP
Build the query projection.
configure_decoder() -> TransformerDecoder
Build the transformer decoder.
run_encoder(
    x: OptTensor,
    pos: Tensor,
    batch: Tensor,
    idx: OptTensor = None,
) -> Tuple[Tensor, Tensor]
Tokenizes the point cloud with the pre-encoder and runs the masked transformer encoder.
Parameters:
-
x(OptTensor) –Packed point features, shape \((N, C)\), or
Noneto use the positions. -
pos(Tensor) –Packed point positions, shape \((N, 3)\).
-
batch(Tensor) –Per-point scene index, shape \((N,)\).
-
idx(OptTensor, default:None) –Optional pre-computed sampling indices for the pre-encoder.
Returns:
-
Tuple[Tensor, Tensor]–The token positions of shape \((B, P, 3)\) and the token features of shape \((P, B, C)\).
get_query_embeddings(
    enc_xyz: Tensor,
    point_cloud_dims: Tuple[Tensor, Tensor],
    query_idx: OptTensor = None,
) -> Tuple[Tensor, Tensor]
Samples the query positions among the encoder tokens and embeds them into decoder queries.
Parameters:
-
enc_xyz(Tensor) –Encoder token positions, shape \((B, P, 3)\).
-
point_cloud_dims(Tuple[Tensor, Tensor]) –Per-scene minimum and maximum corners, used to normalize the positional embedding.
-
query_idx(OptTensor, default:None) –Optional pre-computed query indices. Farthest point sampling is used when
None.
Returns:
-
Tuple[Tensor, Tensor]–The query positions of shape \((B, Q, 3)\) and the query embeddings of shape \((B, C, Q)\).
decode(out: ThreeDETROutput) -> Detection3D
Decode a forward output into raw per-query detections (no NMS, threshold, or filtering).
Builds one oriented box per query, scores it by objectness, and labels it by the argmax semantic class. The angle head predicts negated angles, so the decoded heading is the negated angle_continuous, matching the dataset / metric \((c_x, c_y, c_z, d_x, d_y, d_z, \theta)\) counter-clockwise convention. The result is the full unfiltered query set; the evaluation pipeline applies point-count filtering, NMS, score thresholding, and the indoor per-class expansion (driven by the returned class_probs) via the torch_pointcloud.ops.box3d utilities, reproducing 3DETR's APCalculator test protocol (exact_eval=True).
Parameters:
-
out(ThreeDETROutput) –A
ThreeDETROutputfromforward.
Returns:
-
Detection3D–Packed queries
{"boxes", "scores", "labels", "batch", "class_probs"}(PyG layout), where the -
Detection3D–per-query score is objectness, the label is the argmax semantic class, and
class_probsholds -
Detection3D–the semantic-class probabilities.
Shape
- boxes: \((B \cdot Q, 7)\)
- scores / labels / batch: \((B \cdot Q,)\)
- class_probs: \((B \cdot Q, C)\)