pointpillars
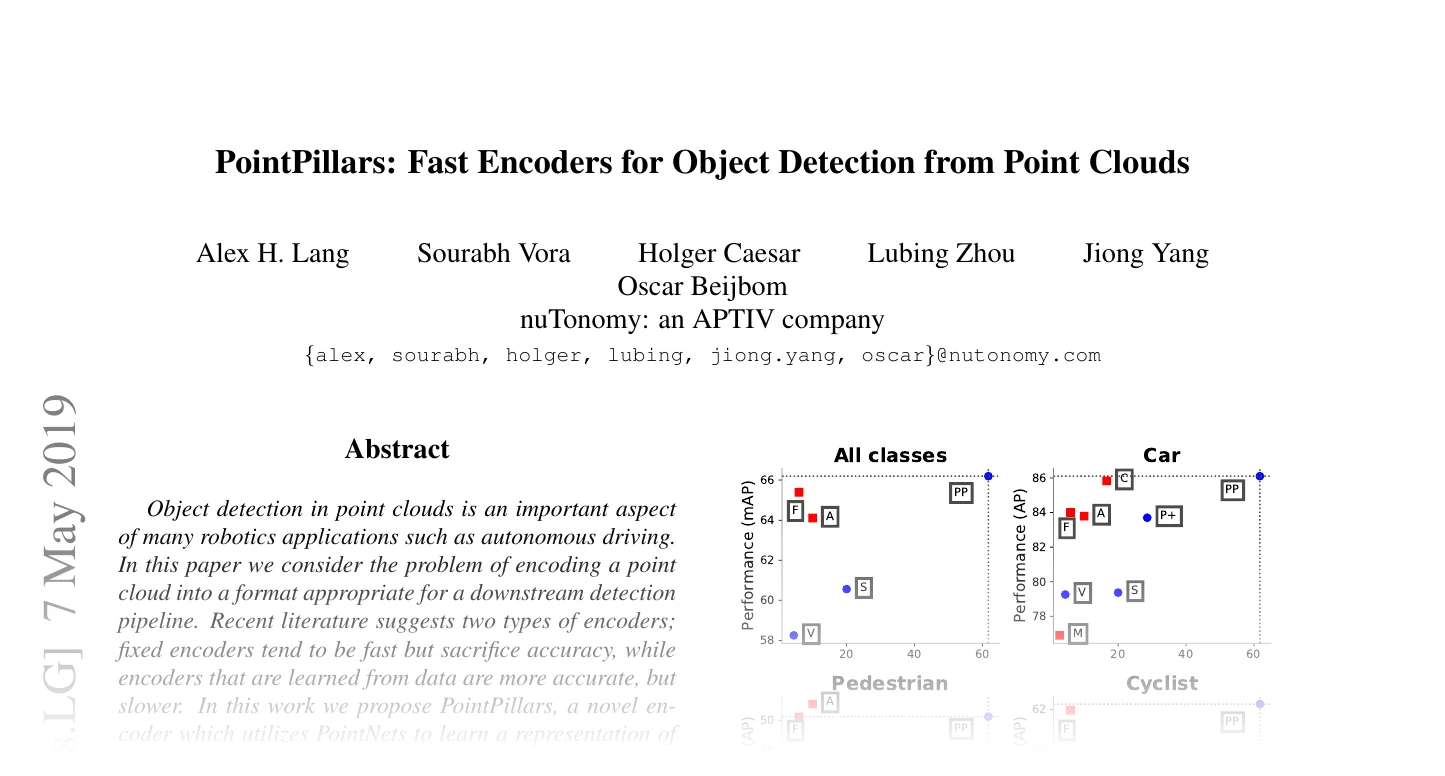
PointPillars detection models.
Classes:
-
PillarFeatureNet–Pillar feature encoder (
PillarVFE). -
PointPillarsDetection–PointPillars 3D object detector (packed point format).
-
PointPillarsMultiHeadDetection–PointPillars with a multi-group anchor head (nuScenes 10-class, packed point format).
Functions:
-
scatter_to_bev–Scatter pillar features back to a dense BEV pseudo-image.
PillarFeatureNet(
    in_channels: int,
    feat_channels: Sequence[int],
    voxel_size: Sequence[float],
    point_cloud_range: Sequence[float],
    *,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Pillar feature encoder (PillarVFE).
Augments each point in a pillar with its offset to the pillar's point-cluster mean and to the pillar center, then applies a stack of PillarFeatureLayers.
Parameters:
-
in_channels(int) –Raw point feature channels (e.g. \(4\) for \(x, y, z, \text{intensity}\)).
-
feat_channels(Sequence[int]) –Output channels of each pillar feature-net layer.
-
voxel_size(Sequence[float]) –Pillar size \((v_x, v_y, v_z)\).
-
point_cloud_range(Sequence[float]) –Range \((x_\min, y_\min, z_\min, x_\max, y_\max, z_\max)\).
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
PointPillarsDetection(
    in_channels: int = 4,
    num_classes: int = 3,
    *,
    voxel_size: Sequence[float] = (0.16, 0.16, 4.0),
    point_cloud_range: Sequence[float] = (
        0.0,
        -39.68,
        -3.0,
        69.12,
        39.68,
        1.0,
    ),
    anchor_sizes: Sequence[Sequence[float]],
    anchor_bottom_heights: Sequence[float],
    feature_map_stride: int,
    anchor_rotations: Sequence[float] = (0.0, 1.57),
    feat_channels: Sequence[int] = (64,),
    layer_nums: Sequence[int] = (3, 5, 5),
    layer_strides: Sequence[int] = (2, 2, 2),
    num_filters: Sequence[int] = (64, 128, 256),
    upsample_strides: Sequence[int] = (1, 2, 4),
    num_upsample_filters: Sequence[int] = (128, 128, 128),
    num_dir_bins: int = 2,
    dir_offset: float = 0.78539,
    dir_limit_offset: float = 0.0,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: DetectionModel
PointPillars 3D object detector (packed point format).
Reference: PointPillars: Fast Encoders for Object Detection from Point Clouds (Lang et al., 2019). Reference implementation: open-mmlab/OpenPCDet.
Parameters:
-
in_channels(int, default:4) –Raw point feature channels including xyz (e.g. \(4\) for \(x, y, z, \text{intensity}\)).
-
num_classes(int, default:3) –Number of foreground classes.
-
voxel_size(Sequence[float], default:(0.16, 0.16, 4.0)) –Pillar size \((v_x, v_y, v_z)\).
-
point_cloud_range(Sequence[float], default:(0.0, -39.68, -3.0, 69.12, 39.68, 1.0)) –Range \((x_\min, y_\min, z_\min, x_\max, y_\max, z_\max)\).
-
anchor_sizes(Sequence[Sequence[float]]) –Per-class box size \((d_x, d_y, d_z)\), one row per class.
-
anchor_bottom_heights(Sequence[float]) –Per-class anchor bottom \(z\), one per class.
-
anchor_rotations(Sequence[float], default:(0.0, 1.57)) –Yaw angles (radians) shared by all classes.
-
feature_map_stride(int) –BEV feature-map stride of the head.
-
feat_channels(Sequence[int], default:(64,)) –Output channels of the pillar feature net.
-
layer_nums(Sequence[int], default:(3, 5, 5)) –2D backbone conv counts per level.
-
layer_strides(Sequence[int], default:(2, 2, 2)) –2D backbone downsample strides per level.
-
num_filters(Sequence[int], default:(64, 128, 256)) –2D backbone channel widths per level.
-
upsample_strides(Sequence[int], default:(1, 2, 4)) –2D backbone upsample strides per level.
-
num_upsample_filters(Sequence[int], default:(128, 128, 128)) –2D backbone upsample channels per level.
-
num_dir_bins(int, default:2) –Number of direction bins in the head.
-
dir_offset(float, default:0.78539) –Direction-classifier angle offset.
-
dir_limit_offset(float, default:0.0) –Heading wrap offset used during decoding.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable for the pillar feature net and 2D backbone.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable for the pillar feature net and 2D backbone.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
configure_vfe–Build the pillar feature net.
-
configure_backbone–Build the 2D BEV backbone.
-
configure_head–Build the single-group anchor head.
-
decode–Decode a forward output into raw per-anchor detections (see
AnchorHead.decode). -
reset_classifier–Replace the classification branch of the detection head for
num_classesoutputs.
Attributes:
-
num_features(int) –Channel count \(C\) of the BEV feature map entering the head.
property 
Channel count \(C\) of the BEV feature map entering the head.
decode(out: AnchorHeadOutput) -> Detection3D
Decode a forward output into raw per-anchor detections (see AnchorHead.decode).
PointPillarsMultiHeadDetection(
    in_channels: int = 5,
    num_classes: int = 10,
    *,
    voxel_size: Sequence[float] = (0.2, 0.2, 8.0),
    point_cloud_range: Sequence[float] = (
        -51.2,
        -51.2,
        -5.0,
        51.2,
        51.2,
        3.0,
    ),
    anchor_sizes: Sequence[Sequence[float]],
    anchor_bottom_heights: Sequence[float],
    head_class_groups: Sequence[Sequence[int]],
    feature_map_stride: int,
    anchor_rotations: Sequence[float] = (0.0, 1.57),
    feat_channels: Sequence[int] = (64,),
    layer_nums: Sequence[int] = (3, 5, 5),
    layer_strides: Sequence[int] = (2, 2, 2),
    num_filters: Sequence[int] = (64, 128, 256),
    upsample_strides: Sequence[float] = (0.5, 1, 2),
    num_upsample_filters: Sequence[int] = (128, 128, 128),
    shared_conv_num_filter: int = 64,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: DetectionModel
PointPillars with a multi-group anchor head (nuScenes 10-class, packed point format).
Reference implementation: open-mmlab/OpenPCDet (cbgs_pp_multihead). Same pillar trunk as PointPillarsDetection but with an MultiGroupAnchorHead head (per-group heads, sincos + velocity box code). Input points carry 5 features (\(x, y, z, \text{intensity}, \Delta t\) from 10-sweep aggregation).
Parameters:
-
in_channels(int, default:5) –Raw point feature channels including xyz (5 for nuScenes).
-
num_classes(int, default:10) –Number of foreground classes (10 for nuScenes).
-
voxel_size(Sequence[float], default:(0.2, 0.2, 8.0)) –Pillar size \((v_x, v_y, v_z)\).
-
point_cloud_range(Sequence[float], default:(-51.2, -51.2, -5.0, 51.2, 51.2, 3.0)) –Range \((x_\min, y_\min, z_\min, x_\max, y_\max, z_\max)\).
-
anchor_sizes(Sequence[Sequence[float]]) –Per-class box size \((d_x, d_y, d_z)\), one row per class.
-
anchor_bottom_heights(Sequence[float]) –Per-class anchor bottom \(z\), one per class.
-
head_class_groups(Sequence[Sequence[int]]) –Class-index groups, one per RPN head (e.g.
[[0], [1, 2], ...]). -
anchor_rotations(Sequence[float], default:(0.0, 1.57)) –Yaw angles (radians) shared by all classes.
-
feature_map_stride(int) –BEV feature-map stride of the head.
-
feat_channels(Sequence[int], default:(64,)) –Pillar feature-net output channels.
-
layer_nums(Sequence[int], default:(3, 5, 5)) –2D backbone conv counts per level.
-
layer_strides(Sequence[int], default:(2, 2, 2)) –2D backbone downsample strides per level.
-
num_filters(Sequence[int], default:(64, 128, 256)) –2D backbone channel widths per level.
-
upsample_strides(Sequence[float], default:(0.5, 1, 2)) –2D backbone upsample factors per level (may be < 1).
-
num_upsample_filters(Sequence[int], default:(128, 128, 128)) –2D backbone upsample channels per level.
-
shared_conv_num_filter(int, default:64) –Channels of the head's shared conv.
-
act(Union[str, Callable, None], default:'relu') –Activation type or callable for the pillar feature net, 2D backbone and head.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Extra activation arguments.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization type or callable for the pillar feature net, 2D backbone and head.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Extra normalization arguments.
Methods:
-
configure_vfe–Build the pillar feature net.
-
configure_backbone–Build the 2D BEV backbone.
-
configure_head–Build the multi-group anchor head.
-
decode–Decode a forward output into raw per-anchor detections (see
MultiGroupAnchorHead.decode). -
reset_classifier–Replace the classification branch of the detection head for
num_classesoutputs.
Attributes:
-
num_features(int) –Channel count \(C\) of the BEV feature map entering the head.
property 
Channel count \(C\) of the BEV feature map entering the head.
configure_head() -> MultiGroupAnchorHead
Build the multi-group anchor head.
decode(out: AnchorHeadMultiOutput) -> Detection3D
Decode a forward output into raw per-anchor detections (see MultiGroupAnchorHead.decode).
scatter_to_bev(
    pillar_features: Tensor,
    voxel_indices: Tensor,
    batch_size: int,
    grid_size: Tuple[int, int, int],
) -> Tensor
Scatter pillar features back to a dense BEV pseudo-image.
Stateless scatter of per-pillar features onto a dense bird's-eye-view canvas indexed by each pillar's \((y, x)\) voxel grid index. The channel count is taken from pillar_features.
Parameters:
-
pillar_features(Tensor) –Per-pillar features of shape \((P, C)\).
-
voxel_indices(Tensor) –Per-pillar voxel indices of shape \((P, 4)\) with columns \((\text{batch}, z, y, x)\) and \(z = 0\).
-
batch_size(int) –Number of samples \(B\) in the batch.
-
grid_size(Tuple[int, int, int]) –Voxel grid size \((n_x, n_y, n_z)\) with \(n_z = 1\).
Returns:
-
Tensor–Dense BEV pseudo-image of shape \((B, C, n_y, n_x)\).
Shape
- Input: \((P, C)\) and \((P, 4)\).
- Output: \((B, C, n_y, n_x)\).
Example
import torch
from torch_pointcloud.models.pointpillars import scatter_to_bev

pillar_features = torch.randn(120, 64)
voxel_indices = torch.zeros(120, 4, dtype=torch.long)
voxel_indices[:, 2] = torch.randint(0, 496, (120,))
voxel_indices[:, 3] = torch.randint(0, 432, (120,))
bev = scatter_to_bev(pillar_features, voxel_indices, batch_size=1, grid_size=(432, 496, 1))
print(bev.shape)