point_bert
Point-BERT classification models, discrete VAE tokenizer, and masked pretraining transformer.
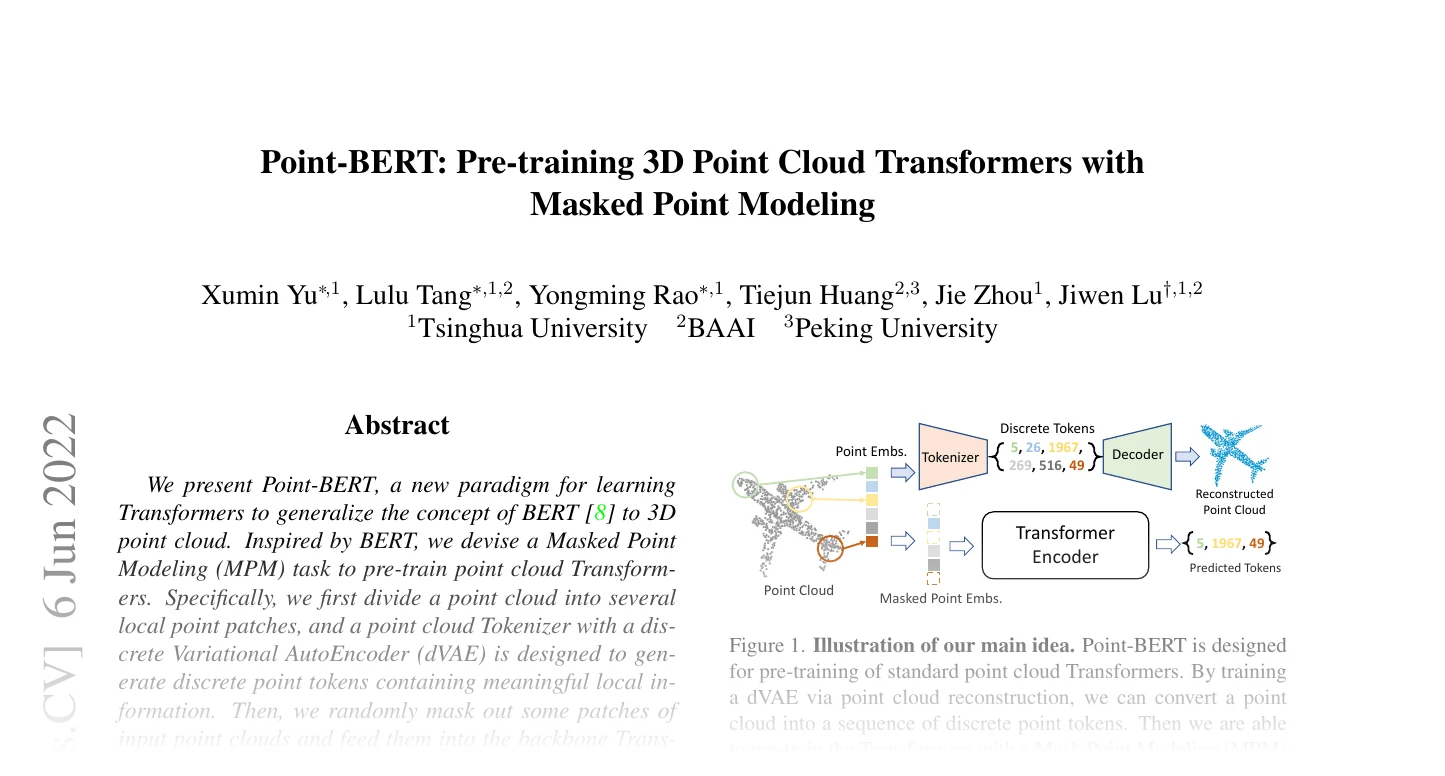
Classes:
-
PointBERTEncoder–Point-BERT transformer backbone.
-
PointBERTClassification–Point-BERT classification model.
-
PointBERTPretraining–Point-BERT masked point modeling backbone (pretrain).
-
TokenDGCNN–DGCNN feature-propagation block of the Point-BERT dVAE tokenizer.
-
FoldingDecoder–Folding reconstruction decoder of the Point-BERT dVAE.
-
PointBERTDiscreteVAE–Point-BERT discrete VAE point tokenizer.
PointBERTEncoder(
    embed_dim: int = 384,
    depth: int = 12,
    num_heads: int = 6,
    num_groups: int = 64,
    group_size: int = 32,
    encoder_dims: int = 256,
    in_channels: int = 0,
    token_local_channels: Sequence[int] = (128, 256),
    token_global_channels: Sequence[int] = (512,),
    pos_embed_channels: Sequence[int] = (128,),
    drop_path: float = 0.1,
    spatial_dim: int = 3,
    act: Union[str, Callable, None] = "gelu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = LayerNorm,
    norm_kwargs: Optional[Dict[str, Any]] = None,
    token_act: Union[str, Callable, None] = "relu",
    token_act_kwargs: Optional[Dict[str, Any]] = None,
    token_norm: Union[str, Callable, None] = "batch_norm",
    token_norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Point-BERT transformer backbone.
Implements the backbone of Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling, adapted from lulutang0608/Point-BERT.
The backbone groups the cloud into patches (FPS + KNN), embeds each patch into a token with a mini-PointNet (PointTokenizer), bridges to the transformer dimension with a linear layer, prepends a class token, adds a learned positional embedding of the patch centers, and applies a standard pre-norm transformer encoder. Optional per-point features x are gathered per patch and concatenated to the centered coordinates before the tokenizer.
Parameters:
-
embed_dim(int, default:384) –The transformer dimension \(d\).
-
depth(int, default:12) –The number of transformer blocks.
-
num_heads(int, default:6) –The number of attention heads.
-
num_groups(int, default:64) –The number of patches \(G\).
-
group_size(int, default:32) –The number of points \(M\) per patch.
-
encoder_dims(int, default:256) –The token-embedding dimension before the linear bridge.
-
in_channels(int, default:0) –The number of per-point feature channels concatenated to the coordinates (\(0\) for coordinates only).
-
token_local_channels(Sequence[int], default:(128, 256)) –Hidden widths of the tokenizer's per-point MLP.
-
token_global_channels(Sequence[int], default:(512,)) –Hidden widths of the tokenizer's per-patch MLP.
-
pos_embed_channels(Sequence[int], default:(128,)) –Hidden widths of the positional-embedding MLP.
-
drop_path(float, default:0.1) –The stochastic depth rate (identity at eval).
-
spatial_dim(int, default:3) –The number of spatial dimensions of the coordinates.
-
act(Union[str, Callable, None], default:'gelu') –The activation used in the transformer MLPs.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the activation.
-
norm(Union[str, Callable, None], default:LayerNorm) –The normalization used in the transformer blocks.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the normalization.
-
token_act(Union[str, Callable, None], default:'relu') –The activation used in the token encoder.
-
token_act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the token-encoder activation.
-
token_norm(Union[str, Callable, None], default:'batch_norm') –The normalization used in the token encoder.
-
token_norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the token-encoder normalization.
Shape
- Input: \((N, C)\) or
None, \((N, 3)\) and \((N,)\). - Output: \((B, G + 1, d)\) (token 0 is the class token).
Example
PointBERTClassification(
    in_channels: int,
    num_classes: int,
    *,
    embed_dim: int = 384,
    depth: int = 12,
    num_heads: int = 6,
    num_groups: int = 64,
    group_size: int = 32,
    encoder_dims: int = 256,
    token_local_channels: Sequence[int] = (128, 256),
    token_global_channels: Sequence[int] = (512,),
    pos_embed_channels: Sequence[int] = (128,),
    drop_path: float = 0.1,
    spatial_dim: int = 3,
    act: Union[str, Callable, None] = "gelu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = LayerNorm,
    norm_kwargs: Optional[Dict[str, Any]] = None,
    head_act: Union[str, Callable, None] = "relu",
    dropout: float = 0.5,
    head_channels: Optional[
        Union[int, Sequence[int]]
    ] = 256,
)
Bases: ClassificationModel
Point-BERT classification model.
Implements the finetuning model of Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling, adapted from lulutang0608/Point-BERT.
A PointBERTEncoder backbone followed by a 2-layer MLP head. The global feature concatenates the class token with the max-pooled patch tokens, so the head input dimension is \(2d\).
Parameters:
-
in_channels(int) –The number of per-point feature channels concatenated to the coordinates (\(0\) for coordinates only).
-
num_classes(int) –The number of output classes.
-
embed_dim(int, default:384) –The transformer dimension \(d\).
-
depth(int, default:12) –The number of transformer blocks.
-
num_heads(int, default:6) –The number of attention heads.
-
num_groups(int, default:64) –The number of patches \(G\).
-
group_size(int, default:32) –The number of points \(M\) per patch.
-
encoder_dims(int, default:256) –The token-embedding dimension before the linear bridge.
-
token_local_channels(Sequence[int], default:(128, 256)) –Hidden widths of the tokenizer's per-point MLP.
-
token_global_channels(Sequence[int], default:(512,)) –Hidden widths of the tokenizer's per-patch MLP.
-
pos_embed_channels(Sequence[int], default:(128,)) –Hidden widths of the positional-embedding MLP.
-
drop_path(float, default:0.1) –The stochastic depth rate (identity at eval).
-
spatial_dim(int, default:3) –The number of spatial dimensions of the coordinates.
-
act(Union[str, Callable, None], default:'gelu') –The activation used in the transformer MLPs.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the activation.
-
norm(Union[str, Callable, None], default:LayerNorm) –The normalization used in the transformer blocks.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the normalization.
-
head_act(Union[str, Callable, None], default:'relu') –The activation used in the classification head.
-
dropout(float, default:0.5) –The dropout rate of the classification head.
-
head_channels(Optional[Union[int, Sequence[int]]], default:256) –The hidden width(s) of the classification head.
Shape
- Input: \((N, 3)\) and \((N,)\).
- Output: \((B, \text{num\_classes})\).
Example
Methods:
-
configure_encoder–Build the
PointBERTEncoderbackbone.
Attributes:
-
num_features(int) –Channel count \(C\) of the pooled features entering the head.
property 
Channel count \(C\) of the pooled features entering the head.
configure_encoder() -> PointBERTEncoder
Build the PointBERTEncoder backbone.
PointBERTPretraining(
    in_channels: int,
    *,
    embed_dim: int = 384,
    depth: int = 12,
    num_heads: int = 6,
    num_groups: int = 64,
    group_size: int = 32,
    encoder_dims: int = 256,
    token_local_channels: Sequence[int] = (128, 256),
    token_global_channels: Sequence[int] = (512,),
    pos_embed_channels: Sequence[int] = (128,),
    num_tokens: int = 8192,
    cls_dim: int = 512,
    mask_ratio: Tuple[float, float] = (0.25, 0.45),
    drop_path: float = 0.1,
    spatial_dim: int = 3,
    act: Union[str, Callable, None] = "gelu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = LayerNorm,
    norm_kwargs: Optional[Dict[str, Any]] = None,
    token_act: Union[str, Callable, None] = "relu",
    token_act_kwargs: Optional[Dict[str, Any]] = None,
    token_norm: Union[str, Callable, None] = "batch_norm",
    token_norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: PretrainingModel
Point-BERT masked point modeling backbone (pretrain).
Implements the masked transformer (transformer_q) of Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling, adapted from lulutang0608/Point-BERT.
It embeds patches and, in training mode, replaces a contiguous block of patch tokens (a ratio drawn uniformly from mask_ratio, centered on a random patch) with a learned mask token while keeping their positional embeddings. It then runs the transformer and exposes a token-classification head (lm_head, predicting dVAE codebook ids) and a contrastive class head (cls_head). In eval mode no tokens are masked. The MoCo / cutmix machinery of the full pretraining objective is omitted; this module is the reusable encoder that downstream finetuning loads.
Parameters:
-
in_channels(int) –The number of per-point feature channels concatenated to the coordinates (\(0\) for coordinates only).
-
embed_dim(int, default:384) –The transformer dimension \(d\).
-
depth(int, default:12) –The number of transformer blocks.
-
num_heads(int, default:6) –The number of attention heads.
-
num_groups(int, default:64) –The number of patches \(G\).
-
group_size(int, default:32) –The number of points \(M\) per patch.
-
encoder_dims(int, default:256) –The token-embedding dimension before the linear bridge.
-
token_local_channels(Sequence[int], default:(128, 256)) –Hidden widths of the tokenizer's per-point MLP.
-
token_global_channels(Sequence[int], default:(512,)) –Hidden widths of the tokenizer's per-patch MLP.
-
pos_embed_channels(Sequence[int], default:(128,)) –Hidden widths of the positional-embedding MLP.
-
num_tokens(int, default:8192) –The dVAE vocabulary size predicted by
lm_head. -
cls_dim(int, default:512) –The contrastive head output dimension.
-
mask_ratio(Tuple[float, float], default:(0.25, 0.45)) –Lower / upper bounds of the block-masking ratio.
-
drop_path(float, default:0.1) –The stochastic depth rate (identity at eval).
-
spatial_dim(int, default:3) –The number of spatial dimensions of the coordinates.
-
act(Union[str, Callable, None], default:'gelu') –The activation used in the transformer MLPs and the contrastive head.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the activation.
-
norm(Union[str, Callable, None], default:LayerNorm) –The normalization used in the transformer blocks.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the normalization.
-
token_act(Union[str, Callable, None], default:'relu') –The activation used in the token encoder.
-
token_act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the token-encoder activation.
-
token_norm(Union[str, Callable, None], default:'batch_norm') –The normalization used in the token encoder.
-
token_norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the token-encoder normalization.
Shape
- Input: \((N, 3)\) and \((N,)\).
- Output: a dict with
cls_feature\((B, \text{cls\_dim})\) andlogits\((B, G, \text{num\_tokens})\).
Example
Methods:
-
configure_encoder–Build the mini-PointNet token encoder embedding each patch.
-
configure_reduce_dim–Build the linear bridge from the token-embedding dimension to the transformer dimension.
-
configure_pos_embed–Build the positional-embedding MLP mapping patch centers to the transformer dimension.
-
configure_blocks–Build the transformer blocks with a linearly scaled stochastic-depth schedule.
-
configure_lm_head–Build the token-classification head predicting dVAE codebook ids.
-
configure_cls_head–Build the contrastive class-token head.
configure_encoder() -> PointPatchEmbed
Build the mini-PointNet token encoder embedding each patch.
Build the linear bridge from the token-embedding dimension to the transformer dimension.
Build the positional-embedding MLP mapping patch centers to the transformer dimension.
Build the transformer blocks with a linearly scaled stochastic-depth schedule.
TokenDGCNN(
    in_channels: int,
    out_channels: int,
    act: Union[str, Callable, None] = "leaky_relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "group_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
DGCNN feature-propagation block of the Point-BERT dVAE tokenizer.
Implements the DGCNN of Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling, adapted from lulutang0608/Point-BERT.
Operates on the \(G\) patch tokens treated as a point set in token-feature space: it stacks four EdgeConv layers (KNN with \(k = 4\) over the patch centers, edge features, group-norm, leaky-relu, max over neighbors), concatenates the four levels, and projects to the output channel. The edge layers are genuine 2D convolutions over \((B, C, k, N)\) and use Conv2dBlock; the input projection and the final fusion are per-point shared Linear maps (the group-norm of the final fusion still reduces over channels and points on the \((B, C_\text{out}, G)\) layout). Used twice in the dVAE: before the codebook (dgcnn_1) and after (dgcnn_2).
Parameters:
-
in_channels(int) –The input token-feature dimension.
-
out_channels(int) –The output token-feature dimension.
-
act(Union[str, Callable, None], default:'leaky_relu') –The activation used in the edge layers and the final fusion.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the activation.
-
norm(Union[str, Callable, None], default:'group_norm') –The normalization used in the edge layers and the final fusion.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the normalization.
Shape
- Input: features \((B, G, C_\text{in})\) and centers \((B, G, 3)\).
- Output: \((B, G, C_\text{out})\).
Example
FoldingDecoder(
    in_channels: int,
    num_fine: int,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: Module
Folding reconstruction decoder of the Point-BERT dVAE.
Implements the folding decoder of Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling, adapted from lulutang0608/Point-BERT.
A per-token global feature is decoded to a coarse point set with a fully-connected MLP, then folded to a fine point set with a \(1 \times 1\) convolution conditioned on a \(2 \times 2\) grid.
Parameters:
-
in_channels(int) –The per-token feature dimension fed to the decoder.
-
num_fine(int) –The number of fine points \(N\) reconstructed per patch.
-
act(Union[str, Callable, None], default:'relu') –The activation used in the coarse MLP and the folding convolution.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the activation.
-
norm(Union[str, Callable, None], default:'batch_norm') –The normalization used in the folding convolution.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the normalization.
Shape
- Input: \((B, G, C_\text{in})\).
- Output: coarse \((B, G, N // 4, 3)\) and fine \((B, G, N, 3)\).
Example
PointBERTDiscreteVAE(
    in_channels: int,
    *,
    num_groups: int = 64,
    group_size: int = 32,
    encoder_dims: int = 256,
    token_local_channels: Sequence[int] = (128, 256),
    token_global_channels: Sequence[int] = (512,),
    num_tokens: int = 8192,
    tokens_dims: int = 256,
    decoder_dims: int = 256,
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
)
Bases: PretrainingModel
Point-BERT discrete VAE point tokenizer.
Implements the dVAE of Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling, adapted from lulutang0608/Point-BERT.
The dVAE produces the discrete point tokens used as the masked-modeling targets in Point-BERT pretraining: a mini-PointNet token encoder, a DGCNN that maps tokens to codebook logits, a learned codebook, a second DGCNN, and a folding decoder reconstructing the patches.
Parameters:
-
in_channels(int) –The number of input channels (\(0\), coordinates only).
-
num_groups(int, default:64) –The number of patches \(G\).
-
group_size(int, default:32) –The number of points \(M\) per patch.
-
encoder_dims(int, default:256) –The mini-PointNet token-embedding dimension.
-
token_local_channels(Sequence[int], default:(128, 256)) –Hidden widths of the tokenizer's per-point MLP.
-
token_global_channels(Sequence[int], default:(512,)) –Hidden widths of the tokenizer's per-patch MLP.
-
num_tokens(int, default:8192) –The codebook vocabulary size.
-
tokens_dims(int, default:256) –The codebook embedding dimension.
-
decoder_dims(int, default:256) –The dimension fed to the folding decoder.
-
act(Union[str, Callable, None], default:'relu') –The activation used in the token encoder and the folding decoder.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the token / decoder activation.
-
norm(Union[str, Callable, None], default:'batch_norm') –The normalization used in the token encoder and the folding decoder.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Keyword arguments for the token / decoder normalization.
Shape
- Input: \((N, 3)\) and \((N,)\).
- Output: a dict with
logits\((B, G, \text{num\_tokens})\) and reconstructions.
Example
Methods:
-
configure_encoder–Build the mini-PointNet token encoder embedding each patch.
-
configure_dgcnn_1–Build the DGCNN mapping patch tokens to codebook logits.
-
configure_dgcnn_2–Build the DGCNN mapping sampled codebook embeddings to decoder features.
-
configure_decoder–Build the folding decoder reconstructing each patch.
-
tokenize–Return the codebook logits of every group, without sampling or decoding them.
configure_encoder() -> PointPatchEmbed
Build the mini-PointNet token encoder embedding each patch.
configure_dgcnn_1() -> TokenDGCNN
Build the DGCNN mapping patch tokens to codebook logits.
configure_dgcnn_2() -> TokenDGCNN
Build the DGCNN mapping sampled codebook embeddings to decoder features.
configure_decoder() -> FoldingDecoder
Build the folding decoder reconstructing each patch.
Return the codebook logits of every group, without sampling or decoding them.
Parameters:
-
pos(Tensor) –Point coordinates of shape \((N, 3)\).
-
batch(Tensor) –Per-point batch index of shape \((N,)\).
Returns:
-
Tensor–Logits over the codebook of shape \((B, G, \text{num\_tokens})\).