dgcnn
DGCNN classification and segmentation models.
Classes:
-
DGCNNEncoderBlock–EdgeConv block: rebuilds a \(k\)-nearest-neighbor graph in feature space and runs an MLP over the edges.
-
DGCNNEncoder–Stack of
DGCNNEncoderBlockblocks whose outputs are concatenated into a single per-point feature. -
DGCNNClassification–Classification model as described in the paper
-
DGCNNSegmentation–Semantic segmentation model as described in the paper
-
DGCNNPartSegmentation–Part segmentation model as described in the paper
DGCNNEncoderBlock(
    in_channels: int,
    out_channels: Union[int, Sequence[int]],
    num_neighbors: int,
    aggr: AggrType = "max",
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    act_first: bool = False,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
    bias: Union[bool, Sequence[bool]] = True,
)
Bases: Module
EdgeConv block: rebuilds a \(k\)-nearest-neighbor graph in feature space and runs an MLP over the edges.
Pass x_knn to build the graph from another tensor than the features, typically the raw coordinates.
DGCNNEncoder(
    channels: Sequence[Union[int, Sequence[int]]],
    num_neighbors: Union[int, Sequence[int]],
    aggr: AggrType = "max",
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    act_first: bool = False,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
    bias: bool = True,
)
Bases: Module
Stack of DGCNNEncoderBlock blocks whose outputs are concatenated into a single per-point feature.
Attributes:
-
out_channels_per_block(Tuple[int, ...]) –Output channel count of each block.
-
out_channels(int) –Channel count \(C\) of the concatenated block outputs.
DGCNNClassification(
    in_channels: int,
    num_classes: int,
    *,
    spatial_dim: int = 3,
    stnet_local_channels: Optional[Sequence[int]] = None,
    stnet_global_channels: Optional[Sequence[int]] = None,
    head_channels: Optional[
        Union[int, Sequence[int]]
    ] = None,
    channels: Sequence[int],
    proj_channels: Optional[int] = None,
    num_neighbors: Union[int, Sequence[int]],
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    act_first: bool = False,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
    bias: bool = True,
    dropout: float = 0.0,
    global_pool: PoolLike | Sequence[PoolLike] = "max",
)
Bases: ClassificationModel
Classification model as described in the paper "Dynamic Graph CNN for Learning on Point Clouds" by Yue Wang, Yongbin Sun, Ziwei Liu, Sanjay E. Sarma, Michael M. Bronstein, Justin M. Solomon.
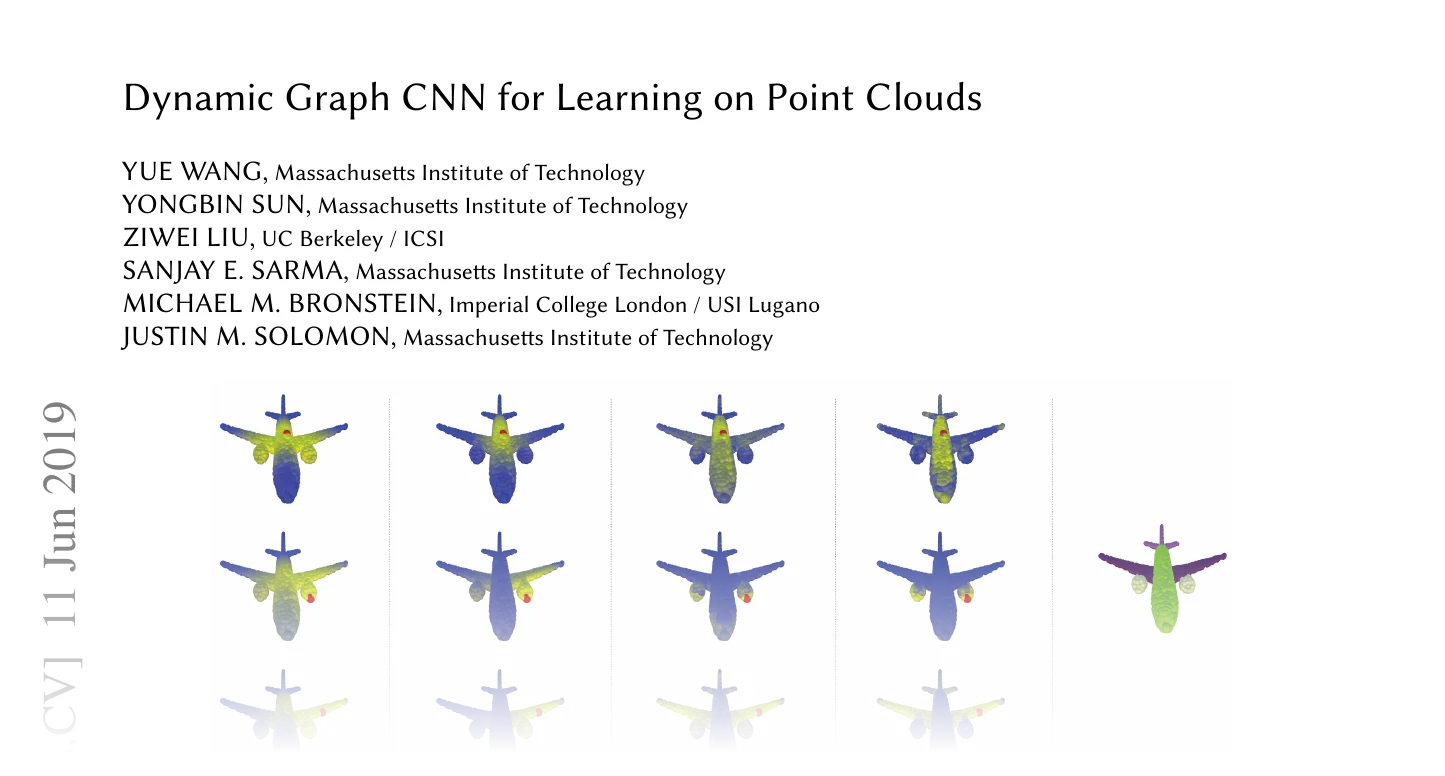
DGCNN introduces the EdgeConv operator, which computes features on dynamically constructed k-nearest neighbor (k-NN) graphs at each layer. Graphs are recomputed in the learned feature space, allowing the network to capture both local geometric relationships and long-range semantic structures.
Parameters:
-
in_channels(int) –Number of input channels.
-
num_classes(int) –Number of output classes.
-
spatial_dim(int, default:3) –Spatial dimension of the input point cloud.
-
stnet_local_channels(Optional[Sequence[int]], default:None) –List of channels for the local spatial transformer network. If None, the spatial transformer network is not used.
-
stnet_global_channels(Optional[Sequence[int]], default:None) –List of channels for the global spatial transformer network. If None, the spatial transformer network is not used.
-
channels(Sequence[int]) –List of channels for each encoder block.
-
proj_channels(Optional[int], default:None) –If set, projects the concatenated encoder features through an MLP of this width before pooling. Matches the
conv5layer in the original DGCNN paper. -
head_channels(Optional[Union[int, Sequence[int]]], default:None) –List of channels for each head block.
-
num_neighbors(Union[int, Sequence[int]]) –Maximum number of neighbors for each encoder block.
-
act(Union[str, Callable, None], default:'relu') –Activation function.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Additional arguments for the activation function.
-
act_first(bool, default:False) –Whether to apply activation before normalization.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization layer type.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Additional arguments for the normalization layer.
-
bias(bool, default:True) –Whether to use bias in linear / MLP layers.
-
dropout(float, default:0.0) –Dropout probability before the classification head.
-
global_pool(PoolLike | Sequence[PoolLike], default:'max') –Global pooling operation for final feature aggregation.
Methods:
-
configure_stnet–Build the spatial transformer aligning the input coordinates, or
Nonewhen its channels are unset. -
configure_encoder–Build the
DGCNNEncoderbackbone. -
configure_proj–Build the projection MLP applied before pooling, or
Nonewhenproj_channelsis unset.
Attributes:
-
num_features(int) –Channel count \(C\) of the pooled features entering the head.
DGCNNSegmentation(
    in_channels: int,
    num_classes: int,
    *,
    spatial_dim: int = 3,
    stnet_local_channels: Optional[Sequence[int]] = None,
    stnet_global_channels: Optional[Sequence[int]] = None,
    proj_channels: int = 1024,
    channels: Sequence[Union[int, Sequence[int]]],
    head_channels: Optional[
        Union[int, Sequence[int]]
    ] = None,
    num_neighbors: Union[int, Sequence[int]],
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    act_first: bool = False,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
    bias: bool = True,
    dropout: float = 0.0,
)
Bases: SemanticSegmentationModel
Semantic segmentation model as described in the paper "Dynamic Graph CNN for Learning on Point Clouds" by Yue Wang, Yongbin Sun, Ziwei Liu, Sanjay E. Sarma, Michael M. Bronstein, Justin M. Solomon.
DGCNN introduces the EdgeConv operator, which computes features on dynamically constructed k-nearest neighbor (k-NN) graphs at each layer. Graphs are recomputed in the learned feature space, allowing the network to capture both local geometric relationships and long-range semantic structures.
Parameters:
-
in_channels(int) –Number of input channels.
-
num_classes(int) –Number of output classes.
-
spatial_dim(int, default:3) –Spatial dimension of the input point cloud.
-
stnet_local_channels(Optional[Sequence[int]], default:None) –List of channels for the local spatial transformer network. If None, the spatial transformer network is not used.
-
stnet_global_channels(Optional[Sequence[int]], default:None) –List of channels for the global spatial transformer network. If None, the spatial transformer network is not used.
-
proj_channels(int, default:1024) –Number of channels for the projection layer after the encoder.
-
channels(Sequence[Union[int, Sequence[int]]]) –List of channels for each encoder block.
-
head_channels(Optional[Union[int, Sequence[int]]], default:None) –List of channels for each head block.
-
num_neighbors(Union[int, Sequence[int]]) –Maximum number of neighbors for each encoder block.
-
act(Union[str, Callable, None], default:'relu') –Activation function.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Additional arguments for the activation function.
-
act_first(bool, default:False) –Whether to apply activation before normalization.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization layer type.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Additional arguments for the normalization layer.
-
bias(bool, default:True) –Whether to use bias in linear / MLP layers.
-
dropout(float, default:0.0) –Dropout probability before the classification head.
Methods:
-
configure_stnet–Build the spatial transformer aligning the input coordinates, or
Nonewhen its channels are unset. -
configure_encoder–Build the
DGCNNEncoderbackbone. -
configure_proj–Build the projection MLP producing the global feature.
-
forward_decoder–Decode encoder features back to per-point resolution.
Attributes:
-
num_features(int) –Channel count \(C\) entering the head: encoder features plus the broadcast global feature.
property 
Channel count \(C\) entering the head: encoder features plus the broadcast global feature.
configure_stnet() -> Optional[TNet]
Build the spatial transformer aligning the input coordinates, or None when its channels are unset.
Decode encoder features back to per-point resolution.
Canonical signature: forward_decoder(x, ..., intermediates), consuming the output of forward_features and returning per-point features \((N, C)\). Models whose encoder already emits per-point features (DGCNN, PointNet) have no decoder and raise NotImplementedError.
DGCNNPartSegmentation(
    in_channels: int,
    num_classes: int,
    *,
    num_categories: int,
    cat_embed_channels: int = 64,
    spatial_dim: int = 3,
    stnet_edge_channels: Optional[Sequence[int]] = None,
    stnet_local_channels: Optional[Sequence[int]] = None,
    stnet_global_channels: Optional[Sequence[int]] = None,
    stnet_num_neighbors: int = 20,
    proj_channels: int = 1024,
    channels: Sequence[Union[int, Sequence[int]]],
    head_channels: Optional[
        Union[int, Sequence[int]]
    ] = None,
    num_neighbors: Union[int, Sequence[int]],
    act: Union[str, Callable, None] = "relu",
    act_kwargs: Optional[Dict[str, Any]] = None,
    act_first: bool = False,
    norm: Union[str, Callable, None] = "batch_norm",
    norm_kwargs: Optional[Dict[str, Any]] = None,
    bias: bool = True,
    dropout: float = 0.0,
)
Bases: PartSegmentationModel
Part segmentation model as described in the paper "Dynamic Graph CNN for Learning on Point Clouds" by Yue Wang, Yongbin Sun, Ziwei Liu, Sanjay E. Sarma, Michael M. Bronstein, Justin M. Solomon.
Extends the DGCNN encoder with a category-conditioned global feature branch for part-level segmentation (e.g. ShapeNet parts).
Parameters:
-
in_channels(int) –Number of input channels.
-
num_classes(int) –Number of output part classes (across all categories).
-
num_categories(int) –Number of object categories for the category embedding.
-
cat_embed_channels(int, default:64) –Number of channels for the category embedding.
-
spatial_dim(int, default:3) –Spatial dimension of the input point cloud.
-
stnet_edge_channels(Optional[Sequence[int]], default:None) –Hidden channels for the DynamicTNet EdgeConv MLP. If None, the spatial transformer network is not used.
-
stnet_local_channels(Optional[Sequence[int]], default:None) –Channels for the DynamicTNet local (point-wise) MLP.
-
stnet_global_channels(Optional[Sequence[int]], default:None) –Channels for the DynamicTNet global MLP.
-
stnet_num_neighbors(int, default:20) –Number of kNN neighbors for the DynamicTNet.
-
proj_channels(int, default:1024) –Number of channels for the projection layer after the encoder.
-
channels(Sequence[Union[int, Sequence[int]]]) –List of channels for each encoder block.
-
head_channels(Optional[Union[int, Sequence[int]]], default:None) –List of channels for each head block.
-
num_neighbors(Union[int, Sequence[int]]) –Maximum number of neighbors for each encoder block.
-
act(Union[str, Callable, None], default:'relu') –Activation function.
-
act_kwargs(Optional[Dict[str, Any]], default:None) –Additional arguments for the activation function.
-
act_first(bool, default:False) –Whether to apply activation before normalization.
-
norm(Union[str, Callable, None], default:'batch_norm') –Normalization layer type.
-
norm_kwargs(Optional[Dict[str, Any]], default:None) –Additional arguments for the normalization layer.
-
bias(bool, default:True) –Whether to use bias in linear / MLP layers.
-
dropout(float, default:0.0) –Dropout probability in the decoder head.
Methods:
-
configure_stnet–Build the dynamic spatial transformer, or
Nonewhenstnet_edge_channelsis unset. -
configure_encoder–Build the
DGCNNEncoderbackbone. -
configure_proj–Build the projection MLP producing the global feature.
-
configure_cat_embed–Build the MLP embedding the one-hot shape category.
-
forward_decoder–Decode encoder features back to per-point resolution.
Attributes:
-
num_features(int) –Channel count \(C\) entering the head: encoder features, global feature and category embedding.
property 
Channel count \(C\) entering the head: encoder features, global feature and category embedding.
configure_stnet() -> Optional[DynamicTNet]
Build the dynamic spatial transformer, or None when stnet_edge_channels is unset.
Decode encoder features back to per-point resolution.
Canonical signature: forward_decoder(x, ..., intermediates), consuming the output of forward_features and returning per-point features \((N, C)\). Models whose encoder already emits per-point features (DGCNN, PointNet) have no decoder and raise NotImplementedError.