scannet
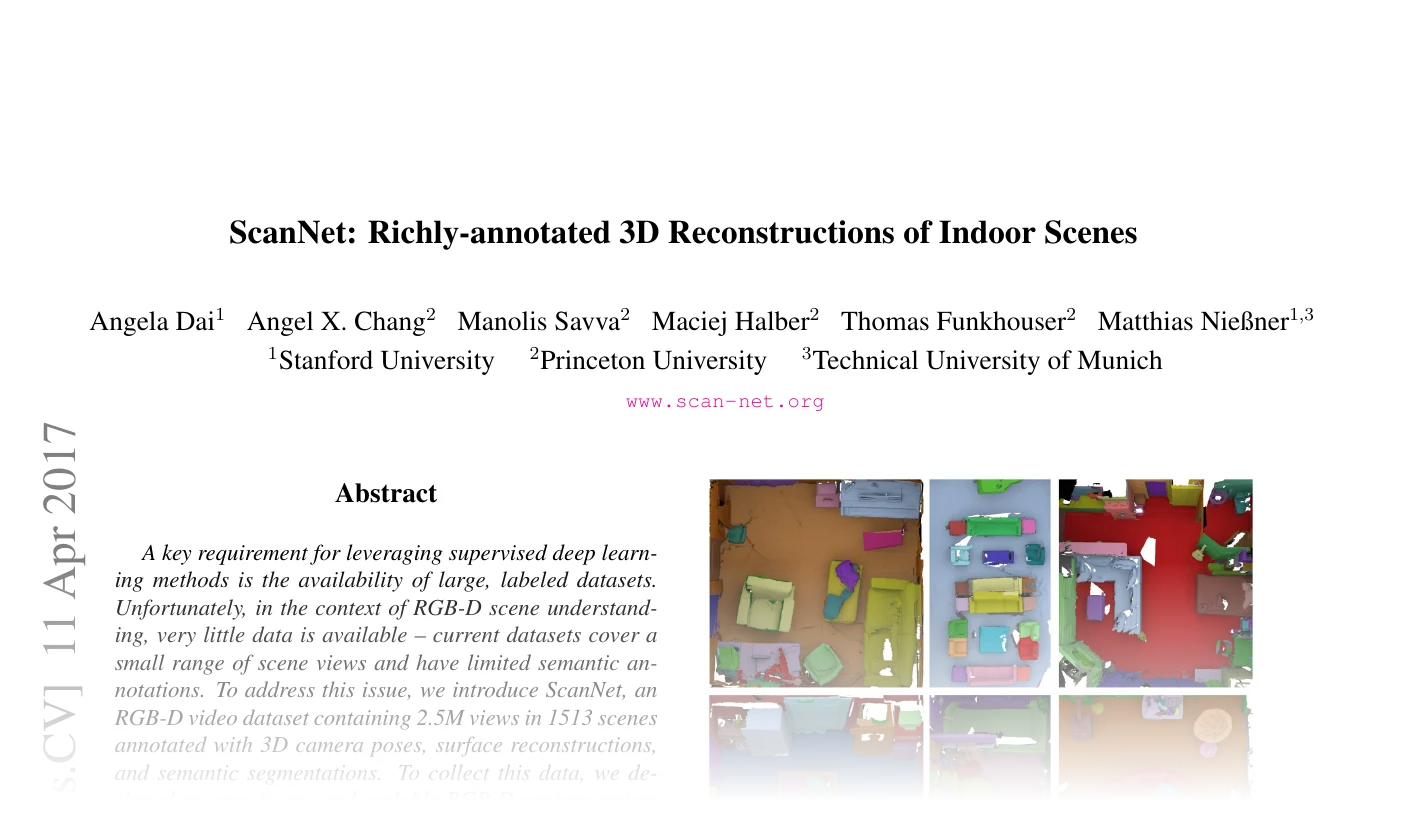
The ScanNet dataset as described in the paper ScanNet: Richly-annotated 3D Reconstructions of Indoor Scenes.
Classes:
-
ScanNetData–Per-point arrays of one ScanNet scene, as returned by
load_scannet_scene. -
ScanNet–The ScanNet dataset as described in the paper
-
ScanNet20–ScanNet restricted to the standard 20-class semantic-segmentation benchmark.
-
ScanNet200–ScanNet restricted to the 200-class benchmark, as described in the paper
Functions:
-
load_scannet_scene_mesh–Load a ScanNet PLY file and return the vertices and face.
-
load_scannet_scene_metadata–Load a ScanNet metadata file and return the metadata.
-
load_scannet_scene_aggregation_and_segs–Read per-vertex instance ids and semantic labels from aggregation + segments.
-
load_scannet_labels–Load the ScanNet labels CSV file as a
pandas.DataFrameobject. -
select_scannet_classes–Select the classes to load from the labels.
-
load_scannet_scene–Load a ScanNet scene and return the parsed points, color, normal, instance, and labels
-
tile_scannet_scene–Split a single ScanNet scene dict into fixed-size spatial blocks.
Bases: TypedDict
Per-point arrays of one ScanNet scene, as returned by load_scannet_scene.
ScanNet(
    root: PathLike,
    *,
    version: Literal["v1", "v2"] = "v2",
    split: Literal["train", "test", "val"] = "train",
    label_name: str = "nyu40class",
    label_id: str = "nyu40id",
    use_axis_alignment: bool = True,
    return_superpoint: bool = False,
    block_size: Optional[float] = None,
    block_stride: float = 0.75,
    num_nodes: int = 8192,
    min_num_nodes: int = 100,
    transform: Optional[Callable] = None,
    download: bool = False,
    force_download: bool = False,
    force_process: bool = False,
    show_progress: bool = True,
    num_workers: Optional[int] = None,
    accept_terms: bool = False,
)
Bases: PointCloudDataset
The ScanNet dataset as described in the paper ScanNet: Richly-annotated 3D Reconstructions of Indoor Scenes. This dataset contains 2.5M views in 1513 scans acquired in 707 distinct spaces. Each scan is annotated with 3D camera poses, meshes, object segmentation, and scene semantics for a total of 36,000 annotated object instance.
The dataset is available in two versions:
v1: The original dataset with 1,513 scans.v2: Improved annotation coverage to ~90% (from 63% in v1), with 100 more scans for test.
Note
It is recommended to use the v2 version, as it contains more annotated object instance. The v1 version is kept for backward compatibility.
Note
By default, the labels are taken from the nyu40class column in the labels CSV file, and the nyu40id column is used to sort the labels. Note than the class_to_idx property returns a dictionary mapping the class name to the contiguous index, and indices may not correspond to the nyu40id values.
In most cases, the loaded labels are contiguous; see class_to_idx for the mapping from class name to index (indices may not match raw nyu40id values in the source files).
Parameters:
-
root(PathLike) –The root directory of the dataset.
-
version(Literal['v1', 'v2'], default:'v2') –The version of the dataset to use.
-
split(Literal['train', 'test', 'val'], default:'train') –The split to load, one of
train,val, ortest. -
label_name(str, default:'nyu40class') –The name of the label column in the labels CSV file.
-
label_id(str, default:'nyu40id') –The name of the id column in the labels CSV file.
-
use_axis_alignment(bool, default:True) –If True, apply ScanNet's axis-alignment transform to the mesh.
-
return_superpoint(bool, default:False) –Also emit the per-point
superpointids, read from the rawscans/<scene>/<scene>_vh_clean_2.0.010000.segs.jsonmesh segmentation (requires the raw scans). -
block_size(Optional[float], default:None) –If set, split each scene into ground-plane blocks of this size (meters) for training.
-
block_stride(float, default:0.75) –Stride between adjacent blocks when
block_sizeis set. -
num_nodes(int, default:8192) –Number of points sampled per block (when
block_sizeis set) or per scene. -
min_num_nodes(int, default:100) –Skip blocks with fewer than this many points.
-
transform(Optional[Callable], default:None) –A callable that transforms the data when retrieved from the dataset.
-
download(bool, default:False) –Whether to download the raw data.
-
force_download(bool, default:False) –Whether to force the download of the raw data.
-
force_process(bool, default:False) –Whether to force the processing of the raw data.
-
show_progress(bool, default:True) –Whether to show a progress bar during processing.
-
num_workers(Optional[int], default:None) –Worker processes for preprocessing, or
Nonefor sequential processing. -
accept_terms(bool, default:False) –Confirm that you have signed the ScanNet terms of use (
terms_url). When leftFalse,downloadasks for the confirmation on the terminal, once in every process that triggers the download.
Example
Assuming you have downloaded the raw dataset from https://kaldir.vc.in.tum.de/scannet/, and extracted it under data/ScanNet/raw, you can load the dataset as follows:
from torch_pointcloud.datasets import ScanNet

dataset = ScanNet(
    root="data",
    version="v2",
    split="train",
)
By default, the labels are taken from the nyu40class column in the labels CSV file, and the nyu40id column is used to map the labels to contiguous indices. You can change this by setting the label_name and label_id arguments.
For example, to use the raw_category column and the id column, you can do:
Methods:
-
read_scene–Read one processed scene directory into a sample dict, relabeled if
relabelis set.
Attributes:
-
labels(DataFrame) –The raw label table, read from the version's combined labels TSV.
-
classes(List[str]) –Class names in label order.
-
class_to_idx(Dict[str, int]) –Mapping from class name to label index.
-
relabel(Optional[Relabel]) –Transform remapping the raw segment ids to the benchmark ids, or
Nonewhen they are used as-is. -
processed_dir(str) –Path to the processed cache directory, suffixed
_noalignwhen axis alignment is off. -
processed_files(List[Path]) –Sorted list of the split's processed scene directories.
-
name(str) –Name of the dataset directory.
-
data_dir(str) –Path to the dataset directory
<root>/<name>. -
raw_dir(str) –Path to the raw download directory.
cached property 
The raw label table, read from the version's combined labels TSV.
cached property 
relabel: Optional[Relabel]
Transform remapping the raw segment ids to the benchmark ids, or None when they are used as-is.
property 
Path to the processed cache directory, suffixed _noalign when axis alignment is off.
property 
Sorted list of the split's processed scene directories.
Read one processed scene directory into a sample dict, relabeled if relabel is set.
Parameters:
-
path(Path) –Processed scene directory holding
pos.npy,color.npy,normal.npyand, when annotated,segment.npy/instance.npy.
Returns:
-
Dict[str, Any]–The scene as a
DataKeys-keyed dict of tensors plus itsDataKeys.SCENEid.
ScanNet20(
    root: PathLike,
    *,
    version: Literal["v1", "v2"] = "v2",
    split: Literal["train", "test", "val"] = "train",
    use_axis_alignment: bool = True,
    return_superpoint: bool = False,
    block_size: Optional[float] = None,
    block_stride: float = 0.75,
    num_nodes: int = 8192,
    min_num_nodes: int = 100,
    transform: Optional[Callable] = None,
    download: bool = False,
    force_download: bool = False,
    force_process: bool = False,
    show_progress: bool = True,
    num_workers: Optional[int] = None,
    accept_terms: bool = False,
)
Bases: ScanNet
ScanNet restricted to the standard 20-class semantic-segmentation benchmark.
A thin wrapper over ScanNet that fixes the label columns to nyu40class / nyu40id and exposes the official 20-class benchmark label set (wall, floor, cabinet, ..., otherfurniture) plus the <unk> ignore class at index \(0\). The relabel transform, applied while loading, maps the raw NYU40 segment ids onto these contiguous benchmark indices; points outside the 20 classes map to <unk>. The processed cache lives in processed_20/ so it never collides with the base ScanNet or ScanNet200 caches.
Parameters:
-
root(PathLike) –The root directory of the dataset.
-
version(Literal['v1', 'v2'], default:'v2') –The version of the dataset to use.
-
split(Literal['train', 'test', 'val'], default:'train') –The split to load, one of
train,val, ortest. -
use_axis_alignment(bool, default:True) –If True, apply ScanNet's axis-alignment transform to the mesh.
-
return_superpoint(bool, default:False) –Also emit the per-point
superpointids, read from the rawscans/<scene>/<scene>_vh_clean_2.0.010000.segs.jsonmesh segmentation (requires the raw scans). -
block_size(Optional[float], default:None) –If set, split each scene into ground-plane blocks of this size (meters) for training.
-
block_stride(float, default:0.75) –Stride between adjacent blocks when
block_sizeis set. -
num_nodes(int, default:8192) –Number of points sampled per block (when
block_sizeis set) or per scene. -
min_num_nodes(int, default:100) –Skip blocks with fewer than this many points.
-
transform(Optional[Callable], default:None) –A callable that transforms the data when retrieved from the dataset.
-
download(bool, default:False) –Whether to download the raw data.
-
force_download(bool, default:False) –Whether to force the download of the raw data.
-
force_process(bool, default:False) –Whether to force the processing of the raw data.
-
show_progress(bool, default:True) –Whether to show a progress bar during processing.
-
num_workers(Optional[int], default:None) –Worker processes for preprocessing, or
Nonefor sequential processing. -
accept_terms(bool, default:False) –Confirm that you have signed the ScanNet terms of use (
terms_url). When leftFalse,downloadasks for the confirmation on the terminal, once in every process that triggers the download.
Example
Assuming you have downloaded the raw dataset from https://kaldir.vc.in.tum.de/scannet/ and extracted it under data/ScanNet/raw, you can load the benchmark labels as follows:
Methods:
-
read_scene–Read one processed scene directory into a sample dict, relabeled if
relabelis set.
Attributes:
-
name(str) –Name of the dataset directory (shared with
ScanNet). -
processed_dir(str) –Path to the processed cache directory, suffixed
_20for the 20-class benchmark. -
classes(List[str]) –Class names in label order.
-
relabel(Relabel) –Transform remapping the raw segment ids to the 20 benchmark ids.
-
data_dir(str) –Path to the dataset directory
<root>/<name>. -
raw_dir(str) –Path to the raw download directory.
-
labels(DataFrame) –The raw label table, read from the version's combined labels TSV.
-
class_to_idx(Dict[str, int]) –Mapping from class name to label index.
-
processed_files(List[Path]) –Sorted list of the split's processed scene directories.
property 
Path to the processed cache directory, suffixed _20 for the 20-class benchmark.
cached property 
relabel: Relabel
Transform remapping the raw segment ids to the 20 benchmark ids.
cached property 
The raw label table, read from the version's combined labels TSV.
property 
Sorted list of the split's processed scene directories.
Read one processed scene directory into a sample dict, relabeled if relabel is set.
Parameters:
-
path(Path) –Processed scene directory holding
pos.npy,color.npy,normal.npyand, when annotated,segment.npy/instance.npy.
Returns:
-
Dict[str, Any]–The scene as a
DataKeys-keyed dict of tensors plus itsDataKeys.SCENEid.
ScanNet200(
    root: PathLike,
    *,
    version: Literal["v1", "v2"] = "v2",
    split: Literal["train", "test", "val"] = "train",
    use_axis_alignment: bool = True,
    return_superpoint: bool = False,
    block_size: Optional[float] = None,
    block_stride: float = 0.75,
    num_nodes: int = 8192,
    min_num_nodes: int = 100,
    transform: Optional[Callable] = None,
    download: bool = False,
    force_download: bool = False,
    force_process: bool = False,
    show_progress: bool = True,
    num_workers: Optional[int] = None,
    accept_terms: bool = False,
)
Bases: ScanNet
ScanNet restricted to the 200-class benchmark, as described in the paper Language-Grounded Indoor 3D Semantic Segmentation in the Wild.
A thin wrapper over ScanNet that reads the fine-grained raw_category / id label columns and exposes the 200-class benchmark label set plus the <unk> ignore class at index \(0\). The relabel transform, applied while loading, maps the raw category ids onto contiguous benchmark indices; categories outside the 200 classes map to <unk>. The processed cache lives in processed_200/ so it never collides with the base ScanNet or ScanNet20 caches.
Parameters:
-
root(PathLike) –The root directory of the dataset.
-
version(Literal['v1', 'v2'], default:'v2') –The version of the dataset to use.
-
split(Literal['train', 'test', 'val'], default:'train') –The split to load, one of
train,val, ortest. -
use_axis_alignment(bool, default:True) –If True, apply ScanNet's axis-alignment transform to the mesh.
-
return_superpoint(bool, default:False) –Also emit the per-point
superpointids, read from the rawscans/<scene>/<scene>_vh_clean_2.0.010000.segs.jsonmesh segmentation (requires the raw scans). -
block_size(Optional[float], default:None) –If set, split each scene into ground-plane blocks of this size (meters) for training.
-
block_stride(float, default:0.75) –Stride between adjacent blocks when
block_sizeis set. -
num_nodes(int, default:8192) –Number of points sampled per block (when
block_sizeis set) or per scene. -
min_num_nodes(int, default:100) –Skip blocks with fewer than this many points.
-
transform(Optional[Callable], default:None) –A callable that transforms the data when retrieved from the dataset.
-
download(bool, default:False) –Whether to download the raw data.
-
force_download(bool, default:False) –Whether to force the download of the raw data.
-
force_process(bool, default:False) –Whether to force the processing of the raw data.
-
show_progress(bool, default:True) –Whether to show a progress bar during processing.
-
num_workers(Optional[int], default:None) –Worker processes for preprocessing, or
Nonefor sequential processing. -
accept_terms(bool, default:False) –Confirm that you have signed the ScanNet terms of use (
terms_url). When leftFalse,downloadasks for the confirmation on the terminal, once in every process that triggers the download.
Example
Assuming you have downloaded the raw dataset from https://kaldir.vc.in.tum.de/scannet/ and extracted it under data/ScanNet/raw, you can load the benchmark labels as follows:
Methods:
-
read_scene–Read one processed scene directory into a sample dict, relabeled if
relabelis set.
Attributes:
-
name(str) –Name of the dataset directory (shared with
ScanNet). -
processed_dir(str) –Path to the processed cache directory, suffixed
_200for the 200-class benchmark. -
classes(List[str]) –Class names in label order.
-
relabel(Relabel) –Transform remapping the raw segment ids to the 200 benchmark ids.
-
data_dir(str) –Path to the dataset directory
<root>/<name>. -
raw_dir(str) –Path to the raw download directory.
-
labels(DataFrame) –The raw label table, read from the version's combined labels TSV.
-
class_to_idx(Dict[str, int]) –Mapping from class name to label index.
-
processed_files(List[Path]) –Sorted list of the split's processed scene directories.
property 
Path to the processed cache directory, suffixed _200 for the 200-class benchmark.
cached property 
relabel: Relabel
Transform remapping the raw segment ids to the 200 benchmark ids.
cached property 
The raw label table, read from the version's combined labels TSV.
property 
Sorted list of the split's processed scene directories.
Read one processed scene directory into a sample dict, relabeled if relabel is set.
Parameters:
-
path(Path) –Processed scene directory holding
pos.npy,color.npy,normal.npyand, when annotated,segment.npy/instance.npy.
Returns:
-
Dict[str, Any]–The scene as a
DataKeys-keyed dict of tensors plus itsDataKeys.SCENEid.
Load a ScanNet PLY file and return the vertices and face.
Parameters:
-
file_path(PathLike) –The path to the PLY file.
Returns:
-
Tuple[Tensor, Tensor]–The vertices and face.
Examples:
Load a ScanNet metadata file and return the metadata.
Parameters:
-
meta_path(PathLike) –The path to the metadata file, usually saved as
data/ScanNet/raw/v2/scans/{scan_id}/{scan_id}.txt.
Returns:
-
Dict[str, Any]–The metadata.
Examples:
>>> meta = load_scannet_scene_metadata(
...     "data/ScanNet/raw/v2/scans/scene0000_00/scene0000_00.txt"
... )  # doctest: +SKIP
>>> meta.keys()  # doctest: +SKIP
dict_keys(['axisAlignment', 'colorToDepthExtrinsics', 'colorHeight', 'colorWidth', 'depthHeight', 'depthWidth',
 'fx_color', 'fy_color', 'mx_color', 'my_color', 'numColorFrames', 'numDepthFrames', 'numIMUmeasurements',
 'sceneType'])
load_scannet_scene_aggregation_and_segs(
    aggregation_path: PathLike,
    segs_path: PathLike,
    label_to_idx: Optional[Dict[str, int]] = None,
) -> Tuple[Tensor, Optional[Tensor]]
Read per-vertex instance ids and semantic labels from aggregation + segments.
Parameters:
-
aggregation_path(PathLike) –Path to the aggregation JSON file.
-
segs_path(PathLike) –Path to the segments JSON file.
-
label_to_idx(Optional[Dict[str, int]], default:None) –Optional mapping from
raw_categorystring to NYU40 id (or any integer label). Built from the TSV with e.g.{row["raw_category"]: int(row["nyu40id"]) for _, row in df.iterrows()}. If provided, per-vertex semantic labels are returned. Unrecognized categories map to 0 (unlabeled).
Returns:
-
Tensor–The per-vertex instance ids (the 0-based aggregation
objectId, or-1for vertices in no -
Optional[Tensor]–segment group) and labels.
Examples:
Load the ScanNet labels CSV file as a pandas.DataFrame object.
Parameters:
-
file_path(PathLike) –Path to the labels CSV file, usually located in the
rawdirectory asdata/ScanNet/raw/metadata/scannetv2-labels.combined.tsv
Returns:
-
DataFrame–The labels as a
pandas.DataFrameobject.
Examples:
select_scannet_classes(
    labels: DataFrame,
    name: str,
    sort_by: Optional[str] = None,
    values: Union[Sequence[str], Literal["all"]] = "all",
) -> List[Any]
Select the classes to load from the labels.
Parameters:
-
labels(DataFrame) –The labels as a
pandas.DataFrameobject. -
name(str) –The name of the column in the labels to select the classes from.
-
sort_by(Optional[str], default:None) –The column to sort the labels by.
-
values(Union[Sequence[str], Literal['all']], default:'all') –The values to select from the labels.
Returns:
-
List[Any]–The selected classes.
Examples:
>>> labels = load_scannet_labels("data/ScanNet/raw/metadata/scannetv2-labels.combined.tsv")  # doctest: +SKIP
>>> classes = select_scannet_classes(labels, "raw_category", sort_by="id", values=["wall", "floor"])  # doctest: +SKIP
>>> nyu40classes = select_scannet_classes(labels, "nyu40class", sort_by="nyu40id", values="all")  # doctest: +SKIP
load_scannet_scene(
    mesh_path: PathLike,
    meta_path: Optional[PathLike] = None,
    aggregation_path: Optional[PathLike] = None,
    segments_path: Optional[PathLike] = None,
    label_to_idx: Optional[Dict[str, int]] = None,
    scene_id: Optional[str] = None,
    use_axis_alignment: bool = True,
) -> ScanNetData
Load a ScanNet scene and return the parsed points, color, normal, instance, and labels in a dictionary format.
Parameters:
-
mesh_path(PathLike) –Path to the raw mesh file, usually saved as
data/ScanNet/raw/v2/scans/{scan_id}/{scan_id}.ply. -
meta_path(Optional[PathLike], default:None) –Path to the metadata file, usually saved as
data/ScanNet/raw/v2/scans/{scan_id}/{scan_id}.txt. -
aggregation_path(Optional[PathLike], default:None) –Path to the aggregation file, usually saved as
data/ScanNet/raw/v2/scans/{scan_id}/{scan_id}.aggregation.json. -
segments_path(Optional[PathLike], default:None) –Path to the segments file, usually saved as
data/ScanNet/raw/v2/scans/{scan_id}/{scan_id}.segs.json. -
label_to_idx(Optional[Dict[str, int]], default:None) –A dictionary mapping object labels to contiguous positive indices. The labels correspond to the
raw_categorycolumn in the labels CSV file, or to thelabelkey in the aggregation JSON file. This mapping is used to map object labels to their associated target indices. -
use_axis_alignment(bool, default:True) –Whether to apply the axis alignment transformation from the scene metadata. Set to
Falseto keep the raw PLY coordinates.
Returns:
-
ScanNetData–The loaded scene.
Examples:
>>> labels_path = "data/ScanNet/raw/metadata/scannetv2-labels.combined.tsv"
>>> labels = load_scannet_labels(labels_path)  # doctest: +SKIP
>>> label_to_idx = {label: idx for idx, label in enumerate(labels["raw_category"].unique())}  # doctest: +SKIP
>>> scene_dir = "data/ScanNet/raw/v2/scans/scene0000_00"
>>> scene = load_scannet_scene(  # doctest: +SKIP
...     mesh_path=f"{scene_dir}/scene0000_00_vh_clean_2.ply",
...     meta_path=f"{scene_dir}/scene0000_00.txt",
...     aggregation_path=f"{scene_dir}/scene0000_00.aggregation.json",
...     segments_path=f"{scene_dir}/scene0000_00.segs.json",
...     label_to_idx=label_to_idx,
... )
>>> scene  # doctest: +SKIP
{'points': tensor([[...]]), 'color': tensor([[...]]), 'normal': tensor([[...]]),
 'instance': tensor([...]), 'labels': tensor([...])}}
tile_scannet_scene(
    scene: Dict[str, Any],
    block_size: float = 1.5,
    block_stride: float = 0.75,
    num_nodes: int = 8192,
    min_num_nodes: int = 100,
    scene_index: Optional[int] = None,
) -> List[Dict[str, Any]]
Split a single ScanNet scene dict into fixed-size spatial blocks.
Sweeps a \(\text{block\_size} \times \text{block\_size}\) window (full Z extent) over the scene with the given stride, matching the tiling procedure used in the DGCNN ScanNet evaluation protocol.
Parameters:
-
scene(Dict[str, Any]) –Dict with at least
DataKeys.POS(float32, \((N, 3)\)). All other tensors with a leading dimension of \(N\) are sliced in parallel. -
block_size(float, default:1.5) –Side length of each square block in meters.
-
block_stride(float, default:0.75) –Step size for the sliding window in meters.
-
num_nodes(int, default:8192) –Fixed number of nodes per block.
-
min_num_nodes(int, default:100) –Minimum number of raw nodes for a block to be kept.
-
scene_index(Optional[int], default:None) –If provided, each block will include
scene_indexandnum_scene_pointsentries.
Returns:
-
List[Dict[str, Any]]–List of dicts, one per retained block. Each block has exactly
num_nodesnodes and extra -
List[Dict[str, Any]]–scene_max(scene-level coordinate maxima, useful for downstream normalization), -
List[Dict[str, Any]]–block_center, andpoint_indicesentries.