nuscenes
nuScenes 3D object detection datasets with sweep aggregation and annotation loading helpers.
Classes:
-
NuScenes–nuScenes 3D object-detection dataset (LiDAR keyframes + LiDAR-frame ground-truth boxes).
-
NuScenesMini–nuScenes mini 3D object-detection dataset: every keyframe of the
v1.0-minirelease.
Functions:
-
read_nuscenes_table–Read one nuScenes metadata table from
<version_dir>/<name>.json. -
load_nuscenes_sweeps–Aggregate up to
max_sweepsLiDAR sweeps for a keyframe into its sensor frame. -
load_nuscenes_boxes–Convert a keyframe's global-frame annotations to LiDAR 7-DoF boxes with labels and box extras.
-
velocity_attributes–Attribute id of each detected box from its class and BEV speed (the nuScenes submission convention).
NuScenes(
    root: PathLike,
    *,
    split: Optional[NuScenesSplit] = "train",
    version: Optional[str] = None,
    max_sweeps: int = 10,
    classes: Sequence[str] = NUSCENES_DETECTION_CLASSES,
    transform: Optional[
        Callable[[Dict[str, Any]], Dict[str, Any]]
    ] = None,
    download: bool = False,
    force_download: bool = False,
    force_process: bool = False,
    show_progress: bool = True,
    num_workers: Optional[int] = None,
)
Bases: PointCloudDataset
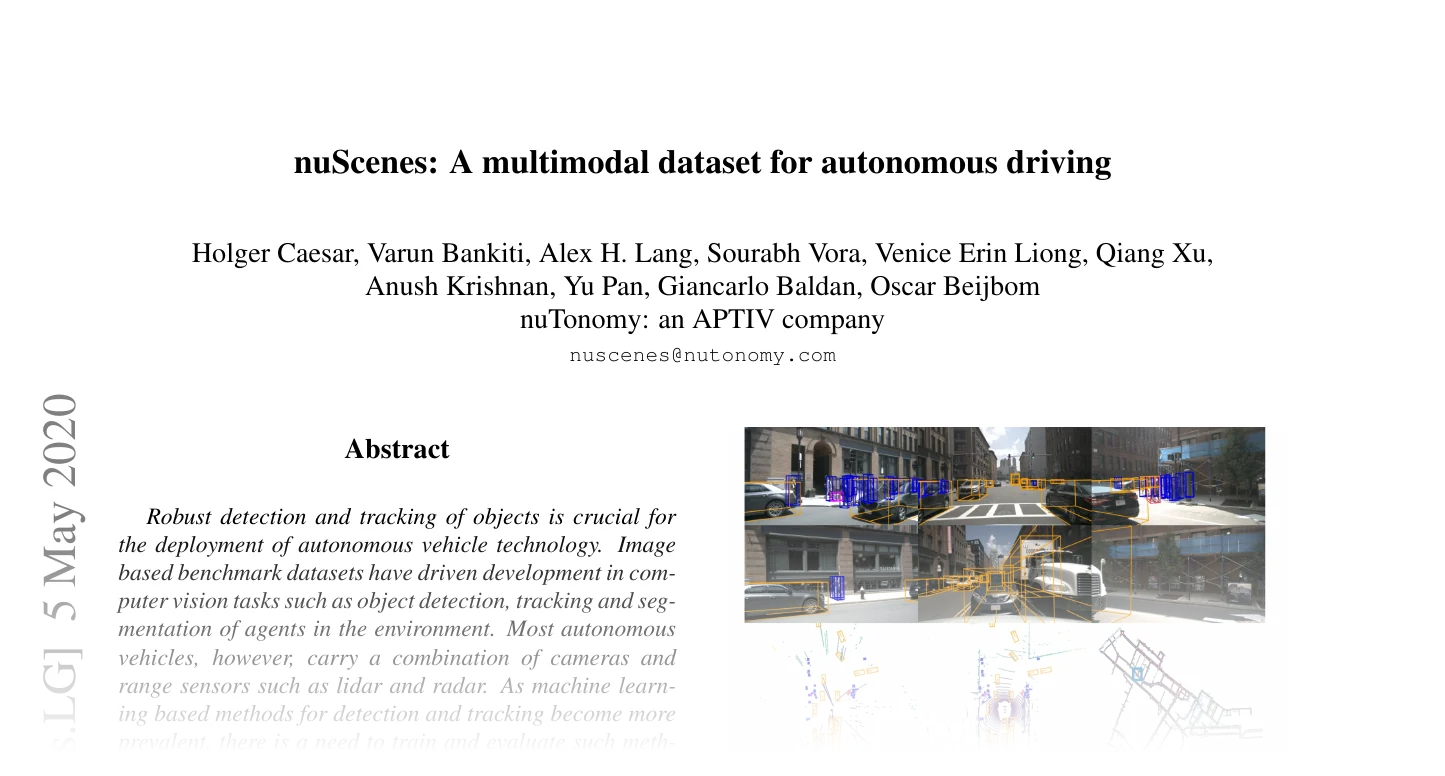
nuScenes 3D object-detection dataset (LiDAR keyframes + LiDAR-frame ground-truth boxes).
Reference: nuScenes: A multimodal dataset for autonomous driving.
Each LiDAR keyframe aggregates max_sweeps sweeps into the keyframe frame (ego-point removal + per-sweep ego/sensor transform, with a per-point time lag), and the global-frame annotations are converted to LiDAR 7-DoF boxes \((c_x, c_y, c_z, dx, dy, dz, \theta)\) mapped onto the official 10-class detection set (NUSCENES_DETECTION_CLASSES). split selects the keyframes through the official scene lists and resolves the metadata version it reads (train / val read v1.0-trainval, test reads v1.0-test, mini_train / mini_val read v1.0-mini); split=None takes every keyframe of an explicit version. The split is processed once into per-keyframe numpy files under <root>/NuScenes/processed/<version>_<split>_sweeps<max_sweeps>/, then loaded from there (the same raw -> processed -> load flow as S3DIS / ModelNet40).
Note
nuScenes cannot be downloaded automatically (it requires registration and accepting the dataset EULA). Download the metadata and every *_blobs.tgz archive of the version manually from https://www.nuscenes.org/nuscenes#download and extract them under <root>/NuScenes/raw/ so that raw/<version>/*.json, raw/samples/LIDAR_TOP/ and raw/sweeps/LIDAR_TOP/ exist; each blob archive holds a different set of scenes, so a split is complete only once all of them are extracted.
Tip
The processed cache is keyed by version, split and max_sweeps, so different sweep counts coexist. The cache also records the classes it was built with and refuses to load under a different class set; pass force_process=True to regenerate it.
Each sample is a dict:
| Key | Shape | Dtype | Description |
|---|---|---|---|
pos | \((N, 3)\) | float32 | LiDAR XYZ (sweeps aggregated into keyframe frame) |
intensity | \((N, 1)\) | float32 | LiDAR reflectance |
timestamp | \((N, 1)\) | float32 | Per-point time lag to the keyframe (seconds) |
box | \((K, 7)\) | float32 | GT boxes \((c_x, c_y, c_z, dx, dy, dz, \theta)\) |
label | \((K,)\) | int64 | Detection class index into classes |
velocity | \((K, 2)\) | float32 | Per-box LiDAR-frame BEV velocity \((v_x, v_y)\) |
num_points | \((K,)\) | int64 | Per-box LiDAR point count (num_lidar_pts) |
attribute | \((K,)\) | int64 | Index into NUSCENES_ATTRIBUTES (\(-1\) when unset) |
token | - | str | Source keyframe sample_token |
Per-box velocities are the finite difference of the annotation translation across the prev / next annotations divided by their sample-timestamp delta, computed in the global frame, rotated into the keyframe LiDAR frame, and zero when neither neighbor exists. The test split ships no annotations, so its box tensors are empty.
Parameters:
-
root(PathLike) –Dataset root; raw data is read from
<root>/NuScenes/raw/. -
split(Optional[NuScenesSplit], default:'train') –One of
NUSCENES_SPLITS("train","val","test","mini_train","mini_val"), orNonefor every keyframe ofversion. -
version(Optional[str], default:None) –Metadata version directory; resolved from
splitwhen omitted, required whensplitisNone. -
max_sweeps(int, default:10) –Total LiDAR sweeps aggregated per keyframe (keyframe + prior sweeps).
-
classes(Sequence[str], default:NUSCENES_DETECTION_CLASSES) –Foreground class names kept (order defines the label index).
-
transform(Optional[Callable[[Dict[str, Any]], Dict[str, Any]]], default:None) –Callable applied to each sample dict (e.g. the model's registered transform).
-
download(bool, default:False) –If
True, calldownload(which raises, since nuScenes needs a manual download). -
force_download(bool, default:False) –Forwarded to
downloadasforce. -
force_process(bool, default:False) –If
True, reprocess the raw data even if a processed cache exists. -
show_progress(bool, default:True) –If
True, show a progress bar while processing. -
num_workers(Optional[int], default:None) –Worker processes for processing, or
Nonefor sequential processing.
Example
Assuming the raw v1.0-trainval release is extracted under data/NuScenes/raw/:
Methods:
-
split_scenes–Scene names of
split, orNonewhen every scene ofversionbelongs to it.
Attributes:
-
processed_dir(str) –Path to the processed cache directory, one per version, split and sweep count.
-
name(str) –Name of the dataset directory.
-
data_dir(str) –Path to the dataset directory
<root>/<name>. -
raw_dir(str) –Path to the raw download directory.
property 
Path to the processed cache directory, one per version, split and sweep count.
NuScenesMini(
    root: PathLike,
    *,
    version: str = "v1.0-mini",
    max_sweeps: int = 10,
    classes: Sequence[str] = NUSCENES_DETECTION_CLASSES,
    transform: Optional[
        Callable[[Dict[str, Any]], Dict[str, Any]]
    ] = None,
    download: bool = False,
    force_download: bool = False,
    force_process: bool = False,
    show_progress: bool = True,
    num_workers: Optional[int] = None,
)
Bases: NuScenes
nuScenes mini 3D object-detection dataset: every keyframe of the v1.0-mini release.
A NuScenes preset for the ten-scene mini release (404 keyframes, no train / val split) that reads its own <root>/NuScenesMini/raw/ directory, so the mini download can live next to the full dataset. Samples and the processed cache follow NuScenes; the cache lives under <root>/NuScenesMini/processed/<version>_sweeps<max_sweeps>/.
Parameters:
-
root(PathLike) –Dataset root; raw data is read from
<root>/NuScenesMini/raw/. -
version(str, default:'v1.0-mini') –Metadata version directory (the mini split is
"v1.0-mini"). -
max_sweeps(int, default:10) –Total LiDAR sweeps aggregated per keyframe (keyframe + prior sweeps).
-
classes(Sequence[str], default:NUSCENES_DETECTION_CLASSES) –Foreground class names kept (order defines the label index).
-
transform(Optional[Callable[[Dict[str, Any]], Dict[str, Any]]], default:None) –Callable applied to each sample dict (e.g. the model's registered transform).
-
download(bool, default:False) –If
True, calldownload(which raises, since nuScenes needs a manual download). -
force_download(bool, default:False) –Forwarded to
downloadasforce. -
force_process(bool, default:False) –If
True, reprocess the raw data even if a processed cache exists. -
show_progress(bool, default:True) –If
True, show a progress bar while processing. -
num_workers(Optional[int], default:None) –Worker processes for processing, or
Nonefor sequential processing.
Example
Assuming the raw mini split is extracted under data/NuScenesMini/raw/:
Methods:
-
split_scenes–Scene names of
split, orNonewhen every scene ofversionbelongs to it.
Attributes:
-
name(str) –Name of the dataset directory.
-
data_dir(str) –Path to the dataset directory
<root>/<name>. -
raw_dir(str) –Path to the raw download directory.
-
processed_dir(str) –Path to the processed cache directory, one per version, split and sweep count.
property 
Path to the processed cache directory, one per version, split and sweep count.
load_nuscenes_sweeps(
    raw_dir: PathLike,
    record: Dict[str, Any],
    ego_pose: Dict[str, Any],
    calib: Dict[str, Any],
    sample_data: Dict[str, Any],
    max_sweeps: int,
) -> ndarray
Aggregate up to max_sweeps LiDAR sweeps for a keyframe into its sensor frame.
Each prior sweep is transformed into the keyframe frame and tagged with its time lag to the keyframe.
Parameters:
-
raw_dir(PathLike) –Dataset raw directory (sweep
filenames are resolved against it). -
record(Dict[str, Any]) –The keyframe
sample_datarecord (aLIDAR_TOPkey frame). -
ego_pose(Dict[str, Any]) –ego_posetable indexed by token. -
calib(Dict[str, Any]) –calibrated_sensortable indexed by token. -
sample_data(Dict[str, Any]) –sample_datatable indexed by token (used to walk theprevchain). -
max_sweeps(int) –Total sweeps to aggregate (keyframe + prior sweeps).
Returns:
-
ndarray–Packed points \((N, 5)\) of \((x, y, z, \text{intensity}, \Delta t)\).
load_nuscenes_boxes(
    record: Dict[str, Any],
    ego_pose: Dict[str, Any],
    calib: Dict[str, Any],
    annotations: Dict[str, List[Dict[str, Any]]],
    class_to_idx: Dict[str, int],
) -> Tuple[ndarray, ndarray, ndarray, ndarray, ndarray]
Convert a keyframe's global-frame annotations to LiDAR 7-DoF boxes with labels and box extras.
Parameters:
-
record(Dict[str, Any]) –The keyframe
sample_datarecord. -
ego_pose(Dict[str, Any]) –ego_posetable indexed by token. -
calib(Dict[str, Any]) –calibrated_sensortable indexed by token. -
annotations(Dict[str, List[Dict[str, Any]]]) –sample_annotationrecords grouped bysample_token, each carrying adetection_name(resolved detection class, orNone), a global-framevelocity\((3,)\) and anattribute_id(index intoNUSCENES_ATTRIBUTES, \(-1\) when unset). -
class_to_idx(Dict[str, int]) –Detection-class-name to label-index map; annotations whose class is absent are dropped.
Returns:
-
ndarray–Boxes \((K, 7)\) of \((c_x, c_y, c_z, dx, dy, dz, \theta)\), integer labels \((K,)\), LiDAR-frame BEV
-
ndarray–velocities \((K, 2)\), LiDAR point counts \((K,)\) and attribute ids \((K,)\).
Attribute id of each detected box from its class and BEV speed (the nuScenes submission convention).
A box faster than speed_threshold gets its class's moving attribute (vehicle.moving, cycle.with_rider, pedestrian.moving), a slower one its stationary attribute (vehicle.parked / vehicle.stopped, cycle.without_rider, pedestrian.standing); barrier and traffic_cone carry no attribute (\(-1\)).
Parameters:
-
labels(Tensor) –Detection class indices into
NUSCENES_DETECTION_CLASSES, shape \((N,)\). -
velocity(Tensor) –BEV velocities in m/s, shape \((N, 2)\).
-
speed_threshold(float, default:1.0) –Speed above which a box counts as moving.
Returns:
-
Tensor–Attribute ids into
NUSCENES_ATTRIBUTES, shape \((N,)\), \(-1\) where the class has none.